Introduction
Welcome to the world of the Linux command line.
Beneath the sleek, graphical interfaces of modern computing lies an incredibly rich, expressive, and powerful environment: the text-based command line interface (CLI). For decades, computing has evolved toward visual simplicity—drag-and-drop actions, icons, and menus designed to hide complexity. While graphical user interfaces (GUIs) make everyday tasks accessible to anyone, they also build a wall between the user and the raw capabilities of the underlying operating system.
Stepping into the command line means stepping through that wall. It shifts your role from a passive consumer of software to an active driver of your system. Rather than being constrained to the specific buttons and menus a software designer chose to provide, the command line offers direct, unmediated communication with your computer using a clear, written syntax.
What is the Linux Command Line?
At its core, the Linux command line is a text-based interface used to control a computer. Instead of pointing and clicking on graphical elements with a mouse, you type structured textual commands into a terminal, press Enter, and receive text output in response.
To understand the command line, it helps to distinguish between three terms that are often used interchangeably:
- The Terminal: This is the window or application that accepts your input and displays output. Think of the terminal as the physical screen and keyboard interface—a digital canvas for text.
- The Shell: This is the program running inside the terminal. The shell is an interpreter; it receives the commands you type, translates them into instructions the operating system’s kernel can execute, and returns the results.
- The Command Line: This is the abstract concept of interacting with an operating system through sequential lines of text commands.
In a world dominated by visual design, working in plain text can initially feel like stepping back in time. However, text is the universal currency of computing. Text is lightweight, unambiguous, and infinitely adaptable. While a graphical interface requires a visual display and manual interaction, command-line operations rely on simple strings of text that can be executed, combined, saved, and automated across virtually any system environment.
Why Use the Command Line?
If modern graphical interfaces are so intuitive, why do developers, system administrators, data scientists, and power users continue to rely heavily on text commands? The reason is simple: efficiency, control, and repeatability.
1. Unmatched Speed and Efficiency
For basic tasks, pointing and clicking works well. But as tasks become repetitive or scale in size, graphical interfaces become cumbersome. Performing an action on one file takes a few clicks; performing that same action on thousands of files scattered across nested folders via a GUI can take hours of tedious, manual labor. On the command line, complex bulk operations can often be described in a single line of text and completed in seconds.
2. Direct Control and Precision
Graphical interfaces only expose the features their developers explicitly built visual controls for. If a setting lacks a checkbox or a drop-down menu, the GUI leaves you stuck. The command line grants direct access to the entire operating system, enabling precise adjustments and configuration changes that graphical applications simply cannot match.
3. Automation and Reproducibility
One of the greatest limitations of a GUI is that actions taken inside it leave no natural trace. If you perform a complex sequence of clicks to format a document or configure a system today, you must remember every single click to repeat the process next month. Command-line interactions, because they consist of written text, can easily be recorded, shared, and saved into scripts. Once you solve a problem on the command line, you can automate that solution so it never has to be manually performed again.
4. Resource Efficiency and Remote Access
Graphical environments consume significant memory, storage, and processing power just to render windows and animations. On servers, cloud instances, embedded hardware, and remote machines across the globe, graphical interfaces are rarely installed. The command line requires minimal resources and functions seamlessly over low-bandwidth network connections, making it the standard interface for managing the servers that power the internet.
Why the Bash Shell?
While there are several different shells available in the Unix and Linux ecosystems—such as Zsh, Fish, and Ksh—the Bash shell (short for Bourne Again SHell) stands out as the standard for Linux environments.
1. The Universal Standard
Bash is the default or primary shell on almost every major Linux distribution and has served as the backbone of Unix-like operating systems for decades. Learning Bash ensures that whenever you log into a Linux server, virtual machine, or cloud instance, your skills will translate directly without needing to reconfigure or relearn your tools.
2. Powerful Scripting Capabilities
Bash is not just an interactive command interpreter; it is also a complete programming language. It supports variables, loops, conditional checks, and functions, allowing users to combine simple utilities into sophisticated automated workflows.
3. Deep Ecosystem and Community Support
Because of its longstanding dominance, Bash benefits from extensive documentation, tutorials, and community knowledge built over decades. Virtually every system administration tool, installation guide, and server script written for Linux assumes a Bash-compatible environment. Mastering Bash gives you immediate access to this vast collection of collective knowledge.
What Lies Ahead
Learning the command line is much like learning a new language. At first, the vocabulary may feel unfamiliar, and typing commands instead of clicking icons may feel slower than what you are used to.
However, as you progress through the upcoming chapters of this book, you will move step-by-step from foundational concepts to advanced system control:
- Navigating the System: Learning how to move through directories, view files, and inspect your environment entirely through text.
- Manipulating Files and Data: Mastering tools to create, modify, search, filter, and organize information with precision.
- Combining Tools: Discovering how the Linux philosophy of combining small, single-purpose utilities creates flexible, powerful workflows.
- Scripting and Automation: Turning multi-step routines into executable scripts that handle complex tasks automatically.
The command line is not an outdated relic of the past; it is the definitive toolkit of modern computing power. By learning to harness the Linux command line and the Bash shell, you are taking full control of your computing environment. Welcome aboard—let’s begin.
Chapter 1: Welcome to the Shell — Navigation and File Basics
Section 1.1: Anatomy of a Command — Structure, Options, and Arguments
Every time you type a line into the terminal and press Enter, you are communicating with the operating system using a structured syntax. To an untrained eye, command-line inputs might look like a random scramble of short abbreviations, dashes, and pathnames. However, almost every command follow a clean, predictable template:
command[options][arguments]
Understanding this basic formula transforms the terminal from a mysterious black box into an intuitive interface. Each component of this trio—the command, the option, and the argument—serves a distinct role in constructing your instruction.
1. The Command (The Action)
The command is the verb of the statement. It is the primary executable or built-in utility you are instructing the shell to run.
- What it does: It specifies what action you want to perform.
- Placement: The command always sits at the very beginning of the line.
- Examples of intent:
- Asking the system to display a list of items in a folder.
- Requesting to move a file from one directory to another.
- Instructing the terminal to display text on the screen.
- Asking the system to display a list of items in a folder.
When you type a command and hit Enter, the shell searches your system for an executable program matching that exact name. If it finds the program, it executes it; if it doesn’t, it reports that the command was not found.
2. Options (Modifying the Behavior)
Options (often called flags or switches) modify how the command carries out its task. If the command is a verb, options are the adverbs—they refine, expand, or adjust the default behavior of the action.
- What they do: They change settings, unlock hidden features, toggle formatting, or instruct the program to run in quiet or detailed modes.
- Prefixes: Options are typically preceded by one or two dashes:
- Short options: Prefixed by a single dash and usually consisting of a single letter (e.g., -l, -a, -v).
- Long options: Prefixed by double dashes and usually consisting of full words (e.g., –long, –all, –verbose). Long options are easier to read in scripts, while short options are quicker to type interactively.
- Short options: Prefixed by a single dash and usually consisting of a single letter (e.g., -l, -a, -v).
- Combining short options: Most commands allow you to group single-letter short options behind a single dash. For example, applying -a and -l together can be written as -al or -la.
Options are usually optional. If you omit them, the command runs using its default configuration.
3. Arguments (The Target)
Arguments specify what the command operates on. If the command is the verb and the options are adverbs, the argument is the direct object of the sentence.
- What they do: They provide the essential data, target targets, input files, or destinations the command needs to execute its job.
- Common values: Arguments are frequently filenames, folder paths, domain names, user accounts, or specific search text.
- Quantity: Depending on the command, you might provide zero arguments, one argument, or multiple arguments separated by spaces.
For example, if a command’s job is to copy a file, it requires two arguments: the source file you want to copy, and the target location where the copy should be placed.
Deconstructing the Anatomy in Practice
To see how these three pieces interact seamlessly, consider a few structural patterns:
Command Only
└─► ls
Command + Option
└─► ls -l
│ └── Option (Long format listing)
└── Command (List)
Command + Argument
└─► ls Documents
│ └── Argument (Target directory)
└── Command (List)
Full Anatomy: Command + Option + Argument
└─► ls -la Documents
│ │ └── Argument (Target directory)
│ └── Options (Combined: Show all hidden files + use long format)
└── Command (List)
Key Takeaways for Command Syntax
- Space Separation Matters: The shell relies strictly on whitespace (spaces or tabs) to distinguish where the command ends, where options begin, and where arguments split apart. Typing ls-l causes an error because the shell searches for a non-existent command literally named ls-l.
- Case Sensitivity: Linux environments are strictly case-sensitive. ls -a is completely different from ls -A, and target arguments like Document and document refer to two entirely different files.
- Order Flexibility: In most modern utilities, options can appear before or after arguments, but keeping options immediately after the command name before listing arguments is standard practice for clarity and readability.
Section 1.2: Navigating the Directory Tree — pwd (Print Working Directory)
Before you can move around a filesystem, you must answer one fundamental question: “Where am I right now?”
When using a graphical file manager, visual cues keep you oriented—you see a window showing your “Documents” folder inside a visual hierarchy of icons and sidebars. In the command line, there are no visual windows. Instead, you operate within a single location in the filesystem at any given time. This current location is known as your working directory (or present working directory).
To determine your exact location within the Linux directory hierarchy, you rely on one of the most fundamental utilities in the Unix ecosystem: pwd.
What is pwd?
The name pwd is an acronym for Print Working Directory. Its sole job is to write the full absolute path of your current working directory to the standard output (your terminal screen).
User Query ──► pwd
│
▼
Terminal Output: /home/username
Absolute Paths vs. Relative Paths
To understand what pwd reports, it is essential to distinguish between the two ways locations are referenced in Linux:
- Absolute Path: A complete address that traces the location from the very top of the system’s file hierarchy—the root directory, represented by a single forward slash (/). An absolute path always begins with / and specifies the exact sequence of directories to reach a target, regardless of where you are currently located.
- Relative Path: An address that specifies a location relative to where you are currently standing. It does not begin with a forward slash.
The pwd command always outputs an absolute path. No matter how deep inside nested folders you wander, pwd gives you the unambiguous, full address starting from /.
Understanding the Directory Tree Structure
Linux organizes all files and directories into a single unified hierarchical structure called a directory tree. Unlike operating systems that assign separate drive letters to different storage devices (such as C: or D: in Windows), Linux anchors everything to the root directory (/).
/ (Root)
├── bin
├── etc
├── home
│ ├── alex
│ │ ├── Documents
│ │ └── Downloads
│ └── sam
└── var
When you log into a terminal session, the system automatically places you inside your personal sandbox called your Home Directory (e.g., /home/alex). As you navigate throughout the tree, your “current working directory” shifts, but pwd remains your reliable compass.
Command Syntax and Options for pwd
While pwd is frequently run without any arguments or options, it does support two primary behavior flags that dictate how symbolic links (shortcuts) are printed:
pwd[options]
| Option | Flag Name | Description |
| -L | Logical | Prints the logical working directory, preserving any symbolic links (default behavior). |
| -P | Physical | Prints the actual physical directory path, resolving all symbolic links to their real filesystem location. |
Logical vs. Physical Paths
- Logical Path (-L): If you navigate into a folder that is actually a symlink (a pointer to another folder elsewhere on disk), running pwd -L will print the path containing the link’s name.
- Physical Path (-P): Running pwd -P bypasses the shortcut name and prints the true physical destination on disk.
Hands-on Practice & Examples
Let’s walk through several real-world scenarios to see pwd in action.
Example 1: Checking Your Home Location
When you open a new terminal session, check where you have landed:
pwd
Expected Output:
/home/username
(Note: On macOS systems, the user directory hierarchy typically resides under /Users/username instead of /home/username.)
Example 2: Verifying Location After Changing Directories
Imagine you navigate deep inside your project storage directory:
cd /var/log/nginx
pwd
Expected Output:
/var/log/nginx
Why this matters: Before executing commands that modify, delete, or create files, running pwd guarantees that you are operating in the intended directory, preventing accidental modifications in the wrong location.
Example 3: Resolving Symbolic Links (-L vs -P)
Suppose your system administrator created a quick shortcut link named /tmp/doclink that points to a deep physical folder located at /var/www/html/documents.
If you navigate to the link and inspect your path:
cd /tmp/doclink
Check the logical path (Default):- Bash
pwd -L
Output: /tmp/doclink- Check the true physical path on disk:
- Bash
pwd -P
Output: /var/www/html/documents
Summary Checklist for pwd
- [ ] pwd stands for Print Working Directory.
- [ ] It takes no required arguments and returns the absolute path of your current location.
- [ ] Absolute paths always begin at the root directory (/).
- [ ] Use -P to find the real physical path if you suspect you are inside a symbolic link/shortcut directory.
Section 1.3: Listing Directory Contents — The ls Command
Once you know where you are using pwd, the next logical question is: “What is here?”
In a graphical file manager, opening a folder instantly populates your screen with icons, thumbnails, and names representing files and subdirectories. In the command line, you need a utility that can query the filesystem and present its contents in a readable, text-based format. That utility is ls, short for “list.”
The ls command is one of the most frequently used tools in any Linux environment. Whether you are checking code files in a development repository, reviewing server configuration files, or managing system logs, ls is your primary window into the contents of a directory.
Basic Usage and Syntax
At its simplest, running ls with no options or arguments lists the contents of your current working directory:
ls
However, like most Linux commands, ls accepts both options and arguments, allowing you to tailor its output to your exact needs:
ls[options][arguments]
- Without arguments: It lists the contents of the current working directory.
- With a directory argument: It lists the contents of the specified target path without requiring you to navigate there first (e.g., ls /etc).
- With file arguments: It displays information specifically about those listed files.
Decoding the Results: The Long Listing Format (-l)
By default, a standard ls command prints filenames in a compact, multi-column format. While efficient for scanning many items quickly, it hides critical details like file sizes, permissions, ownership, and timestamps.
To reveal this hidden layer of information, you add the long format option (-l):
ls -l
When you execute ls -l, the terminal returns a structured table of data. Let’s break down every column of a typical output line:
-rw-r–r– 1 alex staff 4096 Nov 5 10:30 document.txt
| Output Segment | What It Represents | Detailed Meaning |
| -rw-r–r– | File Type and Permissions | The first character indicates the file type (- for a regular file, d for a directory, l for a symbolic link). The remaining nine characters represent read, write, and execute permissions for the owner, group, and others. |
| 1 | Link Count | The number of hard links pointing to this file or directory. For a standard file, this is usually 1. For a directory, it represents the number of subdirectories inside it. |
| alex | Owner | The user account on the system that owns the file. |
| staff | Group | The user group associated with the file, granting collective permissions to members of that group. |
| 4096 | File Size | The size of the file measured in bytes. By default, this raw number can be hard to parse for large files. |
| Nov 5 10:30 | Timestamp | The date and time when the file was last modified. |
| document.txt | Filename | The name of the file or directory. |
Essential Flags and Options for ls
The true power of ls comes from its extensive suite of options. These flags can be used individually or combined to customize how information is presented.
Common`ls`Options
| Option | Flag Name | Description |
| -l | Long Format | Displays detailed file attributes, permissions, ownership, size, and modification dates. |
| -a | All Files | Includes “hidden” files and directories. In Linux, any file or folder starting with a dot (.) is hidden by default (e.g., .bashrc, .config). |
| -h | Human-Readable | Converts raw byte sizes into easy-to-read units like KB, MB, or GB (best used alongside -l). |
| -t | Sort by Time | Sorts the output chronologically by modification time, showing the most recently modified files first. |
| -r | Reverse Order | Reverses the sorting order (useful when combined with -t to show oldest files first, or to reverse alphabetical sorting). |
| -R | Recursive | Recursively lists all contents of directories and subdirectories down the entire tree. |
| -F | Classify | Appends a trailing symbol to filenames indicating their type: / for directories, * for executable programs, and @ for symbolic links. |
Combining Flags for Enhanced Power
Linux command-line flags are designed to work together seamlessly. Instead of typing separate dashes for every option (e.g., ls -l -a -h), you can bundle short options together behind a single dash:
ls -lah
This single command tells ls to:
- Use the long listing format (-l).
- Show all files, including hidden dotfiles (-a).
- Display sizes in human-readable formats (-h).
Hands-on Practice & Examples
Let’s walk through several practical examples to see how ls operates in real-world scenarios.
Example 1: Basic Directory Listing
To see what files and folders are present in your current working directory:
ls
Typical Output:
Desktop Documents Downloads Music notes.txt scripts
Example 2: Revealing Hidden Files (-a)
Many configuration files and settings are hidden from standard listings to keep interfaces clean. To view everything, including hidden dotfiles:
ls -la
Typical Output:
total 36
drwxr-xr-x 6 alex staff 192 Nov 5 11:00 .
drwxr-xr-x 23 alex staff 736 Nov 5 09:15 ..
-rw-r–r– 1 alex staff 220 Nov 5 09:15 .bash_logout
-rw-r–r– 1 alex staff 3526 Nov 5 09:15 .bashrc
drwxr-xr-x 2 alex staff 64 Nov 5 10:00 Documents
-rw-r–r– 1 alex staff 45 Nov 5 10:30 notes.txt
(Notice the . and .. entries representing the current directory and its parent directory, alongside hidden configuration files like .bashrc.)
Example 3: Inspecting File Sizes in Human-Readable Format (-lh)
When reviewing large folders, raw byte counts are difficult to parse quickly. Combining -l with -h fixes this:
ls -lh
Typical Output:
total 1.2G
-rw-r–r– 1 alex staff 4.2K Nov 5 10:30 dataset.csv
-rw-r–r– 1 alex staff 1.1G Nov 5 11:15 archive.tar.gz
-rwxr-xr-x 1 alex staff 2.4M Nov 5 08:45 compiled_app
(Notice how file sizes are now cleanly displayed as 4.2K, 1.1G, and 2.4M instead of confusing multi-digit byte strings.)
Example 4: Sorting by Modification Time (-lt)
If you just downloaded a file or edited a script and want to find it instantly, sorting by modification time places the newest items at the top:
ls -lt
Typical Output:
total 16
-rw-r–r– 1 alex staff 12 Nov 5 11:45 recent_notes.txt
-rw-r–r– 1 alex staff 450 Nov 5 10:30 notes.txt
-rw-r–r– 1 alex staff 1024 Nov 1 14:20 old_backup.txt
Example 5: Inspecting a Remote Directory Without Changing Locations
You do not need to cd into a folder to see what is inside it. You can pass the path as an argument directly to ls:
ls -F /var/log
Typical Output:
apt/ auth.log boot.log dpkg.log nginx/ syslog
(The trailing slash / added by the -F option instantly identifies apt/ and nginx/ as directories.)
Summary Checklist for ls
- [ ] ls stands for List, used to inspect directory contents.
- [ ] Use ls -l for the long format, revealing permissions, owner, group, size, and modification date.
- [ ] Use ls -a to expose hidden files beginning with a dot (.).
- [ ] Combine flags for maximum efficiency, such as ls -lah for detailed, human-readable listings of all files.
- [ ] Pass a directory path as an argument (e.g., ls /etc) to inspect remote locations without changing your current working directory.
Section 1.4: Moving Through the Filesystem — The cd Command and Path Mechanics
Up to this point, you have learned how to check your current location using pwd and inspect what files reside around you using ls. However, a terminal session is not static; to perform meaningful work, you must be able to move freely across the filesystem.
In a graphical file manager, navigation is tactile: you double-click a folder icon, and a new window opens displaying its contents. In the command line, traversal is handled entirely through text using the cd command, an acronym for Change Directory.
Mastering cd requires more than just memorizing a three-letter command. It requires understanding the geography of the Linux filesystem and the two fundamental ways you can describe a destination: Absolute Paths and Relative Paths.
Basic Usage of cd
The syntax for the change directory command is straightforward:
cd[destination_path]
When you type cd followed by a valid directory path and press Enter, the shell updates your working directory. If the command succeeds, it typically returns no output on the screen; instead, your prompt updates to reflect your new location, or you can verify the change immediately by running pwd.
Absolute Paths vs. Relative Paths: The Core Distinction
When you instruct the shell to move to a new location, you must provide a path. How you write that path depends on whether you choose an absolute or a relative approach.
Filesystem Hierarchy:
/
└── home
└── alex
├── Documents
│ └── reports
└── Downloads
1. Absolute Paths (The GPS Coordinates)
An absolute path is a complete, uncompromised address that starts from the very top of the filesystem—the root directory, represented by a leading forward slash (/).
- How it works: An absolute path traces every single directory step required to reach the target, starting from /.
- Behavior: It works identically no matter where you are currently located in the system.
- Example: If you are currently sitting in /var/log and want to jump directly to Alex’s reports folder, you can type:
- Bash
cd /home/alex/Documents/reports
Even though you are miles away in the directory tree, the absolute path guides the shell directly to the target because it starts explicitly from the root (/).
2. Relative Paths (The Local Directions)
A relative path is an address specified relative to your current working directory. Think of it like giving someone directions starting from the street corner where they are currently standing, rather than from city hall.
- How it works: A relative path never begins with a forward slash (/). It assumes that the target folder is located inside your current directory.
- Behavior: Its effectiveness depends entirely on where you are standing. If you try to use a relative path when you are in the wrong folder, the shell will return a No such file or directory error.
- Example: Suppose your pwd reports that you are inside /home/alex. To move into the Documents folder, you simply type:
- Bash
cd Documents
Because you did not start with a slash, the shell looks inside your current location (/home/alex) for a folder named Documents.
Special Path Shortcuts and Symbols
To make navigation faster and more expressive, the Linux shell provides several universal shorthand symbols that can be passed as arguments to cd.
| Symbol / Shortcut | What It Represents | Description |
| . (Single Dot) | The Current Directory | Represents the directory you are currently standing in. While cd . essentially means “stay right here,” the single dot is frequently used in file operations to specify current-folder targets. |
| .. (Double Dot) | The Parent Directory | Represents the directory one level up in the hierarchy. Typing cd .. moves you backward out of your current folder into its containing parent. |
| ~ (Tilde) | The Home Directory | A universal shortcut representing the home directory of the currently logged-in user (e.g., /home/username). Typing cd ~ instantly transports you back home from anywhere in the system. |
| – (Hyphen) | The Previous Directory | Acts as a toggle switch. Typing cd – instantly returns you to the directory you were just in before your last jump. |
Handling Spaces and Special Characters in Paths
As you navigate through directories, you will eventually encounter folder names that contain spaces (e.g., My Documents or Project Backup 2026).
Because the shell uses whitespace (spaces) to separate commands, options, and arguments, typing cd My Documents will confuse the parser. The shell will interpret My as the destination directory and Documents as an unexpected second argument, resulting in an error:
bash: cd: My: No such file or directory
To fix this, you have two primary methods:
- Quoting: Wrap the path in single or double quotes:
- Bash
cd “My Documents”
Escaping: Precede the space with a backslash (\) to tell the shell to treat the space literally:- Bash
cd My\ Documents
(Pro-tip: Most modern shells also allow you to press the Tab key to auto-complete directory names, which automatically inserts escape characters for you!)
Comprehensive Hands-on Practice & Examples
Let’s walk through a simulated navigation session to see how absolute paths, relative paths, and special shortcuts work together in practice.
Scenario Setup:
Assume you open a new terminal session. By default, the system places you in your home directory (/home/alex).
Example 1: Moving Downward Using Relative Paths
You want to enter your Downloads folder, which is a direct subdirectory of your home folder.
pwd
# Output: /home/alex
cd Downloads
pwd
# Output: /home/alex/Downloads
Because Downloads is directly inside your current location, a simple relative path worked instantly.
Example 2: Stepping Backward Using Parent Shortcuts (..)
While inside /home/alex/Downloads, you realize you need to go into the Documents folder instead. Since Documents is a sibling to Downloads (they share the same parent folder, /home/alex), you can step up one level and back down:
pwd
# Output: /home/alex/Downloads
cd ../Documents
pwd
# Output: /home/alex/Documents
The .. moved you up to /home/alex, and Documents moved you into the target folder in a single fluid command.
Example 3: Teleporting Across the System Using Absolute Paths
You are currently deep in user documents (/home/alex/Documents), and you need to inspect system configuration files located in /etc/nginx. Instead of stepping up multiple times with .., you use an absolute path:
pwd
# Output: /home/alex/Documents
cd /etc/nginx
pwd
# Output: /etc/nginx
The absolute path (/etc/nginx) bypassed your current location entirely.
Example 4: Returning Home Instantly with the Tilde (~)
Wherever you are in the filesystem—even deep inside system directories like /var/log/apt—you can return to your home base with a single keystroke:
pwd
# Output: /var/log/apt
cd ~
pwd
# Output: /home/alex
(Note: In many Linux shells, simply typing cd by itself with no arguments achieves the exact same result as cd ~, instantly jumping you back to your home directory.)
Example 5: Toggling Between Locations with the Hyphen (–)
Suppose you are working in your home directory and decide to jump into a deep project folder:
cd /var/www/html/project_alpha/src/components
pwd
# Output: /var/www/html/project_alpha/src/components
Suddenly, you need to check something back in your home directory. You jump home:
cd ~
Now, you want to jump back to that exact deep components directory without re-typing the long path. You use the hyphen toggle:
cd –
pwd
# Output: /var/www/html/project_alpha/src/components
Typing cd – acts as a quick-switch toggle between your current and previous working directories.
Summary Checklist for cd
- [ ] cd stands for Change Directory, the primary tool for moving through the Linux filesystem.
- [ ] Absolute paths start with a forward slash (/) and trace the path from the root directory; they work from anywhere in the system.
- [ ] Relative paths do not start with a slash; they specify a destination relative to your current working directory.
- [ ] Use .. to move up one level to the parent directory, and ~ (or just cd alone) to return home.
- [ ] Use cd – to toggle back to your previous location instantly.
- [ ] Wrap paths in quotes (“…”) or use backslashes (\) if your directory names contain spaces.
Section 1.5: Shaping the Filesystem — The mkdir Command
So far, you have learned how to orient yourself with pwd, inspect your surroundings with ls, and traverse the directory tree using cd. You are operating as an explorer in an existing world. But as a user, system administrator, or developer, you will often need to build that world yourself.
When organizing projects, setting up server environments, or storing data, your first operational need is the ability to create new folders. In the Linux command line, folders are formally referred to as directories, and they are created using the mkdir command, short for Make Directory.
Basic Usage and Syntax
The syntax for mkdir is clean and intuitive. You provide the command name followed by one or more directory names you wish to create:
mkdir[options]directory_name(s)
When you execute mkdir successfully, the terminal typically returns no output; it silently and instantly constructs the requested directory on disk. You can immediately verify its creation by running ls.
The Fundamental Problem of Nesting: Why -p is Essential
Imagine you want to create a nested project structure where a folder named website sits inside a folder named 2026, which in turn sits inside a parent folder named projects:
projects/
└── 2026/
└── website/
If you type:
mkdir projects/2026/website
Assuming none of those folders currently exist, the command will fail, returning an error similar to this:
mkdir: cannot create directory ‘projects/2026/website’: No such file or directory
Why did this happen? By default, mkdir expects the parent directory (projects/2026/) to already be present before it creates the final target inside it. Without the parent existing, the command refuses to guess or build intermediate folders automatically.
The Savior Flag: –parents (or -p)
To solve this, Linux provides one of the most powerful and frequently used flags in file management: the parent flag (-p).
mkdir -p projects/2026/website
When you include -p, mkdir checks the path from left to right. If the projects folder does not exist, it creates it. If 2026 does not exist inside projects, it creates that too. Finally, it creates the website folder.
- Key Benefit: It prevents errors when parent directories are missing, and it safely does nothing (without throwing an error) if a directory you specified already exists.
Essential Options and Flags for mkdir
While -p is the most critical flag, mkdir supports a few other helpful options to control behavior and output:
Common`mkdir`Options
| Option | Flag Name | Description |
| -p, –parents | Parents | Creates any missing parent directories along the path automatically; ignores errors if directories already exist. |
| -v, –verbose | Verbose | Prints a confirmation message for every directory created, making it easy to track what the command accomplished. |
| -m, –mode=MODE | Mode / Permissions | Sets specific file access permissions (modes) on the newly created directories at the moment of creation (advanced). |
Handling Spaces and Special Characters in Directory Names
Just as we saw with the cd command, directory names that contain spaces (such as Client Files or Archive 2025) require special handling. If you type:
mkdir New Folder
The shell interprets this as a request to create two separate directories: one named New and one named Folder.
To prevent this and ensure the space is treated as part of a single name, you must either wrap the name in quotes or use an escape backslash:
- Using Quotes:
- Bash
mkdir “New Folder”
Using an Escape Backslash:- Bash
mkdir New\ Folder
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how mkdir operates across different real-world scenarios.
Example 1: Creating a Single Directory
You want to create a workspace directory named scratchpad inside your current working directory.
mkdir scratchpad
ls -F
Output:
scratchpad/
(The trailing slash / confirms that scratchpad was successfully created as a directory.)
Example 2: Creating Multiple Directories Simultaneously
Instead of running mkdir multiple times to set up separate folders, you can list multiple directory names separated by spaces in a single command:
mkdir docs source tests build
ls -F
Output:
build/ docs/ scratchpad/ source/ tests/
All four directories are created instantly side-by-side.
Example 3: Building Deep Nested Hierarchies Using -p
You need to set up a complex directory tree for a software application in a single stroke:
mkdir -p src/components/ui/buttons
You can verify the entire nested structure using the ls -R (recursive list) command or by navigating through it:
ls -R src
Output:
src:
components/
src/components:
ui/
src/components/ui:
buttons/
The -p flag built every intermediate directory (components, ui, and buttons) automatically.
Example 4: Tracking Actions with Verbose Output (-v)
When building complex directory trees, it is often helpful to see confirmation of every action the system takes. Combining -p with -v (verbose) provides clear feedback:
mkdir -pv projects/marketing/q1_campaign
Output:
mkdir: created directory ‘projects’
mkdir: created directory ‘projects/marketing’
mkdir: created directory ‘projects/marketing/q1_campaign’
The verbose output clearly outlines each step of the hierarchy constructed by the command.
Summary Checklist for mkdir
- [ ] mkdir stands for Make Directory, used to create new folders from the command line.
- [ ] Use -p (parents) to automatically build missing parent directories in a path and prevent errors if a folder already exists.
- [ ] Use -v (verbose) to print confirmation messages for every directory created.
- [ ] Separate multiple directory names with spaces to create several folders at once (e.g., mkdir folder1 folder2 folder3).
- [ ] Always enclose directory names containing spaces in quotes (“…”) or escape them with backslashes (\).
Section 1.6: Cleaning the Filesystem — Removing Directories (rmdir and rm)
In the previous section, you learned how to bring new directory structures into existence using mkdir. However, an active filesystem naturally accumulates temporary folders, obsolete project directories, and abandoned workspaces. Maintaining a clean and organized system requires knowing how to safely and effectively remove directories when they are no longer needed.
In the Linux command line, removing directories is handled by two distinct commands depending on the state of the folder: rmdir for strictly empty directories, and rm -r for populated directories containing files and subfolders.
Part 1: The rmdir Command (Removing Empty Directories)
The rmdir command (short for remove directory) is designed with a powerful safety philosophy: it will only delete directories if they are completely empty.
If you attempt to delete a folder that contains even a single file or hidden item, rmdir will refuse to execute, printing an error message to protect you from accidentally destroying data.
rmdir[options]directory_name(s)
Why Use rmdir Instead of Other Tools?
Because of its strict safety check, rmdir acts as a guardrail. It ensures that you never accidentally wipe out valuable work when you intended to clean up an old, empty scratchpad folder.
Essential Options and Flags for rmdir
| Option | Flag Name | Description |
| -p, –parents | Parents | Removes the specified directory, and then checks if its parent directory has also become empty. If so, it removes the parent as well, repeating up the tree. |
| -v, –verbose | Verbose | Prints a confirmation message for every directory successfully removed. |
Part 2: Deleting Non-Empty Directories Recursively (rm -r)
In the real world, directories are rarely empty when you want to delete them. A project folder usually contains code files, subdirectories, assets, and configuration documents.
Because rmdir will flatly reject deleting populated folders, you must turn to the more powerful rm command (short for remove). By default, rm is built to delete files, not directories. To instruct it to delete directories and everything inside them, you must supply the recursive flag (-r or -R).
rm[options]target_directory(s)
Understanding the Recursive Mechanism (-r)
When you run rm -r, the command traverses downward into the target directory, deletes every individual file and subfolder it encounters, and finally removes the parent folder itself.
The Danger Zone: Force (-f) and Combined Flags (-rf)
Because rm -r can wipe out entire directory trees in a fraction of a second, the shell will often prompt you for confirmation before deleting files if write permissions are restricted. To bypass these prompts, users frequently combine the recursive flag with the force flag (-f):
rm -rf folder_name
⚠️ Critical Warning: The rm -rf command is one of the most powerful and potentially destructive tools in Linux. If pointed at the wrong location (such as the root directory /), it will systematically delete your entire operating system without hesitation or recovery options. Always double-check your path before hitting Enter when using recursive removal!
Essential Options for Recursive Removal (rm)
| Option | Flag Name | Description |
| -r, -R, –recursive | Recursive | Removes directories and their contents recursively down the tree. |
| -f, –force | Force | Ignores nonexistent files and missing arguments, and never prompts the user for confirmation before deleting. |
| -i | Interactive | Prompts the user for confirmation before removing every single file, adding a layer of safety. |
| -v, –verbose | Verbose | Explains what is happening step-by-step as files and directories are deleted. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how both rmdir and rm -r operate in real-world scenarios.
Example 1: Removing a Simple Empty Directory
Suppose you created a temporary test folder named scratchpad and no longer need it.
rmdir scratchpad
If scratchpad is empty, it vanishes instantly with no output, confirming success.
Example 2: The Safety Guardrail in Action (rmdir failure)
Imagine you try to use rmdir on a directory named project_files that still contains a text file:
rmdir project_files
Expected Error Output:
rmdir: failed to remove ‘project_files’: Directory not empty
The command protects your data by refusing to delete the folder because it contains files.
Example 3: Cleaning Up Nested Empty Hierarchies (rmdir -p)
You created a nested directory path for testing: logs/archive/2025. After moving files elsewhere, all three directories are now completely empty. You can clean them all out in one clean command using -p:
rmdir -p logs/archive/2025
rmdir deletes 2025, notices archive is now empty so it deletes that, and finally deletes logs as well.
Example 4: Deleting a Populated Directory Tree (rm -r)
You have an entire old project folder named test_build containing dozens of files and subdirectories that you want to completely erase.
rm -r test_build
The shell recursively enters test_build, purges all internal contents, and removes the parent folder.
Example 5: Safe Recursive Deletion with Confirmation (rm -ri)
If you want the power of recursive removal but want to protect yourself from mistakes, combine recursion with interactive mode (-i):
rm -ri old_project
Expected Behavior: The terminal will pause and ask for confirmation before deleting each item:
rm: descend into directory ‘old_project’? y
rm: remove regular file ‘old_project/notes.txt’? y
This allows you to verify deletions item-by-item, preventing accidental data loss.
Summary Checklist for Removing Directories
- [ ] Use rmdir to remove empty directories safely; it will block deletion if any files remain inside.
- [ ] Use rmdir -p to remove nested directories that all become empty simultaneously.
- [ ] Use rm -r to delete directories that contain files and subfolders (recursive removal).
- [ ] Exercise extreme caution with rm -rf, as it forcefully deletes everything in its path without prompting or confirmation.
- [ ] Use rm -ri for an interactive, safer recursive deletion process that prompts you before removing files.
Section 1.7: Creating Empty Files and Updating Timestamps — The touch Command
So far in this chapter, you have learned how to inspect your location (pwd), list file contents (ls), navigate across the directory tree (cd), create directories (mkdir), and remove directories (rmdir and rm). You now know how to build and clean up the structural skeleton of your filesystem. But what about the actual files that live inside those directories—documents, scripts, configuration notes, and source code?
While files are typically populated using text editors or download utilities, you will frequently find yourself needing to create a blank file instantly, or adjust the recorded creation and modification times of an existing file. In the Linux command line, this versatile tool is known as touch.
What is touch?
At its core, the touch command serves two primary purposes:
- Creating Empty Files: If you specify a filename that does not currently exist, touch creates a brand-new, completely empty file with that name on disk.
- Updating Timestamps: If the file you specify already exists, touch updates its access and modification timestamps to the exact current date and time, without altering a single byte of the file’s internal content.
touch[options]filename(s)
Why is touch So Useful?
Beginners often wonder why a command dedicated to creating “empty” files is necessary. After all, why not just open a text editor? The utility of touch becomes clear across several common workflows:
- Rapid Workspace Preparation: When starting a new project or writing code, developers often sketch out the file structure beforehand (e.g., creating index.html, style.css, and app.js all at once) before writing any code inside them.
- Scripting and Automation: Automated build scripts and backup routines often rely on empty “flag” or “lock” files to signal states to other programs (e.g., creating a .lock file to indicate a maintenance script is currently running).
- Testing and Timestamp Manipulation: Software testing, file synchronization utilities, and backup systems often rely heavily on file modification times. touch allows administrators to explicitly manipulate these timestamps.
Decoding File Timestamps in Linux
Every file on a Linux filesystem maintains three primary timestamps, often referred to as file time attributes:
- Access Time (atime): The last time the file’s contents were read or accessed.
- Modification Time (mtime): The last time the actual data inside the file was modified or written to.
- Change Time (ctime): The last time the file’s metadata or permissions were modified.
You can inspect these timestamps using the long listing format combined with time sorting (ls -lt) or by using specialized commands like stat. By default, running touch on an existing file updates both the access and modification times to the current second.
Essential Options and Flags for touch
While touch can be run simply with a filename, its options unlock powerful control over how files and timestamps are handled:
Common`touch`Options
| Option | Flag Name | Description |
| -c, –no-create | No Create | Prevents touch from creating a file if it does not already exist. It simply does nothing if the file is missing. |
| -a | Access Time Only | Updates only the file’s access time (atime), leaving the modification time untouched. |
| -m | Modification Time Only | Updates only the file’s modification time (mtime), leaving the access time untouched. |
| -t STAMP | Specific Timestamp | Allows you to set a custom timestamp using a specific date and time format ([[CC]YY]MMDDhhmm[.ss]) instead of using the current time. |
| -r FILE, –reference=FILE | Reference File | Copies the timestamps from a reference file and applies them to the target file. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how touch operates in everyday command-line workflows.
Example 1: Creating a Single Empty File
Suppose you want to create a blank scratch notes file named todo.txt in your current directory.
touch todo.txt
ls -lh todo.txt
Expected Output:
-rw-r–r– 1 alex staff 0 Nov 5 14:00 todo.txt
(Notice that the file size is 0 bytes, confirming that a brand-new, empty file was successfully created.)
Example 2: Creating Multiple Files Simultaneously
Instead of creating files one by one, you can supply multiple filenames separated by spaces to generate several empty files in a single stroke:
touch index.html style.css script.js
ls -F
Expected Output:
index.html script.js style.css todo.txt
All three web development files are created instantly.
Example 3: Updating the Timestamp of an Existing File
Suppose you have an existing configuration file named config.cfg. You want to update its modification time to right now so that backup scripts recognize it as recently touched.
touch config.cfg
Because config.cfg already exists, no new file is created. Instead, its internal modification timestamp is refreshed to the current system time.
Example 4: Copying Timestamps from a Reference File (-r)
Imagine you have an old backup report named report_final.pdf, and you want to stamp a newly generated log file with that exact same date and time for consistency. You can use the reference flag (-r):
touch -r report_final.pdf current_session.log
The current_session.log file now inherits the exact access and modification timestamps of report_final.pdf.
Example 5: Setting a Custom Specific Timestamp (-t)
If you need to artificially stamp a file with a specific date in the past (for instance, January 1st at 12:30 PM), you can use the -t option followed by the format [[CC]YY]MMDDhhmm[.ss]:
touch -t 202601011230 archive_record.txt
ls -l archive_record.txt
Expected Output:
-rw-r–r– 1 alex staff 0 Jan 1 2026 archive_record.txt
The file’s timestamp is explicitly set to January 1, 2026, at 12:30 PM.
Summary Checklist for touch
- [ ] touch is used primarily to create new, empty files or update timestamps on existing files.
- [ ] Supplying multiple filenames to touch creates them all simultaneously in a single command.
- [ ] Use -c (no-create) to ensure touch only updates existing files without accidentally generating new ones.
- [ ] Use -r (reference) to copy timestamps from one file to another.
- [ ] Use -t to apply a precise custom timestamp in the YYYYMMDDhhmm format.
Section 1.8: Duplicating Files and Directories — The cp Command
Up to this point in your command-line journey, you have learned how to inspect your location (pwd), list file contents (ls), navigate the filesystem (cd), create directories (mkdir), remove directories (rmdir and rm), and manage empty files or timestamps (touch).
However, one of the most common everyday tasks in any operating system is duplication: creating backups of important scripts, generating configuration templates, or copying documents from one workspace to another. In the Linux command line, duplication is handled by the cp command, short for copy.
Basic Usage and Syntax
The cp command requires at least two pieces of information to function: what you want to copy (the source) and where you want to put the duplicate (the destination).
cp[options]sourcedestination
Depending on how you structure your arguments, cp performs two fundamentally different operations:
- File-to-File Duplication: Copies an existing file to a new filename (effectively creating a duplicate in the same or a different directory).
- File-to-Directory Placement: Copies one or more files directly into an existing target directory.
Part 1: Copying Files
Let’s examine how file duplication works in practice. Suppose you have a file named notes.txt in your current directory and you want to create a backup copy named notes_backup.txt.
cp notes.txt notes_backup.txt
What Happens Under the Hood?
- The shell locates notes.txt in your current directory.
- It reads the contents of notes.txt and writes them into a brand-new file on disk named notes_backup.txt.
- The original notes.txt remains completely untouched and intact.
Copying Multiple Files into a Directory
You can also pass multiple source files followed by a target directory as the final argument. For example, if you want to move three source files into a folder named archive:
cp file1.txt file2.txt file3.txt archive/
The shell copies all three files into the archive directory, preserving their original filenames.
Part 2: The Danger of Overwriting Files
By default, cp is a silent overwriter. If you specify a destination filename that already exists on disk, cp will overwrite the existing file immediately without warning or confirmation.
# If ‘existing_report.docx’ already exists, its contents are replaced instantly!
cp new_draft.docx existing_report.docx
Because accidental overwrites can lead to permanent data loss, Linux provides protective flags to give you control over how cp handles existing files.
Essential Options and Flags for cp
To master file duplication, you should familiarize yourself with the standard options that modify cp’s default behavior:
Common`cp`Options
| Option | Flag Name | Description |
| -i, –interactive | Interactive | Prompts the user for confirmation with a warning before overwriting any existing file. |
| -r, -R, –recursive | Recursive | Copies directories and all of their internal contents recursively (required when copying folders). |
| -v, –verbose | Verbose | Explains what is happening step-by-step, printing confirmation messages for every file copied. |
| -p | Preserve Attributes | Preserves original file attributes, including modification times, access times, ownership, and permissions. |
| -a, –archive | Archive | Equivalent to -dR –preserve=all. Used for exact backups, preserving links, permissions, timestamps, and recursive structures. |
| -u, –update | Update | Copies only when the source file is newer than the destination file, or when the destination file is missing. |
Part 3: Copying Directories Recursively (-r)
Just as the standard rm command refuses to delete directories without the recursive flag, the standard cp command will refuse to copy a directory unless explicitly told to do so recursively.
If you attempt to copy a folder named project_folder into a backup location without any options:
cp project_folder backup_folder/
Expected Error Output:
cp: -r not specified; omitting directory ‘project_folder’
Using -r for Directory Trees
To copy an entire directory structure along with all of its subdirectories and files, you must include the recursive flag (-r or -R):
cp -r project_folder backup_folder/
When this command runs, cp creates a new directory named project_folder inside backup_folder/ and recursively duplicates every internal file and subfolder.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how cp operates across different real-world scenarios.
Example 1: Creating a Quick File Backup
You are about to edit a configuration file named server.conf. Before making changes, you want to create a safe backup copy named server.conf.bak.
cp server.conf server.conf.bak
ls -lh server.conf*
Expected Output:
-rw-r–r– 1 alex staff 1.2K Nov 5 15:10 server.conf
-rw-r–r– 1 alex staff 1.2K Nov 5 15:10 server.conf.bak
Both files exist side-by-side with identical sizes and content.
Example 2: Safe Copying with Interactive Prompts (-i)
To prevent accidental overwrites when copying files, always use the interactive flag (-i):
cp -i report.docx backup/report.docx
Expected Behavior: If backup/report.docx already exists, the terminal pauses and asks for confirmation:
cp: overwrite ‘backup/report.docx’?
Typing y or yes proceeds with the overwrite; typing n or no cancels the operation safely.
Example 3: Tracking Large Copies with Verbose Output (-v)
When copying multiple files or large directory trees, it is helpful to see real-time confirmation of what the system is doing. Combining recursive and verbose flags provides clear feedback:
cp -rv source_files/ destination_backup/
Expected Output:
‘source_files/’ -> ‘destination_backup/source_files’
‘source_files/index.html’ -> ‘destination_backup/source_files/index.html’
‘source_files/style.css’ -> ‘destination_backup/source_files/style.css’
‘source_files/app.js’ -> ‘destination_backup/source_files/app.js’
Example 4: Creating Exact System Backups with Archive (-a)
When backing up system scripts, logs, or user data where preserving original timestamps, permissions, and ownership is critical, use the archive flag (-a):
cp -a /etc/nginx /home/alex/nginx_backup/
This performs a recursive copy while maintaining every file’s exact administrative metadata.
Summary Checklist for cp
- [ ] Use cp source destination to duplicate files in Linux.
- [ ] Remember that cp overwrites existing files silently by default; use -i (interactive) to prompt for confirmation.
- [ ] Use -r (recursive) when copying directories and their internal contents.
- [ ] Use -v (verbose) to print confirmation messages for every file being copied.
- [ ] Use -a (archive) to create exact backups that preserve timestamps, permissions, and file attributes.
Section 1.9: Moving and Renaming Files — The mv Command
Throughout this chapter, you have learned how to orient yourself with pwd, list contents with ls, navigate the tree with cd, create directories with mkdir, clean up directories with rmdir and rm, generate files with touch, and duplicate files with cp.
However, files and folders do not stay in one place forever. Projects evolve, directory structures need reorganization, and files frequently need to be renamed as work progresses. In the Linux command line, relocating files across directories and renaming them are handled by a single, powerful utility: mv, short for move.
What is mv?
At its core, the mv command performs two distinct operational functions depending on how its destination arguments are structured:
- Relocating (Moving): It moves files or directories from one location in the filesystem to another, physically shifting them out of their original folder into a new destination folder.
- Renaming: In the Unix philosophy, renaming a file is simply moving it to a new name within the same directory. Because of this, mv is the primary command used to rename files and directories across Linux systems.
mv[options]sourcedestination
Part 1: Moving Files and Directories
When moving a file to a new directory, mv requires two primary arguments: the path of the file you want to move (the source) and the path of the target directory where it should arrive.
mv report.pdf /home/alex/Documents/archive/
What Happens Under the Hood?
Unlike the cp command, which duplicates data and leaves the original intact, mv is a relocation tool.
- The shell locates the source file.
- It updates the filesystem’s directory pointers so that the file now resides in the new destination folder.
- It removes the entry from the original location.
Because this is a pointer update rather than a heavy data duplication process, moving even massive gigabyte-sized files or entire directory trees happens almost instantaneously.
Part 2: Renaming Files and Directories
Because renaming is just moving a file to a new name in the exact same directory, you use mv for renaming as well.
mv draft.txt final_report.txt
How the Rename Works:
- Source (draft.txt): The existing filename in your current directory.
- Destination (final_report.txt): The new filename you want to assign.
When you execute this command, the file’s contents remain completely untouched, but its label in the filesystem directory table is updated instantly. You can verify the change using ls.
Part 3: The Overwrite Danger and Protection Flags
Just like cp, mv is a silent overwriter by default. If you move or rename a file, and a file with the exact same name already exists at the destination, mv will overwrite the existing file immediately without warning or confirmation.
# If ‘notes.txt’ already exists in the folder, its contents are permanently replaced!
mv fresh_notes.txt notes.txt
Because accidental overwrites can destroy important work, Linux provides protective flags to safeguard your files.
Essential Options and Flags for mv
To maintain control over your file operations, mv supports several important flags:
Common`mv`Options
| Option | Flag Name | Description |
| -i, –interactive | Interactive | Prompts the user for confirmation before overwriting any existing file at the destination. |
| -n, –no-clobber | No Clobber | Prevents mv from overwriting any existing file under any circumstances (silently skips the move if the target exists). |
| -f, –force | Force | Overwrites destination files without prompting (default behavior, overrides -i). |
| -v, –verbose | Verbose | Explains what is happening step-by-step, printing confirmation messages for every file moved or renamed. |
| -u, –update | Update | Moves the source file only if it is newer than the destination file, or if the destination file does not exist. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how mv operates across everyday command-line scenarios.
Example 1: Renaming a File in Place
Suppose you created a scratch file named todo.txt and want to rename it to weekly_tasks.txt.
mv todo.txt weekly_tasks.txt
ls -F
Expected Output:
weekly_tasks.txt
The file is instantly renamed with no change to its internal contents.
Example 2: Moving a File into a Subdirectory
You have a script named deploy.sh in your current folder, and you want to move it into your scripts/ directory.
mv deploy.sh scripts/
ls scripts/
Expected Output:
deploy.sh
The file is relocated inside the scripts folder.
Example 3: Moving and Renaming Simultaneously
You can move a file to a completely new directory and give it a new name in a single command by specifying the new filename at the end of the destination path:
mv draft.txt /home/alex/Documents/archived_drafts/version_one.txt
The file leaves your current directory, arrives inside archived_drafts/, and is renamed to version_one.txt simultaneously.
Example 4: Safe Moving with Interactive Prompts (-i)
To prevent accidental data loss when moving files into folders where duplicates might exist, always use the interactive flag (-i):
mv -i report.pdf ~/Documents/
Expected Behavior: If ~/Documents/report.pdf already exists, the terminal pauses and prompts you:
mv: overwrite ‘/home/alex/Documents/report.pdf’?
Typing y or yes proceeds with the overwrite; typing n or no cancels the move safely.
Example 5: Tracking Actions with Verbose Output (-v)
When reorganizing complex project directories or moving multiple files, combining verbose mode (-v) with interactive mode (-i) provides clear real-time feedback:
mv -iv *.txt backup_folder/
Expected Output:
‘notes.txt’ -> ‘backup_folder/notes.txt’
‘todo.txt’ -> ‘backup_folder/todo.txt’
Every file movement is explicitly printed to the screen as it happens.
Summary Checklist for mv
- [ ] Use mv source destination to move files and directories across the filesystem.
- [ ] Use mv old_name new_name to rename files or directories in place.
- [ ] Remember that mv overwrites existing files silently; always use -i (interactive) to prompt for confirmation before overwriting.
- [ ] Use -v (verbose) to print confirmation messages for every file relocated.
- [ ] Because moving is a metadata pointer update rather than data duplication, it executes almost instantaneously even for massive directory trees.
Section 1.10: Deleting Files and the Anatomy of Destruction — The rm Command
As we reach the final section of Chapter 1, you have mastered the foundational lifecycle of the Linux filesystem. You can check your location (pwd), inspect contents (ls), navigate across directories (cd), create folders (mkdir), clean up empty directories (rmdir), generate blank files and update timestamps (touch), duplicate files (cp), and relocate or rename files (mv).
Now, we arrive at the most sensitive, powerful, and potentially destructive operation in system management: permanently removing files. In the Linux command line, this task is handled by rm, short for remove.
While rm shares its name root with the directory removal commands you encountered earlier, its primary domain is files. Because the command-line environment prioritizes absolute speed and direct hardware control over protective hand-holding, rm does not move deleted items to a desktop “Trash” or “Recycle Bin.” When you execute rm, the file is unlinked from the filesystem and marked for erasure, making recovery extremely difficult or impossible.
Mastering rm requires a thorough understanding of its syntax, its protective flags, and the profound respect required when wielding it.
Basic Usage and Syntax
The syntax for rm is concise and direct. You provide the command followed by one or more target filenames you wish to delete:
rm[options]filename(s)
When you execute a successful rm command on a file, the terminal returns no output. The file vanishes from disk instantaneously.
The Philosophy of Deletion: Why There Is No “Trash Can”
In modern graphical user interfaces, deleting a file is a low-stakes action. If you accidentally delete a document, you simply open your desktop Trash or Recycle Bin, click “Restore,” and your file returns safely to its home.
The command-line environment operates on a fundamentally different philosophy:
- Performance and Simplicity: Servers and headless Linux environments do not run graphical window managers or background trash-monitoring daemons. Maintaining a global trash bin consumes system overhead.
- Automation and Scripting: When automated background scripts clean up temporary logs or old caches at 3:00 AM, they cannot pop up a graphical dialog box asking, “Are you sure?” They rely on direct, programmatic deletion.
Because of this, deletion on the command line is permanent by default. Once you press Enter, the filesystem reclaims the storage blocks allocated to that file.
The Danger Zone: Understanding Catastrophic Risks
Because rm acts immediately and irrevocably, misuse can lead to catastrophic data loss. Before examining how to use the command safely, it is vital to understand the two greatest hazards associated with rm:
1. Silent Unconditional Deletion
By default, standard rm does not ask for confirmation. If you pass a filename, it deletes it right away. If you mistakenly type a wildcard that matches important files, they are gone before you realize the error.
2. The Recursive Force Nightmare (rm -rf)
When combined with the recursive flag (-r) and the force flag (-f), rm becomes an unyielding bulldozer. If you accidentally execute a command that points to the root directory (/) or your home directory (~) with these flags, the system will systematically wipe out every file, application, configuration, and personal document on disk.
⚠️ Critical Safety Warning: Never run rm -rf / or similar variations. Always double-check your target paths, use relative paths carefully, and rely on interactive protection flags when working in sensitive directories.
Essential Options and Flags for rm
To mitigate the inherent risks of rm, the command provides several powerful flags designed to add safety checks, control verbosity, or handle bulk removals.
Common`rm`Options
| Option | Flag Name | Description |
| -i, –interactive | Interactive | Prompts the user for explicit confirmation (y/n) before removing every single file. |
| -I | Interactive Once | Prompts the user for confirmation once if more than three files are specified, or when removing recursively (a safer middle-ground than -i). |
| -f, –force | Force | Ignores nonexistent files, suppresses error messages, and never prompts the user for confirmation. |
| -r, -R, –recursive | Recursive | Removes directories and their contents recursively (required when deleting folder trees). |
| -v, –verbose | Verbose | Explains what is happening step-by-step, printing confirmation messages for every file deleted. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how rm operates across everyday command-line scenarios, emphasizing safe habits.
Example 1: Deleting a Single Unwanted File
Suppose you created a temporary scratch file named temp_notes.txt and no longer need it.
rm temp_notes.txt
ls -F
The file is instantly deleted from disk with no output.
Example 2: Deleting Multiple Files Simultaneously
You can supply multiple filenames separated by spaces to clean up several files in a single stroke:
rm draft1.txt draft2.txt old_scratchpad.log
All three files are erased simultaneously.
Example 3: Safe Deletion with Interactive Prompts (-i)
To build safe command-line habits and prevent accidental deletions, make the interactive flag (-i) your default practice when deleting important files:
rm -i important_record.txt
Expected Behavior: The terminal pauses and prompts you for verification:
rm: remove regular file ‘important_record.txt’?
Typing y or yes proceeds with deletion; typing n or no preserves the file safely.
Example 4: Bulk Cleanup Protection with -I
When deleting many files at once (for example, using a wildcard like *.tmp), accidental mistakes can wipe out unintended data. The capital -I flag acts as a smart guardrail, prompting you once before proceeding if you are deleting more than three files:
rm -I *.tmp
Expected Behavior:
rm: remove all 15 arguments?
This single prompt gives you a moment to pause and confirm that you really want to delete all 15 matching files before execution.
Example 5: Tracking Deletions with Verbose Output (-v)
When running batch deletions or cleaning up directories, combining verbose mode (-v) with interactive mode (-i) provides clear real-time feedback on every action taken:
rm -iv log_*.txt
Expected Output:
rm: remove regular file ‘log_01.txt’? y
removed ‘log_01.txt’
rm: remove regular file ‘log_02.txt’? y
removed ‘log_02.txt’
Every file deletion is explicitly confirmed and reported to the screen.
Chapter Summary Checklist: Welcome to the Shell
As you conclude Chapter 1, you have built a robust foundation in command-line navigation and file management. You now possess the core vocabulary required to operate within any Linux environment:
- [ ] pwd: Print your absolute working location in the filesystem.
- [ ] ls: List directory contents, reveal hidden files (-a), and inspect long-format attributes (-l).
- [ ] cd: Navigate the filesystem using absolute paths, relative paths, and special shortcuts (.., ~, -).
- [ ] mkdir: Build new directories, including nested hierarchies using -p.
- [ ] rmdir: Safely remove empty directories.
- [ ] touch: Create blank files or update timestamps.
- [ ] cp: Duplicate files and directory trees safely (-i, -r).
- [ ] mv: Move and rename files across the system.
- [ ] rm: Permanently remove files while exercising caution and utilizing protective flags (-i, -I).
Chapter 2: Inspecting and Viewing Files
Section 2.1: Concatenating and Displaying File Contents — The cat Command
In Chapter 1, you built a robust command-line foundation. You learned how to check your location (pwd), list file contents (ls), navigate the directory tree (cd), create and clean up directories (mkdir, rmdir, rm), manage files and timestamps (touch), duplicate structures (cp), and relocate or rename assets (mv). You can now construct, organize, and maintain the physical skeleton of your filesystem.
Now, we turn our attention inside the files themselves. When working in a terminal environment, you frequently need to inspect code files, read configuration settings, check system logs, or review documentation without opening a heavy graphical text editor.
Welcome to Chapter 2. We begin with one of the most famous, foundational, and widely used utilities in the Unix ecosystem: cat, short for concatenate.
What is cat?
The name cat is derived from its primary design role: concatenating files. However, in everyday command-line practice, its most common use is much simpler—reading and displaying the contents of a file directly on your terminal screen.
cat[options]file(s)
When you pass a filename to cat, the shell reads the data from that file stream and writes it directly to standard output (stdout), which is your terminal display window.
How cat Works: The Unix Philosophy of Data Streams
To truly master cat, it helps to understand how Unix-like operating systems handle input and output. In Linux, everything is treated as a stream of bytes.
When you run cat filename.txt:
- The cat utility opens the file specified in the argument.
- It reads the raw bytes sequentially from disk.
- It streams those bytes directly to your terminal window line by line.
Because cat simply streams data from source to screen without pausing, paging, or breaking it down into interactive viewports, it is exceptionally fast. However, this speed comes with a notable limitation: if you run cat on a massive log file containing millions of lines, the text will rush past your screen instantly, filling your terminal buffer and leaving you staring at the very end of the file.
- cat is ideal for short to medium-sized files (configuration files, short scripts, code snippets, READMEs).
- For massive files, Linux provides specialized paging and trimming utilities (such as less, head, and tail), which we will explore later in this chapter.
Part 1: Displaying Single and Multiple Files
Let’s examine the two core operational modes of cat: viewing a single file and concatenating multiple files together.
1. Displaying a Single File
To read a text file, simply type cat followed by the filename:
cat notes.txt
The terminal instantly prints the entire contents of notes.txt from top to bottom.
2. Concatenating Multiple Files
The true namesake feature of cat is its ability to take two or more separate source files, read them in sequential order, and output them as a single continuous data stream.
cat file1.txt file2.txt file3.txt
The shell reads file1.txt, streams it to the screen, immediately appends file2.txt, and finishes with file3.txt.
While seeing multiple files printed together on screen can be chaotic, this concatenation power becomes extremely useful when combined with shell output redirection (which we will explore shortly).
Essential Options and Flags for cat
While basic cat outputs raw text exactly as stored on disk, it supports several helpful flags to format output, add line numbers, or reveal hidden whitespace characters.
Common`cat`Options
| Option | Flag Name | Description |
| -n, –number | Number All Lines | Prefixes every line in the output with a sequential line number. |
| -b, –number-nonblank | Number Non-Blank Lines | Prefixes sequential line numbers to lines containing text, but skips numbering empty blank lines. |
| -s, –squeeze-blank | Squeeze Blank Lines | Suppresses consecutive empty blank lines, replacing multiple blank lines with a single blank line. |
| -E, –show-ends | Show Line Ends | Displays a dollar sign ($) character at the exact end of every line, revealing trailing spaces. |
| -T, –show-tabs | Show Tabs | Displays tab characters explicitly as ^I instead of invisible whitespace. |
| -A, –show-all | Show All | Equivalent to combining -vET, displaying all non-printing characters, tabs, and line endings. |
Part 2: Creating and Combining Files Using cat and Redirection
Beyond reading files, cat is frequently paired with shell redirection operators (> and >>) to create or merge files directly from the command line without opening an editor.
1. Creating a New File on the Fly (>)
By running cat without a source file argument, the command waits for input directly from your keyboard (standard input). You can type text, and then press Ctrl + D (the EOF or End-of-File signal) to save and exit:
cat > grocery_list.txt
(Once you type your text and press Ctrl + D, cat writes your keyboard input directly into a new file named grocery_list.txt.)
2. Appending Text to an Existing File (>>)
If you want to add text to the bottom of an existing file without overwriting its current contents, use the append operator (>>):
cat >> grocery_list.txt
3. Merging Multiple Files into a New Combined File
You can use cat to concatenate multiple source files and redirect their combined output into a brand-new target file:
cat chapter1.txt chapter2.txt > complete_book.txt
The contents of chapter1.txt and chapter2.txt are merged sequentially and saved into complete_book.txt.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how cat operates across everyday command-line workflows.
Example 1: Reading a Configuration File
Suppose you want to inspect a system configuration file named hosts located in the /etc directory:
cat /etc/hosts
Expected Output:
127.0.0.1 localhost
127.0.1.1 ubuntu-server
::1 localhost ip6-localhost ip6-loopback
The entire contents of the configuration file stream directly to your screen.
Example 2: Inspecting Code with Line Numbers (-n)
When reading scripts or source code, line numbers are essential for referencing specific bugs or segments. Combining cat with the -n flag adds automatic line numbering:
cat -n script.py
Expected Output:
1 #!/usr/bin/env python3
2
3 def main():
4 print(“Hello, Linux World!”)
5
6 if __name__ == “__main__”:
7 main()
Every single line—including blank lines—is clearly numbered on the left.
Example 3: Numbering Only Non-Blank Lines (-b)
If you have a document with many empty spacing lines and want line numbers applied only to lines containing actual text, use the -b flag:
cat -b script.py
Expected Output:
1 #!/usr/bin/env python3
2 def main():
3 print(“Hello, Linux World!”)
4 if __name__ == “__main__”:
5 main()
Notice how the blank lines on lines 2 and 5 are left unnumbered, keeping your sequence clean and readable.
Example 4: Cleaning Up Excessive Spacing (-s)
Sometimes poorly formatted text files or log exports contain large blocks of consecutive blank lines. The squeeze flag (-s) collapses multiple empty lines into a single blank line:
cat -s messy_document.txt
This instantly compresses runaway whitespace, making the document much easier to scan.
Example 5: Revealing Hidden Whitespace and Line Ends (-E)
Invisible bugs in configuration files or scripts are often caused by stray trailing spaces at the ends of lines or hidden tab formatting. You can expose these hidden characters using -E and -T:
cat -ET configuration.conf
Expected Output:
server_ip = 192.168.1.100$
port = 8080^I# Default HTTP port$
debug_mode = true$
The dollar sign ($) reveals exactly where each line terminates, and ^I exposes tab characters.
Summary Checklist for cat
- [ ] cat stands for Concatenate, used primarily to read, display, and combine file contents in the terminal.
- [ ] Running cat filename streams the entire file directly to standard output.
- [ ] Use -n to display all lines with sequential numbers, or -b to number non-blank lines only.
- [ ] Use -s to squeeze consecutive empty lines into a single blank line.
- [ ] Use -E and -T to reveal hidden line endings ($) and tabs (^I).
- [ ] Combine cat with redirection operators (> and >>) to create, append, or merge files directly from the command line.
- [ ] Remember that cat streams data without pausing; for massive files, rely on page-by-page viewers.
Section 2.2: Paging Through Files — The less and more Commands
In the previous section, we explored the cat command. You learned how cat reads a file and streams its entire contents directly to standard output. For short configuration snippets, small scripts, or concise code blocks, cat is exceptionally fast and efficient.
However, what happens when you run cat on a massive system log file containing 500,000 lines of data?
The text rushes past your terminal screen at blinding speed. Your terminal’s buffer fills up instantly, pushing thousands of lines of valuable history out of view, and leaving you staring helplessly at the very bottom of the document. The beginning of the file is entirely lost to history.
To solve this problem, Linux provides pagers—interactive utilities designed to display large files one screenful at a time, allowing you to scroll forward, scroll backward, search for specific terms, and navigate massive documents effortlessly.
The two primary paging utilities in the Linux ecosystem are more (the classic historical pager) and less (the modern, feature-rich successor).
Part 1: The Modern Standard — The less Command
Despite its paradoxical name (“less is more”), less is actually much more powerful than more.
While older pagination tools required the system to read an entire file into memory before opening it (which could freeze terminals on massive multi-gigabyte files), less loads files lazily. It reads only the portion of the file needed to fill the current screen. As a result, less opens instantly, whether your file is 10 lines long or 10 gigabytes.
less[options]filename
Launching and Interacting with less
When you open a file with less:
less massive_system.log
The terminal clears, and you see the first screenful of the file. At the very bottom of the screen, you will see a prompt (often just a colon : or the filename).
Because less is an interactive program, it takes over your terminal window. You do not type normal shell commands while inside less; instead, you use single-key shortcuts to navigate:
EssentialKeyboardShortcutsInsideless
| Keystroke | Action / Navigation |
| Spacebar or Page Down | Scroll forward one full screen down. |
| b or Page Up | Scroll backward one full screen up. |
| Enter or Down Arrow | Scroll forward one single line at a time. |
| Up Arrow | Scroll backward one single line at a time. |
| g | Jump instantly to the very beginning (top) of the file. |
| G | Jump instantly to the very end (bottom) of the file. |
| /pattern | Search forward for a specific text pattern (e.g., /error). |
| ?pattern | Search backward for a specific text pattern. |
| n | Jump to the next match of your active search. |
| N | Jump to the previous match of your active search. |
| h | Open the built-in help summary menu. |
| q | Quit and exit less, returning you to your normal shell prompt. |
Part 2: Essential Options and Flags for less
While less is primarily controlled interactively via keyboard shortcuts once open, it also supports command-line flags that modify its startup behavior:
Common`less`Options
| Option | Flag Name | Description |
| -N, –LINE-NUMBERS | Line Numbers | Displays sequential line numbers alongside every line in the file. |
| -S, –chop-long-lines | Chop Long Lines | Cuts off lines that exceed the width of your terminal screen instead of wrapping them awkwardly onto multiple lines. |
| -i, –IGNORE-CASE | Smart Case Search | Makes your search queries case-insensitive unless you include uppercase letters in your search term. |
| -F, –quit-if-one-screen | Auto-Exit | If the file is short enough to fit entirely on a single screen, less exits automatically without making you press q. |
| -X, –no-init | No Clear Screen | Leaves the file text visible on your terminal screen even after you quit less. |
Part 3: The Classic Legacy — The more Command
Before less became the ubiquitous modern standard, Unix systems relied on more.
more[options]filename
How more Works
more is a simpler, strictly forward-moving pager. When you run more large_file.log, it displays the file screen-by-screen.
- You can press the Spacebar to move forward one screen.
- You can press Enter to move down one line at a time.
- The Historic Limitation: For decades, classic more did not allow you to scroll backward. If you pressed past the information you wanted, you had to exit and restart the command. (While modern Linux implementations of more have added basic backward scrolling, less remains vastly superior and is universally preferred by system administrators).
Part 4: Supercharging Pagers with Piping (|)
The true power of less shines when it is combined with the pipe operator (|).
In Linux, a pipe takes the standard output (stdout) generated by one command and streams it directly as input into another command. Instead of piping data into a file on disk, you pipe data directly into less.
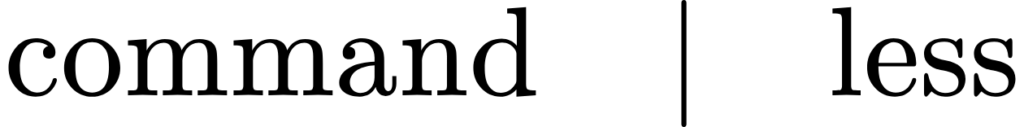
This allows you to page through the output of commands that normally flood the screen, such as listing massive directories, inspecting system logs, or reviewing package lists.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how less, more, and piping operate in real-world scenarios.
Example 1: Paging Through a Large Log File
Suppose you need to review a massive system log located in /var/log/syslog:
less /var/log/syslog
The file opens instantly. You can press Spacebar to read downward, b to scroll back up, and q to exit when finished.
Example 2: Viewing Files with Line Numbers Enabled (-N)
When inspecting code or configuration logs inside less, having line numbers visible makes referencing specific entries much easier:
less -N complex_config.conf
Every line is clearly numbered on the left margin as you scroll through the document.
Example 3: Searching for Errors Inside less
Suppose you open a massive server log and need to find every occurrence of the word “failed”:
- Open the file:
- Bash
less /var/log/auth.log
While inside less, type /failed and press Enter.- The screen jumps directly to the first match, highlighting the word.
- Press n to jump forward to the next match, or N to jump to the previous match.
Example 4: Piping Command Output into less
Imagine you run a command to list every installed package on an Ubuntu system (dpkg -l). The output spans tens of thousands of lines and rushes off your screen instantly.
By piping the output into less, you can examine the results interactively:
dpkg -l | less
Now, you can scroll up and down, search for specific software packages using /, and exit cleanly with q.
Example 5: Preventing Awkward Line Wrapping (-S)
When viewing files that contain long tabular data or wide source code lines, wrapping text breaks alignment. Using the chop lines flag (-S) keeps wide lines clean:
less -S wide_database_export.csv
Lines that exceed your terminal width are clipped cleanly at the edge instead of wrapping onto messy secondary lines.
Summary Checklist for less and more
- [ ] Use less as the modern, feature-rich standard for viewing large files interactively without filling your terminal buffer.
- [ ] Use Spacebar to scroll down, b to scroll up, and q to quit.
- [ ] Use / followed by a search term to search forward through a document, and press n to cycle through matches.
- [ ] Combine less with the pipe operator (|) to examine long command outputs interactively (e.g., command | less).
- [ ] Use -N in less to enable persistent line numbers, and -S to chop wide lines cleanly.
- [ ] Remember that more is an older, legacy forward-only pager; less is vastly more powerful and preferred for all modern Linux workflows.
Section 2.3: Inspecting the Beginning and End of Files — The head and tail Commands
In the previous sections of Chapter 2, you learned how to read files in their entirety using cat and how to page through massive documents interactively using less and more.
However, in many system administration, programming, and data analysis workflows, you do not need to view an entire file—nor do you want to spend time opening an interactive pager. Often, you only need a quick peek at the very beginning of a file to verify its structure (such as checking CSV headers or script shebangs), or a look at the very end of a file to check the most recent entries in a log.
To accomplish this swiftly and efficiently, Linux provides two complementary utilities: head and tail.
Part 1: Inspecting the Start of Files — The head Command
The head command prints the first part of one or more files to standard output. By default, if no options are specified, head outputs exactly the first 10 lines of the target file.
head[options]file(s)
How head Operates
When you execute head filename.txt, the utility opens the file, reads the initial lines into memory, prints them to the terminal, and terminates immediately without reading the rest of the file. This makes head exceptionally fast, even when operating on multi-gigabyte files.
Essential Options and Flags for head
| Option | Flag Name | Description |
| -n N, –lines=N | Lines Count | Prints the first N lines instead of the default 10. (If prefixed with a plus sign like +N, it prints all lines starting from line N onward). |
| -c N, –bytes=N | Bytes Count | Prints the first N bytes of the file instead of lines. Useful for binary files or raw data streams. |
| -q, –quiet, –silent | Quiet Mode | Suppresses the printing of file header banners when multiple files are provided as arguments. |
| -v, –verbose | Verbose Mode | Always prints a descriptive header banner naming the file before displaying its contents, even if only a single file is provided. |
Part 2: Inspecting the End of Files — The tail Command
While head focuses on the beginning of a file, the tail command focuses on the end. By default, tail outputs the last 10 lines of a target file.
tail[options]file(s)
How tail Operates
tail is indispensable for checking recent updates, error logs, and system events. Like head, it reads only the necessary portion of the file, making it instantaneous and lightweight.
Essential Options and Flags for tail
| Option | Flag Name | Description |
| -n N, –lines=N | Lines Count | Prints the last N lines instead of the default 10. (If prefixed with a plus sign like +N, it starts printing from line N to the end of the file). |
| -c N, –bytes=N | Bytes Count | Prints the last N bytes of the file instead of lines. |
| -f, –follow | Follow Output | Keeps the command open and actively monitors the file, printing new lines as they are appended in real time. |
| -q, –quiet, –silent | Quiet Mode | Suppresses file header banners when multiple files are monitored. |
| -v, –verbose | Verbose Mode | Always displays a header banner identifying the file before printing its contents. |
Part 3: Real-Time Log Monitoring with tail -f
One of the most powerful features in the entire Linux command-line toolkit is the follow flag (-f) in tail.
When you run tail -f, the command does not exit after printing the last 10 lines. Instead, it holds the terminal open, continuously watching the file for new data. The moment another program, service, or user appends text to the end of that file, tail -f immediately prints those new lines to your screen in real time.
This makes tail -f the ultimate tool for monitoring live system logs, web server access logs, database activity, and application compilation processes.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how head and tail operate across everyday command-line workflows.
Example 1: Viewing the Default First 10 Lines (head)
To quickly inspect the beginning of a system configuration file:
head /etc/passwd
Expected Output:
root:x:0:0:root:/root:/bin/bash
daemon:x:1:1:daemon:/usr/sbin:/usr/sbin/nologin
bin:x:2:2:bin:/bin:/usr/sbin/nologin
sys:x:3:3:sys:/dev:./usr/sbin/nologin
sync:x:4:65534:sync:/bin:/sync
games:x:5:60:games:/usr/games:/usr/sbin/nologin
man:x:6:12:man:/var/cache/man:/usr/sbin/nologin
lp:x:7:7:lp:/var/spool/lpd:/usr/sbin/nologin
mail:x:8:8:mail:/var/mail:/usr/sbin/nologin
news:x:9:9:news:/var/spool/news:/usr/sbin/nologin
Example 2: Specifying a Custom Line Count (head -n)
If 10 lines is too many or too few, use -n to specify an exact number. For example, to check only the first 3 lines of a data export:
head -n 3 dataset.csv
Expected Output:
id,name,category,price
1,Widget A,Hardware,19.99
2,Widget B,Hardware,24.50
Example 3: Viewing the Default Last 10 Lines (tail)
To inspect the most recent entries in a system log:
tail /var/log/syslog
The terminal displays the final 10 lines of the log file.
Example 4: Monitoring Live Log Files (tail -f)
To watch a web server error log in real time while testing an application:
tail -f /var/log/nginx/error.log
The command stays active in your terminal. As errors occur or requests arrive, new log lines stream onto your screen instantly. Press Ctrl + C to exit the follow mode.
Example 5: Extracting Specific Line Ranges Using Combination Pipes
While head and tail are powerful on their own, their true flexibility emerges when combined using pipes (|).
Suppose you have a 100-line document, and you want to extract only lines 20 through 25. You can achieve this in two steps:
- First, take the top 25 lines using head.
- Second, pipe that output into tail to take the last 6 lines of those 25.
head -n 25 document.txt | tail -n 6
How it works:
- head -n 25 document.txt outputs lines 1 through 25.
- The pipe (|) sends those 25 lines directly into tail -n 6.
- tail extracts the final 6 lines of that incoming stream, leaving you with exactly lines 20 through 25.
Summary Checklist for head and tail
- [ ] Use head to view the beginning of a file (default 10 lines).
- [ ] Use head -n N to specify an exact number of lines to display from the top.
- [ ] Use tail to view the end of a file (default 10 lines), ideal for checking recent log entries.
- [ ] Use tail -f to monitor files in real time as new data is appended (exit using Ctrl + C).
- [ ] Combine head and tail with pipes (|) to slice out specific middle line ranges from documents.
Section 2.4: Counting Words, Lines, and Bytes — The wc Command
As we continue exploring Chapter 2 (Inspecting and Viewing Files), you have learned how to read files entirely using cat, navigate massive documents interactively using less and more, and inspect the extreme boundaries of files using head and tail.
Often, however, your analytical needs go beyond reading text. When writing scripts, processing datasets, editing manuscripts, or auditing system log outputs, you need quantitative metrics: How many lines are in this log? How many words are in this draft? How large is this data stream in bytes?
To answer these questions efficiently, Linux provides a dedicated counting utility known as wc, short for word count.
What is wc?
Despite its name suggesting it only counts words, wc is a versatile metrics engine. When executed against a file, it reads the data stream and computes three primary statistical counts by default:
- Newlines (Line Count): The total number of line breaks (rows) in the file.
- Words: The total number of whitespace-separated words in the file.
- Bytes: The total size of the file measured in raw bytes.
wc[options]file(s)
When you pass a filename to wc, it outputs these three numerical statistics in a clean, tabular format alongside the filename.
How wc Works Under the Hood
The mechanics of wc are elegant in their simplicity. As wc reads a file byte by byte from disk or standard input, it monitors specific character triggers:
- Line counting tracks every time a newline character (\n) is encountered.
- Word counting tracks transitions between whitespace (spaces, tabs, and newlines) and printable text characters.
- Byte counting tallies every individual byte processed through the stream.
Because wc processes streams sequentially without storing the entire document in complex data structures, it executes with extreme speed, handling files containing millions of lines in a fraction of a second.
Default Output Structure
Let’s examine what happens when you run wc on a single text file without any options:
wc notes.txt
Typical Output:
45 320 2410 notes.txt
Reading left to right, the output represents:
- 45: The file contains 45 lines.
- 320: The file contains 320 words.
- 2410: The file contains 2,410 bytes.
- notes.txt: The name of the file being analyzed.
Essential Options and Flags for wc
While the default three-column output is helpful, you will frequently want to isolate a single metric or process data streams where filename banners are unhelpful. wc provides precise option flags to customize its output:
Common`wc`Options
| Option | Flag Name | Description |
| -l, –lines | Lines Only | Prints only the newline (line count) metric, suppressing words and bytes. |
| -w, –words | Words Only | Prints only the word count metric, suppressing lines and bytes. |
| -c, –bytes | Bytes Only | Prints only the raw byte count. |
| -m, –chars | Characters Only | Prints the character count (useful for UTF-8 and multibyte text where characters differ from raw bytes). |
| -L, –max-line-length | Maximum Line Width | Prints the length of the longest line (measured in characters) in the file. |
Part 2: Combining wc with Pipelines (|)
Just like head and tail, the true analytical power of wc emerges when it is combined with pipes (|). Because wc accepts input from standard input (stdin) if no filename is provided, you can pipe the output of any command directly into wc to gather real-time metrics.
For example, if you want to know how many files are currently inside a directory, you can pipe the output of ls into wc -l:
ls -1 | wc -l
(The -1 flag in ls forces single-column listing, and wc -l counts exactly how many lines—and thus how many files—were listed.)
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how wc operates across everyday command-line workflows.
Example 1: Getting Standard Metrics for a Single File
To inspect the line, word, and byte counts of a script named script.py:
wc script.py
Expected Output:
12 45 312 script.py
Example 2: Isolating Line Counts Only (-l)
When writing automated scripts that check whether a log file has grown or whether a configuration list contains a specific number of entries, you usually only care about lines. Using -l strips away words and bytes:
wc -l /etc/passwd
Expected Output:
42 /etc/passwd
Example 3: Finding the Maximum Line Length (-L)
If you are formatting code or editing documentation and want to ensure no lines exceed a specific character limit, use the max line length flag (-L):
wc -L README.md
Expected Output:
84 README.md
(This tells you that the longest single line in README.md is 84 characters wide.)
Example 4: Counting Words in a Writing Project
If you are drafting an article or a book chapter in plain text and want to check your total word count:
wc -w chapter1.txt
Expected Output:
4820 chapter1.txt
Example 5: Analyzing Multi-File Totals
If you pass multiple files to wc, it prints individual metrics for each file, followed by a total summary row at the bottom:
wc -l chapter1.txt chapter2.txt
Expected Output:
450 chapter1.txt
520 chapter2.txt
970 total
Summary Checklist for wc
- [ ] Use wc to compute lines, words, and bytes for any file.
- [ ] Use wc -l to isolate line counts.
- [ ] Use wc -w to isolate word counts.
- [ ] Use wc -c or wc -m for byte and character sizing.
- [ ] Use wc -L to find the length of the longest line in a document.
- [ ] Combine wc with pipes (|) to count the output of other commands (e.g., command | wc -l).
Section 2.5: Organizing and Ordering Text Streams — The sort Command
As we progress through Chapter 2 (Inspecting and Viewing Files), you have mastered reading files entirely (cat), paging through massive documents (less, more), inspecting boundaries (head, tail), and computing quantitative metrics (wc). You can view, scroll, trim, and measure text files with precision.
However, raw text data is rarely presented in the exact order you need. Log files are chronological, user lists are randomized, configuration inventories are scattered, and data exports are messy. To transform chaotic text into an organized, readable, and analyzable format, Linux provides one of the most powerful text-processing utilities in existence: sort.
What is sort?
At its core, the sort command reads lines of text from files or standard input, rearranges them according to specific ordering rules, and writes the sorted output to standard output.
sort[options]file(s)
By default, if you run sort without any options, it examines lines alphabetically (lexicographically) based on the ASCII character encoding values of each character from left to right.
How sort Works Under the Hood
Understanding how sort processes data explains its incredible efficiency:
- Line-Oriented Processing: sort treats each newline-terminated string as a discrete record. It does not care about individual words unless instructed; its primary unit of sorting is the entire line.
- Buffer Management and Temporary Files: When sorting small or medium files, sort performs the operation entirely in memory. When faced with massive multi-gigabyte datasets that exceed available RAM, sort automatically chunks the data, sorts pieces in memory, writes temporary sorted runs to disk, and merges them back together using an efficient external merge sort algorithm.
- Locale Sensitivity: By default, modern Linux sort commands respect your system’s locale settings, meaning punctuation, accent marks, and case sensitivity are handled according to your language environment.
Default Lexicographical Sorting vs. Numeric Realities
Before diving into flags, it is essential to understand the single biggest trap beginners encounter with sort: default alphabetical sorting.
If you have a file containing numbers like 2, 10, 20, and 5, and you run a default sort:
10
20
2
5
Why did this happen? Because sort operates lexicographically by default, it compares text character-by-character from left to right. It evaluates the character ‘1’ as coming before ‘2’, so 10 and 20 appear before 2.
To sort numbers mathematically rather than alphabetically, you must unlock sort’s specialized option flags.
Essential Options and Flags for sort
The true power of sort lies in its comprehensive suite of options that override default alphabetical behavior, target specific columns, ignore case, or eliminate duplicates.
Common`sort`Options
| Option | Flag Name | Description |
| -r, –reverse | Reverse Order | Reverses the sorting order, shifting from ascending (A-Z, 0-9) to descending (Z-A, 9-0). |
| -n, –numeric-sort | Numeric Sort | Compares strings based on their numerical arithmetic value (essential for numbers, prices, and sizes). |
| -u, –unique | Unique Output | Suppresses duplicate lines, ensuring that only unique sorted records are printed. |
| -f, –ignore-case | Ignore Case | Treats lowercase and uppercase letters identically (forces ‘a’ and ‘A’ to be sorted together). |
| -V, –version-sort | Version Sort | Natural sort of version numbers within text (e.g., version-1.2 comes before version-1.10). |
| -t SEP, –field-separator=SEP | Field Separator | Specifies a custom character separator (like a comma or colon) instead of default whitespace. |
| -k POS, –key=POS | Sort Key / Column | Restricts sorting to specific columns or fields within each line. |
Part 2: Advanced Field and Key Sorting (-t and -k)
In structured text files like CSVs, TSVs, or system files like /etc/passwd (which use colons as delimiters), lines are divided into distinct columns or fields. You rarely want to sort an entire line from the first character; instead, you want to sort based on a specific column (such as sorting a user list alphabetically by username, or a sales report numerically by revenue).
To achieve this, you combine two powerful flags:
- -t (Field Separator): Tells sort what character divides your columns.
- -k (Key / Field Position): Tells sort which specific column number to use as the sorting key.
sort-t’:’-k3,3nfilename
(This syntax tells sort to use a colon : as the separator, look at column 3, and sort it numerically n.)
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how sort operates across everyday command-line workflows.
Example 1: Basic Alphabetical Sorting
Suppose you have a plain text file named fruits.txt containing a randomized list of items:
banana
apple
Cherry
date
apricot
Running a standard sort:
sort fruits.txt
Expected Output:
Cherry
apricot
apple
banana
date
(Notice how uppercase ‘C’ comes before lowercase letters in ASCII-based alphabetical sorting.)
Example 2: Case-Insensitive Sorting (-f)
To make sorting ignore uppercase vs. lowercase differences, add the -f flag:
sort -f fruits.txt
Expected Output:
apricot
apple
banana
Cherry
date
(Now ‘apricot’, ‘apple’, and ‘banana’ are grouped cleanly regardless of letter case.)
Example 3: Reversing Sort Order (-r)
If you want to sort items in reverse descending order (Z to A):
sort -r fruits.txt
Expected Output:
date
banana
apple
apricot
Cherry
Example 4: Numeric Sorting (-n)
Suppose you have a file named scores.txt with numbers:
45
2
100
12
8
Running a numeric sort:
sort -n scores.txt
Expected Output:
2
8
12
45
100
(The numeric flag ensures values are evaluated mathematically.)
Example 5: Removing Duplicates On-The-Fly (-u)
If your file contains repeated entries and you want a clean, de-duplicated sorted list:
sort -u fruits.txt
Any duplicate lines are automatically collapsed into a single instance.
Example 6: Version Sorting (-V)
Standard alphabetical sort ranks v1.10 before v1.2 because ‘1’ comes before ‘2’. For software versions, use the version sort flag (-V):
sort -V version_list.txt
Expected Output:
app-v1.1.0
app-v1.2.4
app-v1.10.2
app-v2.0.0
Versions are ordered naturally and logically.
Example 7: Sorting Structured Data Using Fields (-t and -k)
Suppose you have a file named employees.csv structured with comma separation:
Alex,Engineering,85000
Sam,Marketing,72000
Jordan,Engineering,94000
Taylor,Sales,65000
You want to sort this file numerically by salary (column 3) in descending order:
sort -t’,’ -k3,3nr employees.csv
How it works:
- -t’,’ tells sort that commas separate the columns.
- -k3,3 targets strictly column 3.
- n sorts numerically.
- r reverses the order (highest salary first).
Expected Output:
Jordan,Engineering,94000
Alex,Engineering,85000
Sam,Marketing,72000
Taylor,Sales,65000
Summary Checklist for sort
- [ ] Use sort to arrange lines of text alphabetically by default.
- [ ] Use -r to reverse the sorting order (Z-A, highest-to-lowest).
- [ ] Use -n for correct mathematical numeric sorting.
- [ ] Use -u to filter out duplicate lines during sorting.
- [ ] Use -f to ignore case sensitivity.
- [ ] Use -V for natural software version sorting.
- [ ] Combine -t (separator) and -k (key column) to sort structured data like CSVs and logs with precision.
Section 2.6: Detecting and Filtering Repeated Lines — The uniq Command
As we continue exploring Chapter 2 (Inspecting and Viewing Files), you have mastered reading files (cat), paging through documents (less, more), inspecting boundaries (head, tail), computing metrics (wc), and ordering text streams (sort). You can view, scroll, trim, measure, and rearrange text files with absolute precision.
However, when processing large text files, log exports, or data streams, you frequently encounter redundant data. Repeated entries clutter outputs, bloat reports, and distort data analysis. To clean up and filter out adjacent duplicate records, Linux provides a specialized utility known as uniq, short for unique.
What is uniq?
The uniq command reads a text file or standard input, filters out redundant lines, and writes the cleaned result to standard output.
uniq[options][input_file][output_file]
By default, uniq examines adjacent lines. If two or more identical lines appear next to each other in sequence, uniq keeps the first instance and discards the subsequent duplicates.
The Golden Rule of uniq: Why Sorting is Prerequisite
Before examining how uniq operates, there is a fundamental rule every Linux user must memorize: uniq only detects adjacent duplicate lines.
If your file contains duplicate entries that are scattered across different parts of the document—separated by other lines of text—standard uniq will not catch them.
Unsorted File: Running ‘uniq’:
apple apple
banana banana
apple ──► uniq does apple (Kept because it wasn’t adjacent!)
cherry not see this cherry
Because of this behavior, uniq is almost always paired directly with the sort command using a pipe (|). By sorting the file first, you bring all identical lines together into contiguous blocks, allowing uniq to detect and filter every duplicate across the entire document reliably:
sort input.txt | uniq > cleaned_output.txt
Default Behavior and Output
Let’s look at what happens when you run uniq on a sorted file containing adjacent duplicates. Suppose you have a file named colors.txt with these contents:
blue
blue
red
green
green
green
yellow
Running default uniq:
uniq colors.txt
Expected Output:
blue
red
green
yellow
(Notice how the duplicate blue and the extra green entries are collapsed into single instances.)
Essential Options and Flags for uniq
While filtering out duplicates is its primary role, uniq supports a powerful set of options that enable counting, isolation, and formatting control.
Common`uniq`Options
| Option | Flag Name | Description |
| -c, –count | Count Occurrences | Prefixes every unique line with a count of how many times it appeared consecutively in the input. |
| -d, –repeated | Repeated Only | Displays only lines that have duplicates, suppressing entirely unique lines. |
| -u, –unique | Unique Only | Displays only lines that appear strictly once (no duplicates anywhere in the group). |
| -i, –ignore-case | Ignore Case | Makes comparisons case-insensitive (treats Apple and apple as identical). |
| -s N, –skip-chars=N | Skip Characters | Skips the first N characters of each line before performing comparisons. |
| -w N, –check-chars=N | Check Characters | Restricts comparison to a maximum of N characters per line. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how uniq operates across everyday command-line workflows.
Example 1: Basic De-duplication via Sorting and Piping
Suppose you have an unsorted list of server IP access logs in access.log with repeated entries:
192.168.1.10
192.168.1.50
192.168.1.10
192.168.1.25
192.168.1.50
To sort the log and filter out all duplicates into a clean, unique list:
sort access.log | uniq
Expected Output:
192.168.1.10
192.168.1.25
192.168.1.50
Example 2: Counting Frequency with -c
One of the most common administrative uses for uniq is frequency analysis—such as counting how many times a specific IP address accessed your server or how often an error appeared in a log.
By combining sort with uniq -c, and then sorting the results numerically by frequency (sort -nr), you build a powerful frequency table:
sort access.log | uniq -c | sort -nr
Expected Output:
3 192.168.1.50
2 192.168.1.10
1 192.168.1.25
(The -c flag prepends the count, and sort -nr organizes them from highest frequency to lowest.)
Example 3: Isolating Only Repeated Lines (-d)
If you want to audit a file to see only the records that appear more than once (discarding unique records entirely), use the -d flag:
sort inventory.txt | uniq -d
Only items that had duplicates in the original list are printed to the screen.
Example 4: Isolating Strictly Unique Lines (-u)
Conversely, if you want to find records that appeared only once without any duplicates, use the -u flag:
sort user_submissions.txt | uniq -u
Any entry that appeared two or more times is filtered out, leaving only the strictly one-off records.
Example 5: Case-Insensitive Comparison (-i)
By default, uniq distinguishes between uppercase and lowercase letters (Admin vs admin). To force uniq to treat them as identical:
sort names.txt | uniq -i
Case variations are consolidated into a single unique record.
Summary Checklist for uniq
- [ ] Use uniq to detect and filter out adjacent duplicate lines from text streams.
- [ ] Always sort first: Remember that uniq only checks adjacent lines; running sort file.txt | uniq is standard practice.
- [ ] Use -c (count) to prefix lines with their occurrence frequency.
- [ ] Use -d (repeated) to output only duplicated records.
- [ ] Use -u (unique) to output only non-duplicated single records.
- [ ] Use -i for case-insensitive duplicate filtering.
Section 2.7: Comparing Files Line by Line — The diff Command
As we near the conclusion of Chapter 2 (Inspecting and Viewing Files), you have mastered reading files (cat), paging through documents (less, more), inspecting boundaries (head, tail), computing quantitative metrics (wc), ordering streams (sort), and filtering duplicates (uniq). You possess a comprehensive toolkit for viewing, trimming, measuring, sorting, and cleaning text data.
However, in software development, system administration, and collaborative writing, one of the most frequent operational challenges is comparison:
- How has this configuration file changed since last week?
- What is the difference between my draft script and the production script?
- Where did this code break between version 1 and version 2?
While you could open both files side-by-side in an editor and scan them manually, that approach is error-prone and inefficient for large documents. To automate and streamline text comparison, Linux provides the diff command, short for difference.
What is diff?
The diff command compares two files line by line, analyzing their contents and outputting a precise set of instructions detailing the exact changes required to transform the first file into the second file.
diff[options]file1file2
When diff finishes its analysis, if the files are identical, it outputs nothing and exits silently. If the files differ, it generates a structured comparison report known as a diff output or patch instructions.
Understanding diff Output Syntax
Reading a diff report requires understanding its specialized instruction code. By default, diff uses a compact change-script format.
Every change block consists of an instruction header followed by the affected lines, marked with specific directional symbols:
- < (Less Than): Indicates lines that exist in File 1 (the original file) but are missing or changed in File 2.
- > (Greater Than): Indicates lines that exist in File 2 (the new file) but are missing or changed in File 1.
- — (Hyphens): Acts as a visual divider separating the old lines from the new lines in change blocks.
Decoding the Change Instructions
The instruction headers use line numbers and letters indicating the operation:
- c (Change): Lines that were modified between files (e.g., 5c5 means line 5 in file 1 was changed to line 5 in file 2).
- d (Delete): Lines that were present in file 1 but removed in file 2 (e.g., 3,4d2 means lines 3 and 4 were deleted).
- a (Add): Lines that were added to file 2 (e.g., 10a11,12 means lines were added after line 10).
Essential Options and Flags for diff
While standard diff output is powerful, its default format can sometimes be hard to parse visually. A robust suite of option flags allows you to customize its output for clarity, side-by-side comparison, or automated patching.
Common`diff`Options
| Option | Flag Name | Description |
| -u, –unified | Unified Format | Generates a unified diff output showing context lines around changes with + and – markers (the industry standard for code patches and Git). |
| -c | Context Format | Generates a contextual diff showing surrounding lines with explicit markings (* for file 1, – for file 2). |
| -i, –ignore-case | Ignore Case | Ignores case differences during comparison (treats uppercase and lowercase letters as identical). |
| -w, –ignore-all-space | Ignore All Whitespace | Ignores whitespace differences entirely (disregarding trailing spaces, tab variations, and multiple blank spaces). |
| -b, –ignore-space-change | Ignore Space Changes | Ignores changes in the amount of whitespace (treats single and multiple spaces as equivalent). |
| -r, –recursive | Recursive Comparison | Recursively compares all files inside two directories instead of just individual files. |
| -s, –report-identical-files | Report Identicals | Explicitly reports when two compared files are identical (instead of printing nothing). |
Part 2: The Industry Standard — Unified Diff (-u)
While the default change-script format is historically important, the unified diff format (-u) has become the universal standard across modern software engineering, code reviews, and version control systems like Git.
When you run diff -u file1 file2, the output presents a clean, readable comparison block:
- Lines starting with a minus (–) were removed from the original.
- Lines starting with a plus (+) were added in the new version.
- Unchanged lines are displayed with a leading space to provide contextual reference.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how diff operates across everyday command-line workflows.
Example 1: Comparing Two Slightly Different Files
Suppose you have an original configuration file named config_old.txt:
server = 192.168.1.10
port = 8080
timeout = 30
debug = false
And a modified version named config_new.txt:
server = 192.168.1.50
port = 8080
timeout = 60
debug = false
ssl = true
Running standard diff:
diff config_old.txt config_new.txt
Expected Output:
1c1
< server = 192.168.1.10
—
> server = 192.168.1.50
3c3
< timeout = 30
—
> timeout = 60
4a5
> ssl = true
Reading the Output:
- 1c1: Line 1 changed. File 1 had 192.168.1.10, while File 2 changed it to 192.168.1.50.
- 3c3: Line 3 changed (30 became 60).
- 4a5: A new line (ssl = true) was added after line 4 in File 2.
Example 2: Using Unified Diff Format (-u)
To view the exact same comparison in the modern, human-readable unified format:
diff -u config_old.txt config_new.txt
Expected Output:
— config_old.txt 2026-11-06 14:00:00.000000000 -0500
+++ config_new.txt 2026-11-06 14:05:00.000000000 -0500
@@ -1,4 +1,5 @@
-server = 192.168.1.10
+server = 192.168.1.50
port = 8080
-timeout = 30
+timeout = 60
debug = false
+ssl = true
The unified format makes it instantly obvious what was removed (–) and what was added (+).
Example 3: Ignoring Whitespace Differences (-w)
In programming and text editing, accidental trailing spaces or inconsistent indentation can trigger false positives in file comparisons. To ignore whitespace variations entirely:
diff -u -w script_v1.py script_v2.py
Changes in blank spaces and indentation are ignored, isolating only functional code modifications.
Example 4: Comparing Entire Directories Recursively (-r)
You can point diff at two directory trees to compare all contained files simultaneously:
diff -ru project_backup/ project_current/
diff recursively traverses both directory trees, comparing every matching file and reporting any discrepancies found across the entire project.
Summary Checklist for diff
- [ ] Use diff to compare two files line by line and generate a change script.
- [ ] Use -u (unified format) for clean, readable output with + and – markers (the industry standard).
- [ ] Use -w to ignore whitespace and indentation differences.
- [ ] Use -i for case-insensitive comparisons.
- [ ] Use -r to compare entire directory trees recursively.
- [ ] Remember that diff exits silently with no output if two compared files are completely identical.
Congratulations! You have successfully completed Chapter 2. You now possess a comprehensive, professional toolkit for reading, analyzing, measuring, and comparing text files directly from the Linux command line.
Let’s review the powerful utilities you’ve mastered throughout this chapter:
- [ ] cat: Streaming, concatenating, and creating files on the fly.
- [ ] less & more: Paging interactively through massive documents and logs.
- [ ] head & tail: Inspecting the extreme boundaries of files, including real-time log monitoring with tail -f.
- [ ] wc: Computing quantitative metrics (lines, words, bytes, and max line lengths).
- [ ] sort: Organizing chaotic text streams lexicographically, numerically, or via custom data columns (-t and -k).
- [ ] uniq: Detecting, filtering, and counting adjacent repeated lines.
- [ ] diff: Comparing files line by line and generating unified patches (-u).
Chapter 3: Streams, Redirection, and Text Filtering
Section 3.1: The Lifeblood of Unix — Standard Streams (stdin, stdout, stderr)
Throughout Chapters 1 and 2, you mastered the fundamental mechanics of the Linux filesystem. You learned how to navigate directories (pwd, cd), inspect files (ls), create and delete assets (mkdir, rm, touch), and read, measure, sort, and compare text data (cat, less, head, tail, wc, sort, uniq, diff).
Up to this point, you have largely interacted with commands as isolated tools: you type a command, it reads a file or your keyboard, and it prints results to your terminal screen.
Now, in Chapter 3, we cross a major threshold in your command-line proficiency. We are going to unlock the core engineering philosophy that makes Unix and Linux systems legendary: the Unix Philosophy.
The Unix Philosophy and Inter-Process Communication
Coined by Ken Thompson and refined over decades of operating system design, the Unix Philosophy rests on a few golden rules:
- Make each program do one thing well. Instead of building monolithic applications that try to handle every conceivable task, Unix utilities are designed as small, highly specialized, single-purpose tools.
- Expect the output of every program to become the input to another, as yet unknown, program.
How do these independent tools talk to one another? How does the output of a sorting utility flow seamlessly into a duplicate-filtering utility without being written to permanent storage on disk every single time?
The answer lies in streams. In Linux, data does not move around as static files alone; it flows dynamically as continuous streams of bytes. To manage these streams cleanly, every running program in Linux is automatically equipped with three standard communication channels, known as Standard Streams.
The Three Pillars of Standard Streams
When you launch any command, script, or application in a Linux terminal, the operating system opens three default communication channels for that process. Each channel is assigned a numeric identifier called a File Descriptor (FD):
| Stream Name | Common Abbreviation | File Descriptor | Default Source / Destination | Role in the System |
| Standard Input | stdin | 0 | Keyboard | Receives input data into the program. |
| Standard Output | stdout | 1 | Terminal Screen | Displays normal, successful program results. |
| Standard Error | stderr | 2 | Terminal Screen | Displays error messages, warnings, and diagnostics. |
Let’s examine each of these three pillars in detail.
1. Standard Input (stdin — File Descriptor 0)
Standard Input is the data channel through which a program receives information.
- Default Source: By default, stdin is connected to your keyboard. When a command expects input and you type characters into the terminal, those keystrokes flow down the stdin stream into the program.
- Alternative Sources: Commands do not care where their stdin comes from. Through redirection and piping, stdin can be fed automatically from a text file, the output of another command, or a network socket.
When a command runs without arguments and waits for you to type something (like typing into cat without a filename), it is actively listening to the stdin stream.
2. Standard Output (stdout — File Descriptor 1)
Standard Output is the data channel where a program sends its normal, successful operational results.
- Default Destination: By default, stdout is connected to your terminal display screen. When you run ls and see a list of files, or run cat notes.txt and see text printed on your monitor, those bytes are traveling across the stdout stream.
- Separation of Concerns: stdout carries the payload—the actual data you requested.
3. Standard Error (stderr — File Descriptor 2)
Standard Error is the dedicated data channel where a program reports warnings, diagnostic messages, and failure notifications.
- Default Destination: Like stdout, stderr defaults to your terminal display screen. If you misspell a command or try to open a file that does not exist, the error message you see on your screen arrived via the stderr stream.
- Why Separate Error from Output? This is one of the most brilliant design choices in Unix architecture. By keeping stdout (successful data) completely separate from stderr (error notifications), the system ensures that error messages do not corrupt your data streams. If you are piping the output of a data export into a file or another program, error messages will still flash visibly on your screen rather than getting silently swallowed and saved inside your data file.
Comprehensive Hands-on Practice & Examples
Let’s observe how stdin, stdout, and stderr operate in real-world scenarios using basic commands.
Example 1: Observing Default stdout
When you execute a simple command like echo:
echo “Hello, Linux Streams!”
What happens under the hood:
- The echo command processes the string.
- It writes the resulting text bytes into Standard Output (stdout, FD 1).
- Because stdout points to your terminal window by default, the text appears on your screen.
Example 2: Triggering and Observing stderr
What happens when a command fails? Suppose you instruct cat to open a file that does not exist:
cat nonexistent_file.txt
Expected Output:
cat: nonexistent_file.txt: No such file or directory
What happens under the hood:
- The cat program realizes the file cannot be found.
- Instead of writing text to stdout, it generates an error message.
- It routes that message directly into Standard Error (stderr, FD 2).
- Because stderr defaults to your terminal screen, you see the red or white error text.
Example 3: Feeding stdin Interactively
If you run cat without specifying any filename arguments, it enters an interactive state:
cat
What happens under the hood:
- The command sits idle, opening Standard Input (stdin, FD 0) and waiting for data.
- If you type:
- Plaintext
This is typed into stdin.
and press Enter, cat immediately copies those incoming bytes and echoes them back out to Standard Output (stdout, FD 1) on your screen.- Pressing Ctrl + D sends an End-of-File (EOF) signal, closing the stdin stream and terminating the program.
Summary Checklist for Standard Streams
- [ ] Linux processes communicate using three default data streams known as Standard Streams.
- [ ] Standard Input (stdin, FD 0) receives data into a program (defaulting to the keyboard).
- [ ] Standard Output (stdout, FD 1) transmits successful results (defaulting to the terminal screen).
- [ ] Standard Error (stderr, FD 2) transmits diagnostics and failure notices (also defaulting to the screen, but kept physically separate from stdout).
- [ ] Separating stdout from stderr ensures that error messages never contaminate your data streams or corrupt data processing pipelines.
Section 3.2: Redirection and Pipes — Harnessing Stream Flow
In the previous section, we established that every Linux process communicates through three foundational standard streams: Standard Input (stdin, FD 0), Standard Output (stdout, FD 1), and Standard Error (stderr, FD 2). By default, these streams are anchored to your keyboard and your terminal display screen.
However, if standard streams were permanently bound to physical hardware, the Unix environment would be severely limited. You could view results on your screen, but you could never save a log file to disk, feed a pre-written text file into an automated script, or chain twenty specialized utilities together to process gigabytes of data in a fraction of a second.
To break free from these physical defaults, Linux provides redirection and pipes. These mechanisms allow you to intercept data streams, reroute them into files, feed them into other programs, or separate output from error diagnostics.
Part 1: The Overwrite Redirect (>)
By default, when a command generates successful output, it streams those bytes into stdout, which paints characters across your terminal window. The overwrite redirect operator (>) allows you to intercept that stream and write it directly into a file on disk instead.
command>filename
How Overwriting Works Under the Hood
When the shell encounters the > symbol on the command line:
- The shell intercepts the command before it executes.
- It looks at the target filename specified on the right-hand side.
- The Danger Check: If the file already exists on disk, the shell truncates it immediately, wiping out all of its existing contents and reducing its size to zero bytes. If the file does not exist, the shell creates a brand-new, empty file.
- The shell redirects the process’s Standard Output (stdout, FD 1) away from the terminal screen and directly into that file.
- The command runs, and its output is quietly written into the file. Because stdout was captured, your terminal screen remains completely blank while the command executes.
Comprehensive Example: Saving Command Output
Suppose you want to save a list of files in your current directory into a text file named file_inventory.txt:
ls -la > file_inventory.txt
What happens:
- The ls -la command runs.
- Normally, its massive table of permissions, owners, and file sizes would flood your terminal screen.
- Because of the > operator, those bytes stream directly into file_inventory.txt.
- You can verify the success of the operation by reading the file:
- Bash
cat file_inventory.txt
⚠️ Critical Warning: Because >_ overwrites existing files instantly without warning, you must exercise caution. If you accidentally run ls > /etc/passwd or overwrite an important configuration file with command output, the previous data is permanently destroyed.
Part 2: The Append Redirect (>>)
While the overwrite redirect (>) is essential for generating new files or replacing outdated reports, you often want to add data to the end of an existing file without destroying what is already there (such as appending new entries to a system log or adding notes to a running journal).
For this task, Linux provides the append redirect operator (>>).
commandfilename
How Appending Works Under the Hood
When the shell encounters the >> symbol:
- It locates the target file on disk.
- If the file does not exist, it creates a new file (acting identically to >).
- The Safe Preservation: If the file already exists, the shell leaves all existing data intact and moves its internal file write pointer to the very end of the file (the EOF marker).
- The command’s output is then appended sequentially right below the existing text.
Comprehensive Example: Appending to a Log File
Suppose you are running a maintenance check and want to record system status updates into a file named audit_trail.log:
echo “=== Audit Started: $(date) ===” >> audit_trail.log
df -h >> audit_trail.log
echo “=== Audit Complete ===” >> audit_trail.log
What happens:
- Each command runs sequentially, and its output is safely appended to the bottom of audit_trail.log.
- You can run this script ten times a day, and every new report stacks neatly at the bottom without overwriting previous entries.
Part 3: Input Redirection (<)
Just as commands can have their output redirected away from the screen and into a file, they can also have their input redirected away from the keyboard and pulled from a file on disk. This is known as input redirection, represented by the less-than operator (<).
command<filename
How Input Redirection Works Under the Hood
Normally, commands that accept text input (like wc, sort, or custom scripts) listen to Standard Input (stdin, FD 0), which waits for keystrokes from your keyboard.
When you use the < operator:
- The shell opens the specified file on disk in read-only mode.
- It assigns that file stream directly to Standard Input (stdin, FD 0) for the target command.
- The command reads data from the file as if you were typing it line by line into the terminal.
Comprehensive Example: Feeding Files into Commands
Suppose you want to count the words, lines, and bytes in a document named manuscript.txt using wc.
While you can pass the filename directly (wc manuscript.txt), using input redirection achieves the exact same operational result by feeding the file directly into stdin:
wc < manuscript.txt
Expected Output:
450 3200 24500
(Notice that unlike running wc manuscript.txt, the output does not print the filename manuscript.txt at the end. This is because wc received raw byte streams via stdin without knowing the original filename.)
Part 4: Pipes (|) — Passing Data Between Commands
We now arrive at the crowning achievement of Unix architecture: pipes.
While redirection (>, >>, <) bridges the gap between files on disk and command streams, pipes bridge the gap directly between running processes without ever writing temporary files to disk.
Represented by the vertical bar (|), a pipe takes the Standard Output (stdout) of the command on the left and routes it directly into the Standard Input (stdin) of the command on the right.
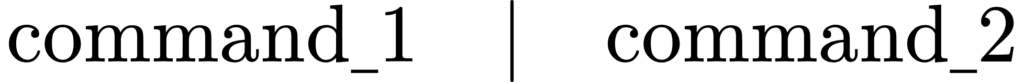
Why Pipes Are Revolutionary
Before pipes were invented, if you wanted to list files in a directory, sort them by size, take the top 5, and save the result, you had to write intermediate output to temporary files on disk:
# The clumsy pre-pipe way:
ls -l > temp1.txt
sort -k5,5nr temp1.txt > temp2.txt
head -n 5 temp2.txt > final_top5.txt
rm temp1.txt temp2.txt
Pipes eliminate disk clutter entirely. Data flows through memory from one tool to the next in a continuous, lightning-fast pipeline:
# The clean, elegant piped way:
ls -l | sort -k5,5nr | head -n 5
How Data Flows Through a Pipeline
When you execute a piped command string like ls -l | sort -k5,5nr | head -n 5:
- The shell launches all three processes (ls, sort, and head) simultaneously.
- It connects the stdout of ls to the stdin of sort via a pipe buffer in kernel memory.
- It connects the stdout of sort to the stdin of head through a second pipe buffer.
- Data begins streaming: ls generates file lists, sort catches them and sorts them numerically by column 5, and head catches the sorted stream and trims it down to the top 5 lines, finally printing those 5 lines to your terminal screen.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples combining redirection and pipes in real-world workflows.
Example 1: Creating and Overwriting Files (>)
Create a new file containing a greeting message:
echo “Welcome to Linux Chapter 3” > greeting.txt
cat greeting.txt
The text is written into greeting.txt, overwriting any previous content.
Example 2: Building Multi-Line Files with Appending (>>)
Build a multi-line configuration checklist by combining echo and append redirection:
echo “Step 1: Update package lists” > setup_log.txt
echo “Step 2: Install dependencies” >> setup_log.txt
echo “Step 3: Configure firewall” >> setup_log.txt
cat setup_log.txt
Expected Output:
Step 1: Update package lists
Step 2: Install dependencies
Step 3: Configure firewall
Example 3: Multi-Stage Analytical Pipelines (|)
Suppose you have a massive system access log (access.log). You want to answer a complex question: What are the 3 most frequently accessed IP addresses in this log?
Instead of writing a complex program, you can chain four standard Linux utilities together in a single pipeline:
awk ‘{print $1}’ access.log | sort | uniq -c | sort -nr | head -n 3
How this brilliant pipeline works step-by-step:
- awk ‘{print $1}’ access.log: Extracts the first column (the IP address) from every line in the log.
- | sort: Takes those IP addresses and sorts them alphabetically so identical IPs sit adjacent to one another.
- | uniq -c: Counts how many consecutive times each IP appears, prefixing them with frequency numbers.
- | sort -nr: Takes the frequency-prefixed list and sorts it numerically (n) in reverse (r) order, putting the highest counts at the top.
- | head -n 3: Trims the stream down to only the top 3 lines, displaying the most active IP addresses on your screen.
Summary Checklist for Redirection and Pipes
- [ ] Use > (overwrite redirect) to send stdout into a file, truncating existing content.
- [ ] Use >> (append redirect) to send stdout to the end of a file without destroying existing data.
- [ ] Use < (input redirection) to feed a file into a command’s stdin instead of typing from the keyboard.
- [ ] Use | (pipes) to stream the stdout of one command directly into the stdin of another without using temporary disk files.
- [ ] Combine redirection and pipes to build powerful, automated data processing pipelines.
Section 3.3: Filtering Text Streams with Regular Expressions — The grep Command
As we continue advancing through Chapter 3 (Streams, Redirection, and Text Filtering), you have mastered the fundamental architecture of standard streams (stdin, stdout, stderr), learned how to reroute data using overwrite (>) and append (>>) redirection, fed files into programs via input redirection (<), and chained independent utilities together using pipes (|).
You can now capture data streams, move them across files, and stream them between running processes. But what happens when you have a multi-gigabyte log file, a massive code repository, or a complex data stream, and you only want to extract the specific lines that match a particular pattern, keyword, or regular expression?
To accomplish this swiftly and powerfully, Linux provides the quintessential text-filtering engine: grep.
What is grep?
The name grep stands for Global Regular Expression Print. Originating from early Unix text-processing tools, grep is a utility designed to search plain-text data sets for lines matching a specific pattern or regular expression.
grep[options]patternfile(s)
When grep finds a line that contains a match for your search pattern, it extracts that entire line and prints it to standard output (stdout). If no match is found, it exits silently or returns an exit status indicating no match.
How grep Works Under the Hood
- Stream Processing: grep reads text line by line from either files specified as arguments or from standard input (stdin) when fed via pipes.
- Pattern Matching: For every line, it evaluates whether the text satisfies the search criteria. This criterion can be a simple literal string (like error) or a complex Regular Expression (regex) describing advanced patterns.
- Instant Extraction: Matching lines are immediately streamed to stdout, making grep exceptionally fast even when parsing massive log files containing millions of records.
Part 1: Basic String Matching vs. Regular Expressions
At its most basic level, grep can be used like a simple find tool—searching for an exact literal word inside a file:
grep “error” system.log
However, the true power of grep lies in its ability to parse Regular Expressions (regex). Regular expressions allow you to search for patterns rather than fixed strings (e.g., finding any line containing an IP address, an email address, or a phone number without knowing the exact digits beforehand).
Core Regular Expression Metacharacters
When using extended regular expressions (or standard expressions with appropriate flags), several characters take on special filtering meanings:
| Metacharacter | Meaning | Example | What it matches |
| . | Any single character | b.t | bat, bit, bot, b@t |
| ^ | Start-of-line anchor | ^Error | Lines that start with the word “Error” |
| $ | End-of-line anchor | done$ | Lines that end with the word “done” |
| * | Zero or more of preceding char | ro*t | rt, rot, root, rooot |
| **[abc] | Character class (any listed) | [aeiou] | Any single lowercase vowel |
| **[^abc] | Negated character class | [^0-9] | Any character that is not a digit |
Essential Options and Flags for grep
To master text filtering, you should familiarize yourself with the standard options that modify how grep searches, formats output, and handles matching rules:
Common`grep`Options
| Option | Flag Name | Description |
| -i, –ignore-case | Ignore Case | Performs case-insensitive matching (treats Error, ERROR, and error as identical). |
| -v, –invert-match | Invert Match | Reverses the filter: prints only lines that do not match the pattern. |
| -r, -R, –recursive | Recursive Search | Recursively searches through all files within directory trees. |
| -n, –line-number | Line Numbers | Prefixes matching output lines with their exact line numbers in the file. |
| -c, –count | Count Matches | Suppresses normal output and prints only the total count of matching lines per file. |
| -w, –word-regexp | Whole Word Match | Matches only whole words (preventing a search for cat from matching caterpillar). |
| -E, –extended-reg-exp | Extended Regex | Enables modern extended regular expressions (+, ?, ` |
| -o, –only-matching | Only Matching | Prints only the exact matching string itself rather than the entire enclosing line. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how grep operates across everyday command-line workflows.
Example 1: Basic Keyword Search
Suppose you have a configuration file named nginx.conf and you want to find every line containing the word listen:
grep “listen” /etc/nginx/nginx.conf
Every line containing listen is extracted and printed to your terminal screen.
Example 2: Case-Insensitive Searching (-i)
By default, grep is strictly case-sensitive. If you want to find references to “failed” regardless of whether they are written as Failed, FAILED, or failed, use the -i flag:
grep -i “failed” /var/log/auth.log
All case variations are successfully captured.
Example 3: Inverting Matches to Filter Out Noise (-v)
Sometimes filtering is about removing clutter rather than finding specific terms. If you want to inspect a configuration file but exclude all commented-out lines (lines starting with #) and empty lines:
grep -v “^#” config.conf | grep -v “^$”
How it works:
- grep -v “^#” filters out any line starting with a hash symbol.
- The pipe (|) streams the remaining text into grep -v “^$”, which strips away all empty blank lines.
Example 4: Displaying Line Numbers (-n) and Counting Matches (-c)
When auditing code or scripts, knowing where a pattern occurs is critical:
grep -n “TODO” script.py
Expected Output:
14: # TODO: Refactor database connection pooling
42: # TODO: Add unit tests for user authentication
(The -n flag prepends the exact line numbers 14 and 42.)
If you only want to know how many times the term appears without printing the lines themselves, use -c:
grep -c “ERROR” system.log
Expected Output:
142
Example 5: Recursive Codebase Searching (-r)
Suppose you are working on a massive software project across dozens of directories and need to find every file that references a specific function name (calculateTax):
grep -rn “calculateTax” src/
grep recursively (-r) scans every file inside the src/ directory tree and outputs matching lines with their respective line numbers (-n).
Example 6: Combining Pipes and grep
Because grep accepts standard input (stdin), it serves as the ultimate analytical filter at the end of pipelines.
For example, if you want to list all files in a directory and filter the list to show only items containing the word “report”:
ls -la | grep “report”
The ls -la output streams into grep, isolating only the filenames matching your query.
Summary Checklist for grep
- [ ] Use grep to search files or data streams for lines matching patterns or regular expressions.
- [ ] Use -i for case-insensitive matching.
- [ ] Use -v to invert matches (displaying lines that do not match).
- [ ] Use -n to display line numbers alongside matches.
- [ ] Use -r to search directory trees recursively.
- [ ] Combine grep with pipes (|) to filter command outputs dynamically across system workflows.
Section 3.4: Locating Files Across the Filesystem — The find Command
As we progress through Chapter 3 (Streams, Redirection, and Text Filtering), you have mastered the foundational mechanics of standard streams (stdin, stdout, stderr), learned how to reroute data using overwrite (>) and append (>>) redirection, fed files into programs via input redirection (<), chained independent utilities together using pipes (|), and filtered massive text streams using grep.
You can capture data streams, move them across files, pipe them between processes, and extract specific text patterns. But what happens when you know a file exists somewhere on your system, but you have no idea where it is located?
While ls lets you view the contents of your current directory, and cd lets you navigate known paths, searching an entire multi-terabyte filesystem for a misplaced configuration file, an old script, or a bloated cache requires a dedicated scanning engine.
To accomplish this with surgical precision, Linux provides one of the most powerful and flexible administrative tools in existence: find.
What is find?
The find command is a real-time filesystem traversal utility. Unlike database-driven search tools (like locate), which rely on pre-indexed background snapshots that can miss newly created files, find actively walks the live directory tree starting from a specified path, inspecting every file and folder against your exact criteria.
find[path][expression/options][actions]
When find evaluates files against your search expressions, it prints the matching paths to standard output (stdout).
How find Works Under the Hood
- Path Traversal: You provide a starting point (such as . for the current directory, /var/log for system logs, or / for the entire root filesystem). find recursively steps into every subdirectory.
- Expression Evaluation: For every file and directory encountered, find evaluates a series of tests and options from left to right.
- Short-Circuit Logic: If an expression evaluates to false, find immediately stops testing that file and moves to the next one, making traversal fast and efficient.
- Action Execution: By default, if no action is specified, find performs the default action: -print (outputting the matching file paths to the screen).
Part 1: Searching by Name and Pattern (-name and -iname)
The most common use case for find is locating files or directories by their filenames.
- -name “pattern”: Searches for files matching the exact pattern (case-sensitive).
- -iname “pattern”: Searches for files matching the pattern while ignoring letter case.
Using Wildcards with find
Because file searches often involve partial names, you will frequently enclose your search patterns in quotes (single or double). Enclosing patterns in quotes prevents your shell from interpreting wildcards (*, ?, []) before find receives them, ensuring the pattern is evaluated across the filesystem rather than just in your current folder.
find /home/alex -name “*.log”
Part 2: Filtering by File Type (-type)
A Linux filesystem contains more than just standard text and binary documents. It houses directories, symbolic links, sockets, and device files. The -type flag restricts your search to specific file classifications:
Common`find`TypeFlags
| Flag | File Classification | Description |
| -type f | Regular File | Standard documents, scripts, images, and archives. |
| -type d | Directory | Folders and subdirectories. |
| -type l | Symbolic Link | Shortcuts pointing to other files or directories. |
| -type b | Block Device | Storage devices like hard drives (/dev/sda). |
| -type c | Character Device | Serial ports and terminal devices. |
Part 3: Searching by File Size (-size)
When cleaning up disk space or auditing system storage, you often need to find files that exceed a certain size or consume excessive storage. The -size flag allows you to filter files based on allocated block size using specific units:
SizeUnitsin`find`
| Unit Suffix | Meaning | Example |
| c | Bytes | -size +500c (files larger than 500 bytes) |
| k | Kilobytes | -size 1024k (files exactly 1MB in size) |
| M | Megabytes | -size +50M (files larger than 50 megabytes) |
| G | Gigabytes | -size +2G (files larger than 2 gigabytes) |
Modifying Size Criteria with Signs
- +size: Greater than the specified size (e.g., +100M).
- -size: Less than the specified size (e.g., -10k).
- size: Exactly equal to the specified size.
Part 4: Searching by Modification and Access Time
System administrators frequently need to find files that were modified recently (e.g., during a security breach or software update) or files that haven’t been touched in years. find provides powerful time-based filters measured in days (time) or minutes (min):
TimeFilterOptions
| Option | Unit | Description |
| -mtime N | Days | Modified exactly N*24 hours ago. |
| -mtime +N | Days | Modified more than N days ago. |
| -mtime -N | Days | Modified less than N days ago (within the last N days). |
| -mmin N | Minutes | Modified exactly N minutes ago. |
| -mmin -N | Minutes | Modified within the last N minutes. |
| -atime N | Days | Last accessed (read) N days ago. |
Part 5: Executing Actions on Found Files (-exec)
Finding files is only half the battle. Often, once you locate files matching your criteria, you want to perform an operation on them—such as moving them, changing their permissions, compressing them, or deleting them.
The -exec option allows you to run any arbitrary Linux command on every file discovered by find.
find[path][expression]-execcommand{}
Anatomy of -exec:
- -exec: Tells find to execute the following command.
- {} (Curly Braces): Acts as a placeholder that find replaces dynamically with the path of each matching file it discovers.
- \; (Escaped Semicolon): Marks the termination of the -exec command string. (The backslash is required to prevent your shell from interpreting the semicolon prematurely).
⚠️ Critical Safety Warning: Combining find with -exec rm or deletion commands is extremely powerful. Always test your find criteria first without -exec (printing matching files to the screen) to ensure you are targeting exactly what you intend before executing destructive actions.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how find operates across everyday system administration and development workflows.
Example 1: Finding Files by Exact Name
Suppose you are looking for a configuration file named nginx.conf anywhere inside the /etc directory tree:
find /etc -name “nginx.conf”
Expected Output:
/etc/nginx/nginx.conf
Example 2: Case-Insensitive Pattern Searching (-iname)
You know you have a document with “readme” in the title, but you aren’t sure about capitalization (README.md, Readme.txt, readme.TXT). Use -iname:
find . -iname “*readme*”
Every file matching the pattern regardless of letter case is listed.
Example 3: Locating All Directories Named “backup” (-type d)
If you want to isolate only directories rather than files:
find /home/alex -type d -name “backup”
Only folders named backup inside your home directory are returned.
Example 4: Finding Large Files Exceeding 100 Megabytes (-size)
To audit your filesystem for storage hogs taking up more than 100MB:
find / -type f -size +100M 2>/dev/null
(Notice the 2>/dev/null at the end: when searching the entire root directory /, you will encounter restricted system folders like /proc or /sys that trigger “Permission Denied” errors. Redirection 2>/dev/null silences those error messages, keeping your screen clean).
Example 5: Finding Files Modified in the Last 24 Hours (-mtime)
To inspect files that were created or modified within the past 1 day:
find /var/www/html -type f -mtime -1
All web files modified in the last 24 hours are listed.
Example 6: Safely Deleting Old Log Files Using -exec
Suppose you want to find all .log files inside a temporary directory that have not been modified in over 30 days, and delete them:
find /var/tmp -type f -name “*.log” -mtime +30 -exec rm -v {} \;
How it works:
- find /var/tmp: Starts scanning in /var/tmp.
- -type f: Restricts search to regular files.
- -name “*.log”: Targets log files.
- -mtime +30: Filters for files older than 30 days.
- -exec rm -v {} \;: Safely passes each discovered file into rm -v for verbose deletion.
Summary Checklist for find
- [ ] Use find [path] [expression] to search live filesystem hierarchies in real time.
- [ ] Use -name for case-sensitive pattern matching and -iname for case-insensitive searches.
- [ ] Use -type f for files, -type d for directories, and -type l for symbolic links.
- [ ] Use -size +N and -size -N to filter files by storage weight (bytes, kilobytes, megabytes, gigabytes).
- [ ] Use -mtime and -mmin to track files by their modification age.
- [ ] Use -exec command {} \; to run automated operations on every file discovered by your search criteria.
Section 3.5: Instantaneous Database File Searches — The locate Command
As we continue exploring Chapter 3 (Streams, Redirection, and Text Filtering), you learned in the previous section how to use the find command. find is a powerful, real-time traversal tool that walks live directory trees down to the disk level. It inspects every file, folder, and attribute dynamically, making it the ultimate tool for precise, up-to-the-second administrative operations.
However, that immense power comes with a performance cost. When you run find / -name “config.ini”, your computer’s storage controller must physically traverse every single directory sector across your storage drives. On multi-terabyte systems or network-mounted volumes, live traversal can take several minutes to complete.
What if you don’t need a real-time disk scan? What if you just want to know where a file is located right now across your entire system in a fraction of a second?
For lightning-fast file discovery, Linux provides locate.
What is locate?
The locate command searches for files by name, not by scanning the live filesystem in real time, but by querying a pre-built background database that indexes your entire system’s file paths.
locate[options]pattern
When you execute locate, the command queries this compressed index database and returns every matching file path almost instantaneously—often in less than 0.01 seconds.
How locate Works Under the Hood: The Database and Indexer
To appreciate why locate is so radically faster than find, you must understand how its architecture operates behind the scenes:
- The System Indexer (updatedb): A background service or scheduled system task (typically running via cron daemon once a day) executes a companion command called updatedb (update database).
- Crawling the Filesystem: The updatedb utility crawls the entire system disk once, catalogs every file and directory name it encounters, compresses the resulting list, and saves it into a central database file (commonly located at /var/lib/mlocate/mlocate.db or /var/lib/locate/locatedb).
- Querying the Snapshot: When you type locate filename, the locate command does not touch your physical disks or scan directories. It simply opens this pre-compiled database file in memory, performs a rapid pattern search, and prints the results.
The Trade-Off: Speed vs. Freshness
Because locate reads a static snapshot database rather than live files:
- The Advantage: It is breathtakingly fast, consuming virtually zero disk I/O during searches.
- The Catch: If you create a brand-new file right now and immediately search for it using locate, you may get no results. Because the background index hasn’t run yet, the new file doesn’t exist in the database. (You can force an immediate database update by running sudo updatedb if you have administrative privileges).
Essential Options and Flags for locate
While basic locate is simple, its command-line flags provide fine-grained control over search behavior, output limits, and pattern matching:
Common`locate`Options
| Option | Flag Name | Description |
| -i, –ignore-case | Ignore Case | Performs case-insensitive matching (treats uppercase and lowercase letters identically). |
| -n N, –limit=N | Limit Results | Restricts output to a maximum of N matching results, preventing screen clutter on broad searches. |
| -c, –count | Count Only | Suppresses file paths and prints only the total number of matching files found. |
| -e, –existing | Existing Only | Checks the live filesystem before printing results, automatically filtering out files that have been deleted since the last database update. |
| -r, –regexp | Regular Expression | Interprets the search pattern as a POSIX Regular Expression rather than a basic glob pattern. |
| -S, –statistics | Database Stats | Displays summary statistics about the size and contents of the locate database. |
Understanding Regular Expressions (Regex)
Before we explore advanced search patterns with locate, this is the ideal moment to formally define and clarify one of the most powerful concepts in computer science and text processing: Regular Expressions (Regex).
What is a Regular Expression?
A regular expression is a sequence of characters that defines a specialized search pattern.
While simple wildcards (like *.txt) let you match basic file extensions, regular expressions provide a formal, universal syntax to describe complex text rules with surgical precision. They allow you to ask questions such as:
- Find any line containing exactly three digits followed by a hyphen.
- Match any filename that begins with either ‘log’ or ‘data’ and ends with a number.
- Locate strings containing specific character repetitions or optional patterns.
Regex Metacharacters vs. Literal Characters
In regex, most characters match themselves literally (e.g., the letter a matches the letter a). However, certain punctuation marks become metacharacters—special symbols with operational meaning:
- ^ (Caret): Asserts the position at the start of a string or line.
- $ (Dollar sign): Asserts the position at the end of a string or line.
- . (Period): Matches any single character whatsoever.
- * (Asterisk): Matches zero or more occurrences of the preceding character or group.
- + (Plus): Matches one or more occurrences of the preceding character.
- [] (Brackets): Defines a character class (matching any single character enclosed within, such as [0-9] for any digit).
Combining Regex with locate (-r)
By default, locate uses basic glob patterns. However, by supplying the -r (regular expression) flag, you can harness full regex syntax to query the system database.
locate-r”regex_pattern”
Let’s look at a concrete example. Suppose you want to locate any file on your system whose name ends with a number between 0 and 9 right before the file extension .log.
Using regex:
locate -r “\/[a-z]_[0-9]\.log$”
How this regex pattern works:
- \/ matches a literal directory slash.
- [a-z] matches any single lowercase letter.
- _[0-9] matches an underscore followed by any single numeric digit.
- \.log matches the literal extension .log (the dot is escaped with a backslash so it acts as a literal period rather than “any character”).
- $ anchors the match to the absolute end of the file path.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how locate operates across everyday system navigation workflows.
Example 1: Basic Filename Search
Suppose you are looking for any file or folder on your system named hosts:
locate hosts
Expected Output:
/etc/hosts
/etc/hosts.allow
/etc/hosts.deny
/usr/share/base-files/hosts
/usr/share/doc/base-files/hosts
Every matching path across the entire system database appears instantly.
Example 2: Case-Insensitive Searching (-i)
Because locate databases record exact capitalization, searching for README might miss lowercase readme.txt files. Use -i to ignore case:
locate -i “readme.md”
All case variations across documentation files are captured.
Example 3: Restricting Output Volume (-n)
Searching for common terms like config can return tens of thousands of results, flooding your terminal window. Use -n to limit the output to the first 10 matches:
locate -n 10 config
Expected Output:
/etc/adjtime
/etc/apparmor.d
/etc/bash.bashrc
/etc/bindresvport.blacklist
/etc/cron.daily
/etc/cron.daily/apt-compat
/etc/cron.daily/dpkg
/etc/cron.daily/logrotate
/etc/cron.daily/man-db
/etc/cron.daily/passwd
Example 4: Counting Total Matches Without Printing (-c)
If you want to know how many configuration files exist on your system without printing every path to the screen:
locate -c “.conf”
Expected Output:
1428
(This tells you immediately that there are 1,428 files ending in .conf indexed in the database).
Example 5: Filtering Out Deleted Files Automatically (-e)
If files have been deleted since updatedb last ran, standard locate will still output their stale paths. The existing flag (-e) forces locate to verify each file on the live disk before displaying it:
locate -e “temp_document”
Stale database records pointing to non-existent files are automatically suppressed.
Summary Checklist for locate
- [ ] Use locate for instantaneous file searches across a pre-compiled system database.
- [ ] Remember that locate relies on the background indexer updatedb; newly created files may require a database refresh before appearing.
- [ ] Use -i for case-insensitive searches.
- [ ] Use -n N to restrict output to a manageable number of results.
- [ ] Use -c to get a total count of matching files.
- [ ] Use -e to verify live filesystem existence and filter out deleted stale records.
- [ ] Use -r combined with Regular Expressions to execute advanced, pattern-based file searches.
Congratulations! You have successfully completed Chapter 3. You have moved beyond basic file management and individual command execution, harnessing the true power of the Unix philosophy by connecting tools together into automated, high-speed data pipelines.
Let’s review the core concepts and utilities you’ve mastered throughout this chapter:
- Standard Streams (stdin, stdout, stderr): The three fundamental data channels (0, 1, 2) that allow processes to receive input, output successful results, and report errors independently.
- Redirection (>, >>, <): Rerouting streams to and from files on disk, whether overwriting reports, safely appending logs, or feeding files into commands.
- Pipes (|): Chaining independent utilities together in memory to pass data directly from one process to another without cluttering disk space.
- grep: Filtering text streams with surgical precision using literal strings and Regular Expressions.
- find: Traversing live filesystem hierarchies in real time to locate files by name, type, size, age, and execute automated actions (-exec).
- locate: Querying pre-compiled system indexes via updatedb for instantaneous database file searches.
You now possess the foundational engineering skillset required to build powerful shell scripts, audit complex system environments, and process massive datasets efficiently.
Chapter 4: Permissions, Ownership, and Users
Section 4.1: Identity and Access — The User and Group Model, whoami, and id
Throughout the first three chapters of our journey, you have mastered the physical geography of the Linux filesystem (pwd, ls, cd), learned to manipulate directories and files (mkdir, rm, touch, cp, mv), read and analyzed file contents (cat, less, head, tail, wc, sort, uniq, diff), and harnessed the incredible power of the Unix philosophy through streams, redirection, pipes, grep, find, and locate. You can navigate, inspect, and process data across any Linux environment.
Now, we arrive at one of the most critical foundational pillars of operating system engineering: Security, Permissions, and User Management.
The Linux Multi-User Philosophy
Unlike early personal computing operating systems designed for a single user sitting in front of a monitor, Unix and Linux were built from the ground up as multi-user, time-sharing systems.
In a standard Linux environment—whether it is a personal workstation, a cloud virtual machine, or a massive enterprise server hosting thousands of concurrent web applications—multiple human users and background automated services share the exact same hardware, kernel, and filesystem simultaneously.
To prevent chaos, accidental file corruption, and malicious tampering, the operating system enforces a strict security boundary:
- Absolute Isolation: Every file and process on the system belongs to a specific user and a specific group.
- Access Control: No process can read, write, or execute a file unless explicitly permitted by the security credentials of the user running that process.
- The Superuser (root): A special administrative account (root, with User ID 0) holds unrestricted power over the entire system, capable of overriding all permissions for maintenance and configuration.
Before you can understand how Linux protects files and manages access, you must first answer a fundamental question: Who are you in the eyes of the operating system?
The Anatomy of System Identity: UIDs and GIDs
When you type your username into a login prompt, the Linux kernel does not actually care about your human name string. Behind the scenes, the kernel identifies every user and group purely through numerical identifiers:
- UID (User Identifier): A unique integer assigned to every user account on the system.
- UID 0: Reserved exclusively for the system administrator (root).
- UIDs 1 to 999 (or 499 on older systems): Reserved for system accounts, background daemons, and service processes (like web servers, database engines, and system loggers) which have limited privileges and cannot log in interactively.
- UIDs 1000 and above: Assigned to standard human user accounts created on the system.
- UID 0: Reserved exclusively for the system administrator (root).
- GID (Group Identifier): A unique integer assigned to a group of users, allowing administrators to grant shared permissions to multiple accounts at once. Every user belongs to a primary group and can optionally belong to multiple supplementary (secondary) groups.
Part 1: Discovering Your Active Username — The whoami Command
When working in complex terminal sessions, switching between different user accounts via su or sudo, or running automated scripts across remote servers, you need a lightning-fast way to verify your current effective identity.
For this purpose, Linux provides the whoami command, short for “Who am I?”.
whoami[option]
How whoami Works Under the Hood
When you execute whoami, the command does not query the keyboard or scan the filesystem. Instead, it makes an immediate system call to the Linux kernel to retrieve the Effective User ID (euid) of the currently running process, looks up that numerical UID in the system’s user database (traditionally /etc/passwd), and prints your human-readable username directly to standard output (stdout).
Essential Options and Flags for whoami
Because whoami is designed to perform one specific task with absolute efficiency, it supports very few options:
| Option | Flag Name | Description |
| –help | Help Menu | Displays a brief usage summary and exits. |
| –version | Version Info | Outputs version details and licensing information. |
Part 2: Comprehensive Identity Auditing — The id Command
While whoami tells you your username string, system administration often requires a complete audit of your security context: What is your numeric UID? What is your primary group GID? What supplementary groups do you belong to?
To retrieve a complete security profile, Linux provides the id command.
id[options][username]
When executed without arguments, id inspects your current user session and reports your exact UID, GID, and all associated group memberships.
Default Output Format
Running basic id in a terminal produces output resembling this:
uid=1000(alex) gid=1000(alex) groups=1000(alex),4(adm),24(cdrom),27(sudo),30(dip),46(plugdev),120(lpadmin),131(lxd),132(sambashare)
Decoding the Output:
- uid=1000(alex): Your user ID is 1000, and your username is alex.
- gid=1000(alex): Your primary group ID is 1000, and its group name is alex. (By default, modern Linux distributions create a private group matching your username upon account creation).
- groups=…: Every group security context active for your session. Notice how user alex belongs to their primary group (1000), plus several powerful administrative and hardware groups like adm, sudo (granting root execution privileges), cdrom, and sambashare.
Essential Options and Flags for id
The id command provides several powerful option flags to isolate specific components of your security identity, which is especially useful when writing shell scripts that need to parse permissions programmatically:
Common`id`Options
| Option | Flag Name | Description |
| -u, –user | User ID Only | Prints only the effective numeric User ID (UID), suppressing all other output. |
| -g, –group | Group ID Only | Prints only the effective numeric Primary Group ID (GID). |
| -G, –groups | All Groups Only | Prints all group IDs (both primary and supplementary) associated with the user as a list of integers. |
| -n, –name | Print Names | When combined with -u, -g, or -G, outputs the human-readable name instead of the raw number. |
| -r, –real | Real ID | Prints the real user or group ID instead of the effective ID (useful when running commands with elevated sudo privileges). |
| -Z, –context | Security Context | Displays the SELinux or AppArmor security context of the user (if mandatory access control is enabled). |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how whoami and id operate across everyday system administration and scripting workflows.
Example 1: Verifying Your Current Identity
Suppose you have logged into a remote server via SSH and want to confirm instantly which user account your session is bound to:
whoami
Expected Output:
alex
Example 2: Performing a Full Security Audit (id)
To check your complete security profile, including UID, GID, and group memberships:
id
Expected Output:
uid=1000(alex) gid=1000(alex) groups=1000(alex),27(sudo),1001(developers)
Example 3: Extracting Pure Numeric UID in Shell Scripts (id -u)
When writing automated shell scripts, you frequently need to verify whether a script is being executed by the root user before performing dangerous administrative tasks.
You can accomplish this by checking if the numeric UID equals 0:
if [ “$(id -u)” -ne 0 ]; then
echo “Error: This script must be run as root!”
exit 1
fi
(The -u flag isolates the raw number 0 or 1000, making programmatic conditional checks clean and reliable.)
Example 4: Getting the Effective Username (id -un)
While whoami gives you your username, combining -u (user) and -n (name) in id achieves the exact same result:
id -un
Expected Output:
alex
Example 5: Inspecting Another User’s Credentials
If you have administrative permissions, you are not limited to inspecting your own session. You can query the security profile of any other user account on the system by passing their username as an argument to id:
id www-data
Expected Output:
uid=33(www-data) gid=33(www-data) groups=33(www-data)
(This reveals the system identity credentials of the web server daemon account www-data, showing its isolated UID and GID).
Summary Checklist for whoami and id
- [ ] Linux is a multi-user environment where every process, file, and resource is bound to specific Users (UIDs) and Groups (GIDs).
- [ ] Use whoami to instantly retrieve your current effective username string.
- [ ] Use id to audit your complete security profile, displaying UIDs, GIDs, and all active group memberships.
- [ ] Use id -u to isolate numeric User IDs (essential for checking root privileges in shell scripts).
- [ ] Use id -Gn to view all group names associated with your user session.
- [ ] Pass a target username to id username to inspect other accounts on the system.
Section 4.2: Privilege Escalation — The su and sudo Commands
In the previous section, we explored the multi-user architecture of Linux, examining how the operating system tracks identity through User IDs (UIDs) and Group IDs (GIDs), and using whoami and id to audit our active session credentials.
We established that standard human user accounts (typically starting at UID 1000) operate with restricted privileges to protect the system from accidental file deletion, broken configurations, and malicious tampering. However, system administration requires performing privileged tasks—such as installing software packages, modifying system-wide network configurations (/etc/hosts, /etc/resolv.conf), managing user accounts, and restarting core system services.
To perform these tasks, you must temporarily escalate your privileges. In this section, we examine the two primary mechanisms Linux provides for privilege escalation: su (Switch User) and sudo (Superuser Do).
The Principle of Least Privilege
Before examining the mechanics of privilege escalation, it is vital to understand the golden rule of modern systems security: The Principle of Least Privilege.
In early computing environments, administrators often logged in directly as the all-powerful root user (UID 0) for everyday tasks. This practice proved catastrophic; a single mistyped command (rm -rf /) or a compromised web application running with root privileges could destroy the entire operating system in seconds.
Modern Linux architecture strictly forbids everyday root logins. Instead, users operate with standard permissions and escalate privileges only when necessary, for the exact duration required, and under strict auditing controls.
Part 1: The Traditional Switch — The su Command
The su command (short for Switch User or Superuser) is the classic Unix utility used to change your active user identity during an active terminal session.
su[options][username]
When executed without a username argument, su defaults to switching to the root user.
How su Works Under the Hood
- You run su in your terminal.
- The command prompts you to enter the target user’s password (e.g., the root password).
- If authenticated successfully, the shell spawns a new shell process running under the UID and GID of the target user, granting you their access rights.
Part 2: The Critical Distinction — su vs. su – (Login Shells)
One of the most common pitfalls for newcomers using su is failing to understand the difference between a standard shell switch and a login shell switch (su –).
When you run plain su:
- You switch your UID to root, but your environment variables (like $PATH, $HOME, and $MAIL) remain those of your original user account.
- This can cause commands to fail or behave unexpectedly because system administrative binaries located in /sbin or /usr/sbin may not be present in a standard user’s $PATH.
When you run su – (or su –login):
- The system simulates a complete, fresh login sequence for the target user.
- It clears your old environment variables and loads the target user’s complete environment configuration (from files like /root/.bashrc and /root/.profile), setting $HOME to /root and ensuring all administrative paths are fully loaded.
Essential Options and Flags for su
Common`su`Options
| Option | Flag Name | Description |
| -, -l, –login | Login Shell | Simulates a full login environment, resetting environment variables and shifting to the target user’s home directory. |
| -c COMMAND, –command=COMMAND | Run Command | Executes a single command as the target user without spawning an interactive shell session, returning immediately to your original shell upon completion. |
| -s SHELL, –shell=SHELL | Custom Shell | Specifies an alternate shell interpreter (e.g., /bin/zsh or /bin/sh) to invoke upon switching. |
Comprehensive Hands-on Practice & Examples (su)
Example 1: Switching to the Root User (Interactive Login Shell)
To switch to the root user with a fully initialized administrative environment:
su –
You will be prompted for the root password. Once entered, your prompt changes (typically from $ to #), indicating you are now operating as root in the /root home directory.
To return to your normal user account when finished, simply type:
exit
Example 2: Running a Single Administrative Command Without Switching Shells (-c)
If you need to run one privileged command (like restarting the Nginx web server) without opening an interactive root shell session:
su -c “systemctl restart nginx”
You enter the root password once, the command executes with administrative privileges, and you remain securely in your standard user shell.
Part 3: The Modern Standard — The sudo Command
While su is historically important, it has significant operational flaws:
- Password Sharing: To use su, every system administrator must know the exact root password. If an administrator leaves the organization, the root password must be changed and redistributed.
- All-or-Nothing Access: su – gives you total, unrestricted root access. You cannot grant a user permission to restart a web server using su without also giving them the ability to delete the entire filesystem.
To solve these problems, the sudo command (short for Superuser Do) was developed. sudo has become the absolute standard for privilege management across modern Linux distributions.
sudo[options]command
How sudo Works Under the Hood
When you prefix a command with sudo:
- The system checks the configuration file located at /etc/sudoers (managed via the visudo command) to verify whether your user account is authorized to run that specific command.
- If authorized, sudo prompts you to enter your own user password (not the root password). This verifies physical presence at the terminal.
- If your password is correct, the command executes with temporary root (or specified user) privileges.
- Complete Audit Logging: Every single sudo execution, including the timestamp, the user, and the exact command run, is logged automatically to /var/log/auth.log (or system journal), providing accountability.
Essential Options and Flags for sudo
Common`sudo`Options
| Option | Flag Name | Description |
| -u USER, –user=USER | Run as User | Executes the command as a user other than root (e.g., running a database script as the postgres user). |
| -i, –login | Simulated Login | Runs an interactive login shell as root, loading root’s environment variables. |
| -s, –shell | Run Shell | Runs the shell program specified in the SHELL environment variable with elevated privileges. |
| -l, –list | List Permissions | Displays the specific sudo privileges and commands your user account is authorized to run. |
| -v, –validate | Validate Timestamp | Updates your sudo timestamp ticket without running a command (refreshing your authentication timeout). |
Comprehensive Hands-on Practice & Examples (sudo)
Example 1: Executing a Privileged Command
To update system package lists using sudo:
sudo apt update
You enter your own user password. The command executes with root privileges.
Example 2: Inspecting Your Authorized Privileges (sudo -l)
To see what administrative commands your user account is allowed to execute across the system:
sudo -l
Expected Output:
Matching Defaults entries for alex on webserver:
env_reset, mail_badpass, secure_path=”/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin”
User alex may run the following commands on this server:
(ALL : ALL) ALL
(This output indicates that user alex is permitted to run all commands, as any user, on any target host).
Example 3: Running Commands as a Non-Root Service User (-u)
Often, system administrators need to execute commands as specialized service accounts (like www-data or postgres) rather than root. You can specify the target user with -u:
sudo -u postgres psql -c “\l”
This command executes the PostgreSQL terminal client specifically under the security context of the postgres user account.
Summary Checklist for su and sudo
- [ ] Privilege escalation allows restricted standard users to perform necessary administrative tasks securely.
- [ ] su (Switch User) transitions your session to another user (defaulting to root), requiring the target user’s password.
- [ ] Always use su – (login shell) to ensure environment variables and administrative paths load correctly.
- [ ] sudo (Superuser Do) is the modern security standard, allowing users to execute commands with administrative rights using their own password.
- [ ] sudo provides granular control via /etc/sudoers and maintains detailed audit logs in /var/log/auth.log.
- [ ] Use sudo -l to audit your authorized administrative privileges.
Section 4.3: Managing User Accounts — The useradd, usermod, and passwd Commands
As we continue advancing through Chapter 4 (Permissions, Ownership, and Users), you have mastered the multi-user architecture of Linux, learned how user identities are tracked via Numerical User IDs (UIDs) and Group IDs (GIDs), audited your session credentials using whoami and id, and safely elevated your administrative privileges using su and sudo.
You now understand who you are on the system and how to acquire administrative superpowers. But as a system administrator, your responsibilities extend far beyond running commands—you must build, maintain, and secure the user ecosystem itself. When new developers join your team, when services need isolated runtime accounts, or when user credentials and group memberships change, you need a precise administrative toolkit.
In this section, we examine the three foundational user management utilities in Linux: useradd (creating accounts), usermod (modifying existing accounts), and passwd (managing authentication credentials).
Part 1: Provisioning New Accounts — The useradd Command
The useradd command is a low-level administrative utility used by the system to create new user accounts.
useradd[options]username
When you execute useradd, it does not interactively prompt you for a password or automatically set up a home directory unless you explicitly instruct it to via option flags. Instead, it acts as a precise provisioning engine that writes user records directly into system configuration files like /etc/passwd, /etc/shadow, /etc/group, and /etc/gshadow.
Behind the Scenes: Where User Data Lives
When useradd creates a user, it updates four core system files:
- /etc/passwd: Stores account metadata (username, encrypted password placeholder x, UID, GID, full name / comment field, home directory path, and default login shell).
- /etc/shadow: Stores secure, encrypted password hashes along with password expiration and aging policies (accessible only by root).
- /etc/group: Defines system groups and their member lists.
- /etc/gshadow: Manages secure group passwords and administrative lists.
Default System Configuration Defaults
When you run useradd without options, it consults default configuration templates located at /etc/default/useradd and /etc/login.defs. These files dictate default behaviors, such as whether a home directory should be created, what base UID numbering starts at (typically 1000), and what default shell is assigned (usually /bin/bash).
Essential Options and Flags for useradd
Common`useradd`Options
| Option | Flag Name | Description |
| -m, –create-home | Create Home Directory | Automatically creates the user’s home directory in /home/username and populates it with skeleton configuration files (.bashrc, .profile). |
| -d PATH, –home-dir=PATH | Custom Home Directory | Specifies a custom home directory path instead of the default /home/username. |
| -s SHELL, –shell=SHELL | Default Shell | Assigns a specific login shell interpreter (e.g., /bin/bash, /bin/zsh, or /sbin/nologin for service accounts). |
| -g GROUP, –gid=GROUP | Primary Group | Assigns the user to a specific existing primary group (by name or GID) instead of creating a private user group. |
| -G GROUPS, –groups=GROUPS | Supplementary Groups | Adds the user to a comma-separated list of secondary (supplementary) groups. |
| -u UID, –uid=UID | Custom UID | Assigns a specific numerical User ID to the account instead of auto-incrementing the next available UID. |
| -c “COMMENT”, –comment=COMMENT | User Info / GECOS | Adds a text comment or description (such as the user’s full name, department, or contact info) into /etc/passwd. |
| -r, –system | System Account | Creates a low-UID system account (typically under UID 1000) intended for background daemons and services rather than human login. |
Comprehensive Hands-on Practice & Examples (useradd)
Example 1: Creating a Standard Human User Account
To provision a new developer named Sarah with a home directory, bash shell, and full name comment:
sudo useradd -m -s /bin/bash -c “Sarah Jenkins, Development Team” sarah
What happens under the hood:
- The system allocates the next available UID (e.g., 1001).
- A private primary group named sarah (GID 1001) is created.
- A home directory /home/sarah is created, and skeleton files are copied from /etc/skel/.
- An entry is added to /etc/passwd.
- (Note: Because no password was set, Sarah cannot log in yet until passwd is executed).
Example 2: Creating a Restricted System Service Account (-r)
When deploying a database or background application that requires an isolated runtime account without login privileges or a standard home directory:
sudo useradd -r -s /sbin/nologin -c “PostgreSQL Service Account” postgres
The -r flag assigns a low system UID, and -s /sbin/nologin ensures the account cannot be used for interactive SSH logins.
Part 2: Modifying Existing Accounts — The usermod Command
User accounts are dynamic. Employees change departments, usernames require correction, shells must be upgraded, and group memberships expand over time. Rather than deleting and recreating accounts, administrators use the usermod command to modify existing user properties safely.
usermod[options]username
Essential Options and Flags for usermod
Common`usermod`Options
| Option | Flag Name | Description |
| -l NEW, –login=NEW | Change Username | Renames the user account from the old username to a new username. |
| -d PATH, –home=PATH | Change Home Directory | Updates the recorded home directory path in /etc/passwd. (Combine with -m to move existing files to the new location). |
| -s SHELL, –shell=SHELL | Change Shell | Updates the user’s default login shell interpreter. |
| -g GROUP, –gid=GROUP | Change Primary Group | Reassigns the user’s primary group ID. |
| -aG GROUPS, –append –groups | Add to Supplementary Groups | Crucial Flag Combination: Appends the user to specified secondary groups without removing them from their existing supplementary groups. |
| -L, –lock | Lock Account | Locks the user account by prefixing its password hash in /etc/shadow with an exclamation point (!), preventing login. |
| -U, –unlock | Unlock Account | Unlocks a locked account by removing the exclamation point prefix. |
Comprehensive Hands-on Practice & Examples (usermod)
Example 1: Adding a User to Supplementary Groups (-aG)
Suppose you need to grant user sarah administrative execution rights by adding her to the sudo group and a project group named developers:
sudo usermod -aG sudo,developers sarah
⚠️ Critical Warning: Never use -G alone without the append flag (-a). If you run usermod -G sudo sarah without -a, the system will overwrite her entire supplementary group list, removing her from all other groups she previously belonged to! Always use -aG.
Example 2: Changing a User’s Default Login Shell
If a user requests to switch their default shell from Bash to Zsh (/bin/zsh):
sudo usermod -s /bin/zsh sarah
Example 3: Locking and Unlocking Accounts (-L and -U)
If an employee goes on extended leave or an account is flagged for security review:
# Lock the account immediately
sudo usermod -L sarah
# Restore access when returning
sudo usermod -U sarah
Part 3: Managing Authentication and Passwords — The passwd Command
When you create a user with useradd, the account has no active password hash, making login impossible. To establish, update, or audit authentication credentials, Linux provides the passwd command.
passwd[options][username]
- As a Standard User: Running plain passwd prompts you to change your own password (requiring your current password verification).
- As the Root Administrator: Running sudo passwd username allows you to set or reset any user’s password instantly without knowing their old password.
Essential Options and Flags for passwd
Common`passwd`Options
| Option | Flag Name | Description |
| -d, –delete | Delete Password | Deletes the user’s password entirely, making the account passwordless (extremely insecure; use with caution). |
| -l, –lock | Lock Password | Locks the user’s password hash in /etc/shadow. |
| -u, –unlock | Unlock Password | Unlocks the password hash. |
| -e, –expire | Expire Password | Forces the user’s password to expire immediately, requiring them to create a new password upon their next login. |
| -S, –status | Password Status | Displays a status report for the account (showing whether the password is locked, its aging status, and encryption algorithm). |
Comprehensive Hands-on Practice & Examples (passwd)
Example 1: Setting a Password for a Newly Created User
After running useradd, you must assign an initial password:
sudo passwd sarah
You will be prompted to enter and confirm the new password for user sarah.
Example 2: Forcing Password Expiration on Next Login (-e)
If corporate security policy requires an employee to change their temporary password immediately upon their first login:
sudo passwd -e sarah
Example 3: Auditing Account Password Status (-S)
To check the encryption status and aging metrics of an account:
sudo passwd -S sarah
Expected Output:
sarah P 11/06/2026 0 999 7 -1
(This output indicates that user sarah has a usable password P, last updated on November 6, 2026, with zero days minimum age and 999 days maximum retention).
Summary Checklist for User Management
- [ ] Use useradd -m to provision new user accounts along with home directories and skeleton configuration files.
- [ ] Use useradd -r to create restricted system service accounts.
- [ ] Use usermod -aG to safely append users to supplementary groups without wiping existing group memberships.
- [ ] Use usermod -s and usermod -l to modify login shells and usernames.
- [ ] Use passwd to set or reset user passwords (administrators can manage any account via sudo passwd username).
- [ ] Use passwd -e to force password rotation upon a user’s next login.
Section 4.4: Decoding File Permissions — The Anatomy of ls -l and the rwx Model
Throughout the first three chapters and the opening sections of Chapter 4, you have mastered filesystem navigation, file manipulation, stream redirection, text filtering, system identity, and user provisioning (useradd, usermod, passwd, su, sudo). You know who you are on the system, how to escalate privileges, and how to manage the human accounts that inhabit a Linux environment.
Now, we arrive at the absolute core of operating system security: Discretionary Access Control (DAC).
When multiple users and background services share a single Linux machine, how does the kernel prevent a standard user from reading another user’s private documents, tampering with system binaries, or deleting critical configuration files? The answer lies in file permissions. Every file and directory on a Linux filesystem is guarded by a rigid, elegant security matrix.
In this section, we examine how to inspect that security matrix using the long listing format (ls -l) and decode the meaning of read, write, and execute permissions across owners, groups, and others.
Part 1: Inspecting Permissions with ls -l
In Chapter 1, you learned how to list directory contents using ls. When you add the long listing flag (-l), ls transforms its output from a simple list of filenames into a detailed administrative audit table.
ls-l[filename/path]
Dissecting a Long Listing Line
Let’s examine a typical line generated by ls -l:
-rwxr-xr– 1 alex developers 4096 Nov 7 14:30 script.sh
Reading this line from left to right, each column represents a distinct metadata attribute:
- -rwxr-xr– (The Permission String & File Type): A 10-character string defining the file type and exact access permissions.
- 1 (Link Count): The number of hard links pointing to this file or directory.
- alex (File Owner): The specific user account (UID) that owns the file.
- developers (File Group): The designated group (GID) associated with the file.
- 4096 (File Size): The size of the file measured in bytes.
- Nov 7 14:30 (Modification Timestamp): The exact date and time the file was last modified.
- script.sh (Filename): The name of the file or directory.
Part 2: Decoding the 10-Character Permission String
The most critical component of the long listing is the 10-character permission string on the far left (e.g., -rwxr-xr–). This string is divided into four distinct segments:
[FileType][UserPermissions][GroupPermissions][OthersPermissions]
– rwx r-x r–
│ │ │ └── Others permissions (Read and Execute only)
│ │ └────── Group permissions (Read and Execute only)
│ └────────── User / Owner permissions (Read, Write, and Execute)
└───────────── File Type indicator (Regular file)
1. The File Type Indicator (Character 1)
The very first character indicates the file classification:
- –: Regular file (text documents, scripts, binaries, images).
- d: Directory (a folder containing other files).
- l: Symbolic link (a shortcut pointing to another file or path).
- b / c: Block or character device files (hardware interfaces in /dev).
2. The Three Security Triads (Characters 2 through 10)
The remaining nine characters are broken into three sets of three characters (triads). Each triad governs a specific class of user:
- Characters 2–4 (User / Owner): Applies exclusively to the individual user who owns the file.
- Characters 5–7 (Group): Applies to all users who belong to the file’s assigned group.
- Characters 8–10 (Others / World): Applies to everyone else on the system (any user who is neither the owner nor a member of the group).
Part 3: The Permission Triad (r, w, x)
Within each triad, permissions are represented by specific letters indicating whether an action is permitted or denied. If a permission is granted, its corresponding letter appears; if it is denied, it is replaced by a hyphen (-).
TheThreeCorePermissions
| Symbol | Permission Name | Effect on Files | Effect on Directories |
| r | Read | Allows viewing/reading the contents of the file (e.g., using cat, less, or opening in an editor). | Allows listing the contents (filenames) inside the directory (e.g., running ls). |
| w | Write | Allows modifying, appending to, or overwriting the file contents, or deleting the file. | Allows creating new files, deleting files, and renaming files inside that directory. |
| x | Execute | Allows running the file as a program, script, or system command. | Allows traversing (entering/CDing into) the directory, accessing its internal file paths. |
Part 4: The Crucial Nuance — Execute Permissions on Directories
One of the most common points of confusion for newcomers is understanding what “execute” (x) means for a directory.
- Read (r) alone on a directory allows you to see the names of the files inside it (via ls), but it does not give you permission to read those files, copy them, or enter the directory.
- Execute (x) on a directory grants traversal access. It allows you to use cd to enter the folder and access files inside it, provided you know their filenames (even if r is disabled and you cannot list the directory contents).
- Therefore, Read and Execute (r-x) are almost always paired together on directories so users can enter them and see what is inside.
Comprehensive Hands-on Practice & Examples
Let’s examine several real-world permission strings to understand how the Linux kernel evaluates access requests.
Example 1: Full Administrative Access (rwx——)
-rwx—— 1 root root 1024 Nov 7 09:00 secure_script.sh
User (rwx): The owner (root) has full read, write, and execute permissions.- Group (—): Members of the file’s group have zero access.
- Others (—): All other system users have zero access.
- Verdict: This file is completely private, accessible exclusively by its owner.
Example 2: Standard Executable Script (rwxr-xr-x)
-rwxr-xr-x 1 alex developers 2048 Nov 7 10:15 deployment_tool
User (rwx): Owner alex can read, modify, and execute the script.- Group (r-x): Members of the developers group can read and execute the script, but cannot modify it.
- Others (r-x): Any general system user can also read and execute the script.
- Verdict: A shared utility script that everyone can run, but only the owner can edit.
Example 3: Private Configuration File (rw-r—–)
-rw-r—– 1 postgres postgres 512 Nov 7 11:00 database.conf
User (rw-): Owner postgres can read and write to the configuration file.- Group (r–): Members of the postgres group can read the file (useful for monitoring daemons).
- Others (—): Unauthorized users have absolute zero access.
- Verdict: Sensitive database configuration protected from public viewing.
Summary Checklist for File Permissions
- [ ] Use ls -l to display the detailed long listing format, revealing file permissions, owners, groups, and sizes.
- [ ] The 10-character permission string defines the file type (-, d, l) followed by three security triads: User, Group, and Others.
- [ ] Read (r), Write (w), and Execute (x) control access to file data and directory traversal.
- [ ] Directory permissions behave differently than file permissions: execute (x) controls directory traversal (cd), while read (r) controls content listing (ls).
Section 4.5: Modifying File Permissions — The chmod Command
As we continue advancing through Chapter 4 (Permissions, Ownership, and Users), you have mastered the theoretical foundations of Linux security. You understand how user identities are tracked via UIDs and GIDs, how to escalate privileges using su and sudo, how to provision and modify user accounts (useradd, usermod, passwd), and—most importantly—how to inspect the security matrix of any file or directory using the long listing format (ls -l).
You can look at a long listing output like -rwxr-xr– and immediately decode that the owner has read, write, and execute permissions; group members have read and execute permissions; and others have read-only access.
However, knowing how to read permissions is only half the battle. As a system administrator, developer, or power user, you will frequently need to change those permissions. You may need to lock down a sensitive configuration file so no one else can read it, make a custom shell script executable so it can run as a command, or configure a shared project directory for a team of developers.
To modify the access permissions of files and directories, Linux provides the quintessential permission-management utility: chmod, short for change mode.
What is chmod?
The chmod command is used to alter the access permissions of files and directories, modifying the security triads (r, w, x) that govern users, groups, and others.
chmod[options]modefile(s)
When you run chmod, the Linux kernel intercepts your request, updates the inode metadata associated with the target file or directory, and instantly changes the 10-character permission string displayed in ls -l.
There are two primary methods for specifying permissions with chmod:
- Numeric (Octal) Mode: Setting permissions using base-8 numbers (e.g., 755, 644).
- Symbolic Mode: Modifying permissions using letters and mathematical operators (e.g., u+x, go-w).
Part 1: Numeric (Octal) Mode — The Binary Math of Permissions
While symbolic mode is intuitive for quick tweaks, system administrators frequently rely on numeric (octal) mode for precision, automation, and shell scripting.
To understand numeric mode, you must look beneath the letters (r, w, x) and examine the underlying binary bits that the Linux kernel evaluates.
The Three-Bit Binary Foundation
Every permission triad in the ls -l output (rwx) can be represented as a three-bit binary number, where each bit corresponds to a specific permission:
- The first bit represents Read (r) (Value: 4).
- The second bit represents Write (w) (Value: 2).
- The third bit represents Execute (x) (Value: 1).
When a permission is active, its binary bit is 1 (and its value is counted); when it is disabled, its bit is 0 (value 0).
OctalPermissionCalculationTable
| Binary Bit | Decimal Value | Permission Letter | Meaning |
| 100 | 4 | r | Read permitted |
| 010 | 2 | w | Write permitted |
| 001 | 1 | x | Execute permitted |
By adding the values of the active permissions together within a triad, you arrive at a single digit between 0 and 7.
Combining the Triads into a 3-Digit Octal Code
Because every file has three distinct permission triads (User, Group, and Others), a full numeric chmod mode consists of three octal digits:
chmod[User][Group][Others]filename
Let’s calculate common octal permission codes:
- 7 (Binary 111): Read (4) + Write (2) + Execute (1) = Full permissions.
- 5 (Binary 101): Read (4) + Write (0) + Execute (1) = Read and Execute.
- 6 (Binary 110): Read (4) + Write (2) + Execute (0) = Read and Write.
- 4 (Binary 100): Read (4) + Write (0) + Execute (0) = Read-only.
- 0 (Binary 000): No permissions whatsoever.
Essential Octal Permission Standards
In Unix and Linux systems, three standard octal permission profiles appear constantly across system administration:
- 755(Owner:rwx, Group:r-x, Others:r-x):
- Usage: Standard for executable programs, shell scripts, and public directories. The owner can modify the file, while everyone else can read and execute it.
- Usage: Standard for executable programs, shell scripts, and public directories. The owner can modify the file, while everyone else can read and execute it.
- 644(Owner:rw-, Group:r–, Others:r–):
- Usage: The universal standard for regular text files, documents, configuration files, and web pages. The owner can read and write, while everyone else has read-only access.
- Usage: The universal standard for regular text files, documents, configuration files, and web pages. The owner can read and write, while everyone else has read-only access.
- 700(Owner:rwx, Group:—, Others:—):
- Usage: Private files, secure scripts, and private user directories (like ~/.ssh). Only the owner has access; all other users on the system are completely locked out.
- Usage: Private files, secure scripts, and private user directories (like ~/.ssh). Only the owner has access; all other users on the system are completely locked out.
Comprehensive Hands-on Practice & Examples (Octal Mode)
Example 1: Making a Script Executable (chmod 755)
Suppose you write a new Bash automation script named deploy.sh. When you run ls -l, its permissions look like this:
-rw-r–r– 1 alex alex 350 Nov 7 16:00 deploy.sh
Notice that it lacks execute permissions (x). If you try to run ./deploy.sh, the shell will return a “Permission Denied” error.
To grant execute permissions to yourself while allowing others to read and run it:
chmod 755 deploy.sh
Verifying the result with ls -l:
-rwxr-xr-x 1 alex alex 350 Nov 7 16:00 deploy.sh
(The permission string has successfully updated to rwxr-xr-x).
Example 2: Securing a Private Document (chmod 600)
Suppose you are storing sensitive API tokens or private notes in a file named secrets.txt. You want to ensure that even if other users log into the same machine, they cannot read your file:
chmod 600 secrets.txt
Verifying with ls -l:
-rw——- 1 alex alex 120 Nov 7 16:15 secrets.txt
User has read and write (6), while group and others have zero permissions (0).
Part 2: Symbolic Mode — Modifying Permissions by Target and Operator
While octal mode requires defining all three permission triads at once, symbolic mode allows you to make surgical, targeted adjustments without altering existing permissions.
Symbolic mode expressions are constructed using three components: Target, Operator, and Permission.
chmod[target][operator][permission]filename
1. Targets (Who are you modifying?)
- u (User): The owner of the file.
- g (Group): Members of the file’s assigned group.
- o (Others): All other users on the system.
- a (All): Shorthand for all three targets simultaneously (ugo).
2. Operators (How are you modifying them?)
- + (Add): Adds the specified permission to the target without touching existing permissions.
- – (Remove): Revokes the specified permission from the target.
- = (Set Exactly): Overwrites existing permissions, setting them to the exact specified state.
3. Permissions (What permission is being modified?)
- r (Read)
- w (Write)
- x (Execute)
Comprehensive Hands-on Practice & Examples (Symbolic Mode)
Example 1: Adding Execute Permission to an Owner (u+x)
If you want to make a script executable for the owner only, without changing group or other permissions:
chmod u+x script.sh
The owner gains execute permission (+x), while all other existing permissions remain completely undisturbed.
Example 2: Removing Write Access for Everyone (a-w)
To protect a shared directory or document from accidental modification by anyone (making it read-only across the board):
chmod a-w shared_notes.txt
Example 3: Assigning Multiple Symbolic Rules
You can combine multiple modifications in a single command by separating them with commas:
chmod u=rwx,g=rx,o=r document.txt
This explicitly sets the owner to rwx, the group to r-x, and others to r– (achieving the exact equivalent of chmod 754).
Part 3: Recursive Permission Changes (-R)
Often, when managing directories that contain hundreds of nested subdirectories and files, you need to apply permission changes across the entire directory tree at once.
For this task, chmod provides the recursive flag (-R).
chmod-Rmodedirectory/path
Example: Securing a Web Project Directory
If you want to ensure that all files and folders inside a web project directory (/var/www/html/myproject) are readable by the web server while securing executable scripts:
chmod -R 755 /var/www/html/myproject
chmod recursively traverses every internal file and subdirectory, applying the 755 permission mask to the entire project tree.
Summary Checklist for chmod
- [ ] Use chmod to modify file and directory access permissions, directly altering the output of ls -l.
- [ ] Use Numeric (Octal) Mode (chmod 755 file) for precise, scriptable three-digit permission sets based on binary weight values (r=4, w=2, x=1).
- [ ] Master standard octal profiles: 755 for executables/directories, 644 for standard files, and 700 for private assets.
- [ ] Use Symbolic Mode (chmod u+x file) for targeted, incremental adjustments using targets (u, g, o, a) and operators (+, -, =).
- [ ] Use chmod -R to apply permission changes recursively across entire directory trees.
Section 4.6: Changing File Ownership and Group Membership — The chown and chgrp Commands
As we continue advancing through Chapter 4 (Permissions, Ownership, and Users), you have mastered the foundational mechanics of Linux security. You understand how user identities are tracked via UIDs and GIDs, how to audit sessions using whoami and id, how to elevate privileges with su and sudo, how to provision and manage user accounts (useradd, usermod, passwd), how to interpret permission strings (rwx), and how to modify access modes using numeric and symbolic chmod.
When you run ls -l, every file and directory displays two crucial administrative columns right after the link count:
- The File Owner: The specific user account (UID) that holds primary ownership over the asset.
- The File Group: The designated group (GID) associated with the asset, granting shared access to all members of that group.
-rw-r–r– 1 alex developers 4096 Nov 7 14:30 project_spec.txt
│ │ └── File Group (developers)
│ └──────── File Owner (alex)
└───────────────────── Permission string
However, file ownership is not static. When a developer leaves a team, when project files are transferred between users, or when system installation scripts create files owned by root that need to be handed over to a runtime service account (like www-data or postgres), you must change who owns and controls those files.
To manage ownership and group associations, Linux provides two dedicated administrative utilities: chown (change owner) and chgrp (change group).
Part 1: Changing File Ownership and Groups — The chown Command
The chown command (short for change owner) is a powerful administrative utility used to change the user owner—and optionally the group owner—of files and directories.
chown[options]new_owner[:new_group]file(s)
How chown Works Under the Hood
When you execute chown, the operating system updates the inode metadata of the target file, replacing the stored numeric User ID (UID) with the UID of the new owner.
The Superuser Restriction (root Only)
Unlike chmod (where a regular user can change permissions on any file they own), standard users cannot freely give away ownership of their files to other users using chown.
- Why? Allowing regular users to transfer file ownership would undermine disk quota systems and security accounting (a malicious user could dump massive files onto another user’s account to bypass disk usage limits or frame them for unauthorized data storage).
- The Rule: Only the all-powerful root administrator (or a user wielding sudo privileges) can change the user owner of a file. (However, a user can change a file’s group owner to another group they belong to).
Essential Options and Flags for chown
Common`chown`Options
| Option | Flag Name | Description |
| -R, –recursive | Recursive Operation | Recursively changes ownership across all files and subdirectories within a directory tree. |
| -v, –verbose | Verbose Output | Prints a diagnostic message for every file whose ownership is successfully modified. |
| -c, –changes | Changes Only | Similar to verbose, but outputs messages only when an actual ownership change is made. |
| –reference=RFILE | Reference File | Copies the user and group ownership of a reference file (RFILE) and applies it to the target files. |
Comprehensive Hands-on Practice & Examples (chown)
Example 1: Changing File Ownership
Suppose you created a configuration file as root, but you need to assign its ownership to the user alex:
sudo chown alex app_config.ini
Verifying with ls -l:
-rw-r–r– 1 alex root 512 Nov 7 17:00 app_config.ini
The user owner column has successfully changed from root to alex.
Example 2: Changing Owner and Group Simultaneously
The chown syntax allows you to change both the user owner and the group owner in a single command by separating them with a colon (:):
chownowner:groupfilename
sudo chown alex:developers app_config.ini
This command assigns user ownership to alex and group ownership to developers simultaneously.
Example 3: Changing Group Ownership Only Using chown
If you omit the username and place a colon directly before a group name (or simply use a dot), chown will change only the group owner:
sudo chown :developers app_config.ini
(This achieves the exact same group-assignment result as the chgrp command).
Example 4: Recursive Ownership Changes for Web Directories (-R)
When deploying a web application into a public directory like /var/www/html, all files must be owned by the web server service account (such as www-data on Ubuntu/Debian) so the server can read and execute them:
sudo chown -R www-data:www-data /var/www/html/my_webapp
chown -R recursively traverses every internal file and subdirectory within my_webapp, reassigning both user and group ownership to www-data in a single operation.
Part 2: Changing Group Membership Only — The chgrp Command
While chown can modify both user and group ownership, Linux also provides a dedicated, specialized utility designed exclusively for changing group associations: chgrp (short for change group).
chgrp[options]new_groupfile(s)
How chgrp Works Under the Hood
The chgrp command updates the group ID (GID) associated with a file’s inode metadata.
Group Membership Security Constraints
Unlike changing user ownership (which requires strict root privileges), a regular user can run chgrp to change a file’s group only if:
- They are the owner of the file, and
- They are an active member of the target group they are assigning the file to.
If a user attempts to assign a file to a group they do not belong to, the kernel rejects the request with a “Operation not permitted” error.
Essential Options and Flags for chgrp
Common`chgrp`Options
| Option | Flag Name | Description |
| -R, –recursive | Recursive Operation | Recursively changes group ownership across entire directory trees. |
| -v, –verbose | Verbose Output | Prints diagnostic messages for every file modified. |
| -c, –changes | Changes Only | Reports files whose group ownership was actually altered. |
| –reference=RFILE | Reference File | Copies the group ownership from a reference file and applies it to targets. |
Comprehensive Hands-on Practice & Examples (chgrp)
Example 1: Changing a File’s Group
Suppose you have a shared project report named budget.xlsx owned by user alex, and you want to assign it to the finance group so that all finance team members can access it:
chgrp finance budget.xlsx
Verifying with ls -l:
-rw-r—– 1 alex finance 15360 Nov 7 17:30 budget.xlsx
The group column has successfully updated to finance.
Example 2: Recursive Group Assignment Across Project Directories (-R)
If you are collaborating on a shared code repository located in /srv/projects/alpha and need to ensure all project files belong to the developers group:
sudo chgrp -R developers /srv/projects/alpha
All internal files and folders are recursively assigned to the developers group.
Summary Checklist for chown and chgrp
- [ ] Use chown to change the user owner (and optionally the group owner) of files and directories.
- [ ] Changing user ownership with chown requires administrative root (sudo) privileges for security and disk quota integrity.
- [ ] Use chown owner:group filename to update both user and group ownership in a single command.
- [ ] Use chgrp to change group ownership specifically.
- [ ] Regular users can use chgrp to change a file’s group only if they own the file and belong to the target group.
- [ ] Use -R (recursive flag) with both commands to manage ownership across entire directory trees.
Section 4.7: Default Permission Masks — The umask Command
As we continue advancing through Chapter 4 (Permissions, Ownership, and Users), you have mastered the complete lifecycle of file security. You know how user identities are tracked via UIDs and GIDs, how to escalate privileges safely using su and sudo, how to provision and manage human and system accounts (useradd, usermod, passwd), how to inspect permission strings (rwx), how to modify existing permissions using octal and symbolic chmod, and how to reassign user and group ownership using chown and chgrp.
Up to this point, all our permission management has been reactive: you create a file or directory, and afterwards, you modify its permissions to secure it.
However, this raises a vital operational question: When you create a brand-new file or directory from scratch—such as saving a document in an editor, compiling a script, or writing a log file via an application—what permissions does that asset start with automatically?
Who decides whether a new file is born as 644, 755, or 777?
The answer lies in one of the most fundamental yet misunderstood security mechanisms in Linux: the umask (User Mask).
What is umask?
The umask command (short for user file-creation mode mask) is a shell builtin and system-level setting that determines the default access permissions granted to newly created files and directories.
umask[octal_mask]
When any process or user creates a new file or directory, the Linux kernel does not assign permissions randomly. Instead, it takes a baseline maximum permission set and subtracts (or masks out) the bits specified by the current user’s umask.
The Baseline Starting Points: Files vs. Directories
To understand how umask calculates final permissions, you must know the raw maximum permissions the Linux kernel assigns upon creation before any mask is applied:
- Maximum File Permission Baseline:666 (Read and Write for User, Group, and Others).
- Security Note: For safety reasons, the Linux kernel deliberately strips execute permissions (x) from all newly created files by default. No file is ever born automatically executable unless explicitly modified afterward via chmod.
- Security Note: For safety reasons, the Linux kernel deliberately strips execute permissions (x) from all newly created files by default. No file is ever born automatically executable unless explicitly modified afterward via chmod.
- Maximum Directory Permission Baseline:777 (Read, Write, and Execute for User, Group, and Others).
- Note: Because directories require execute permission (x) to allow traversal (cd), directories retain their full execute bits in the baseline.
- Note: Because directories require execute permission (x) to allow traversal (cd), directories retain their full execute bits in the baseline.
How umask Math Works: Octal Subtraction
The umask value acts as a permission blocker. Each octal digit in your umask represents the permissions you want to remove (or “mask out”) from the maximum baseline.
FinalPermission=BaselineMaximum-UmaskValue
Let’s examine how this works using the standard default umask found on most Linux distributions: 022.
Example 1: Calculating File Permissions with Umask 022
- Baseline File Permission: 666 (rw-rw-rw-)
- Umask: 022 (—-w–w-)
Subtracting the umask bits from the baseline octal digit by digit:
- User (Owner): 6 – 0 = 6 (rw-)
- Group: 6 – 2 = 4 (r–)
- Others: 6 – 2 = 4 (r–)
Result: Every new file created under a 022 umask is born with permissions 644 (rw-r–r–).
Example 2: Calculating Directory Permissions with Umask 022
- Baseline Directory Permission: 777 (rwxrwxrwx)
- Umask: 022 (—-w–w-)
Subtracting digit by digit:
- User (Owner): 7 – 0 = 7 (rwx)
- Group: 7 – 2 = 5 (r-x)
- Others: 7 – 2 = 5 (r-x)
Result: Every new directory created under a 022 umask is born with permissions 755 (rwxr-xr-x).
The Danger of Odd Umask Digits (Bitwise Subtraction)
In standard arithmetic, subtraction is straightforward. However, octal permission masking is actually a bitwise operation (baseline AND (NOT umask)).
While simple subtraction (6 – 2 = 4) works fine for even numbers like 0, 2, or 4, problems arise if a umask contains an odd number (such as 027 or 077).
Example: Calculating Umask 027 on a File
- Baseline File Permission: 666 (rw-rw-rw-)
- Umask: 027 (—-w-rwx)
If you attempt simple decimal subtraction on the “Others” digit (6 – 7), you get -1, which breaks octal math.
Under bitwise masking:
- 6 in binary is 110 (Read + Write).
- 7 in binary is 111 (Read + Write + Execute).
- Stripping bits 111 from 110 leaves 000.
Result:
- File permissions become 640 (rw-r—–).
- Directory permissions become 750 (rwxr-x—).
Inspecting Your Current Umask
To view your active shell session’s current umask setting, run the command without arguments:
umask
Expected Output:
0022
(The leading zero represents special permission bits like setuid/setgid, which we will explore later; the active mask is 022).
Viewing Umask in Symbolic Format (-S)
If octal numbers are difficult to visualize, you can view your umask using human-readable symbolic notation by passing the -S (symbolic) flag:
umask -S
Expected Output:
u=rwx,g=rx,o=rx
(This output shows what permissions are allowed to remain active on new directories).
Changing Your Umask
You can modify your umask during an active terminal session by passing a new octal value to the command:
umask 027
Scope and Persistence
- Session Scope: Changing umask directly in your terminal applies only to your current shell session and any child processes spawned within it. Once you close your terminal or log out, the setting resets.
- Persistent Configuration: To permanently alter your default umask for future logins, you must add the umask command to your user shell configuration profile (such as ~/.bashrc, ~/.bash_profile, or system-wide in /etc/profile or /etc/login.defs).
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical scenarios to see how different umask settings dictate file creation security across real-world workflows.
Example 1: The Standard Shared Environment (umask 022)
In standard development environments where team members need to read each other’s scripts and code files, 022 is the universal default.
umask 022
touch test_file.txt
mkdir test_dir
ls -ld test_file.txt test_dir
Expected Output:
-rw-r–r– 1 alex alex 0 Nov 7 18:00 test_file.txt
drwxr-xr-x 2 alex alex 4096 Nov 7 18:00 test_dir
Files are born as 644, and directories are born as 755.
Example 2: The Secure Private Environment (umask 077)
If you are handling sensitive financial data, private cryptographic keys, or confidential documents, you want to ensure that no other user on the system can read your newly created files under any circumstances.
Set the umask to 077 (which strips all read, write, and execute permissions from both group and others):
umask 077
touch private_notes.txt
mkdir private_folder
ls -ld private_notes.txt private_folder
Expected Output:
-rw——- 1 alex alex 0 Nov 7 18:15 private_notes.txt
drwx—— 2 alex alex 4096 Nov 7 18:15 private_folder
File Permissions: 600 (rw——-) — Only you can read or write to the file.- Directory Permissions: 700 (rwx——) — Only you can enter or view the folder.
Example 3: The Collaborative Team Environment (umask 002)
Suppose you are working on a collaborative project where you want members of your primary group to have full read and write access to any new files you create automatically, without needing to run chmod manually every time.
Set umask to 002:
umask 002
touch shared_doc.txt
ls -l shared_doc.txt
Expected Output:
-rw-rw-r– 1 alex developers 0 Nov 7 18:30 shared_doc.txt
Files are born as 664 (rw-rw-r–), granting immediate write access to group members.
Summary Checklist for umask
- [ ] Use umask to inspect or set the default permission mask applied to newly created files and directories.
- [ ] The maximum permission baseline for files is 666 (with execute bits stripped for safety), and for directories is 777.
- [ ] Umask values represent the permissions subtracted from the baseline maximums (Baseline – Umask = Final Permission).
- [ ] Standard 022 umask results in 644 files and 755 directories.
- [ ] Secure 077 umask results in 600 files and 700 directories (completely private to the owner).
- [ ] Use umask -S to view allowed permissions in human-readable symbolic format.
- [ ] Session changes apply immediately but temporarily; add umask to shell configuration files (~/.bashrc) for persistence.
Congratulations! You have successfully completed Chapter 4. You have mastered the foundational security model of Linux, moving from understanding user identities to enforcing strict access controls and managing system accounts.
Let’s review the core concepts and administrative utilities you’ve mastered throughout this chapter:
- Identity and System Architecture: Understanding UIDs, GIDs, and multi-user environments using whoami and id.
- Privilege Escalation: Safely elevating rights using traditional su (login shells) and modern audited sudo.
- User Provisioning and Management: Creating and modifying accounts and credentials using useradd, usermod, and passwd.
- File Permission Analysis: Decoding long listing security strings (ls -l) across User, Group, and Others triads (rwx), including directory traversal mechanics.
- Permission Modification: Adjusting access modes using numeric octal codes (755, 644) and symbolic targets with chmod.
- Ownership Management: Reassigning user and group ownership with chown and chgrp.
- Default Security Masks: Controlling automatic file and directory creation permissions using umask.
You now possess a professional administrative skillset to secure systems, manage users, and configure precise access boundaries.
Chapter 5: Process Management and System Monitoring
Section 5.1: Capturing System State — The ps Command and Process Snapshots
Throughout Chapters 1 through 4, you have mastered the physical geography of the Linux filesystem (pwd, ls, cd), text inspection (cat, less, grep), stream redirection (>, >>, |), system security, user provisioning (useradd, usermod), file permissions (chmod), ownership (chown), and default masks (umask). You know how to build secure file hierarchies and manage the human and service accounts that inhabit them.
Now, we cross a major threshold in system administration and engineering: Chapter 5: Process Management and System Monitoring.
When a Linux system runs, it does not merely store files on disk; it executes processes—active, running instances of programs consuming CPU cycles, memory allocations, network sockets, and input/output channels. As a system administrator or developer, you must know how to inspect what is happening inside your machine’s memory in real time, track down runaway scripts, audit resource hogs, and manage task lifecycles.
In this section, we begin our study of process monitoring by exploring the quintessential snapshot utility: ps.
What is a Process? (Programs vs. Processes)
Before examining ps, let’s clarify a foundational operating system distinction:
- A Program: Is a static file sitting on your storage disk (such as /bin/ls, /usr/bin/python3, or /usr/sbin/nginx). It is passive, dormant code.
- A Process: Is a program in active execution. When you launch a program, the Linux kernel loads its binary instructions into RAM, allocates memory space, opens file descriptors, assigns security credentials, and creates a dynamic Process Control Block (PCB).
Every single process on a Linux system is identified by a unique positive integer known as a Process ID (PID). Furthermore, processes form a strict familial hierarchy: every process is spawned by another process, creating Parent PIDs (PPIDs). At the absolute top of this hierarchy sits system initialization (typically systemd, bearing PID 1), which spawns all subsequent user and system processes.
What is ps?
The ps command (short for process status) is a command-line utility used to generate a static snapshot of the processes currently running on the system.
ps[options]
Unlike interactive resource monitors that update continuously in real time, ps takes an instantaneous photograph of kernel process tables at the exact microsecond it is executed, prints the result to standard output (stdout), and exits immediately.
The Three Syntax Flavors of ps
One of the historical quirks that trips up newcomers is that ps supports three distinct styling syntaxes, inherited from decades of Unix evolution:
- UNIX / POSIX Options: Preceded by a single dash (e.g., -ef, -aux).
- BSD Options: Used without any dashes (e.g., aux, ef).
- GNU Long Options: Preceded by double dashes (e.g., –forest, –pid).
While this flexibility can cause confusion, learning how to combine these styles unlocks immense diagnostic power.
Part 1: BSD-Style Comprehensive Snapshots (ps aux)
One of the most widely used commands in Linux administration is ps aux.
ps aux
When you execute ps aux (using BSD syntax without dashes), the system prints a massive table detailing every single process running across the entire operating system, regardless of which user owns them.
Decoding the ps aux Output Columns
Let’s examine the headers generated by ps aux:
USER PID %CPU %MEM VSZ RSS TTY STAT START TIME COMMAND
root 1 0.0 0.4 169280 13428 ? Ss Nov07 0:05 /sbin/init
alex 1420 1.2 1.8 942104 74210 ? Sl Nov07 2:14 /usr/lib/gnome-terminal
USER: The user account that owns and executed the process.- PID: The unique Process ID number.
- %CPU: The percentage of CPU time consumed by the process relative to total available CPU capacity.
- %MEM: The percentage of physical RAM utilized by the process.
- VSZ (Virtual Memory Size): The total amount of virtual memory allocated to the process in kilobytes.
- RSS (Resident Set Size): The exact amount of physical RAM currently being consumed by the process in kilobytes (excluding swapped-out pages).
- TTY: The controlling terminal associated with the process (e.g., pts/0 for a terminal window, or ? if the process runs as a background daemon detached from any terminal).
- STAT: The current Process State Code (indicating whether the process is running, sleeping, stopped, or a zombie).
- START: The exact time or date the process was launched.
- TIME: The total cumulative CPU time consumed by the process since it started (not elapsed wall-clock time).
- COMMAND: The exact command string and arguments used to launch the process.
Part 2: Understanding Process States (STAT Codes)
The STAT column in ps output provides vital diagnostic clues regarding what a process is currently doing. A state code is often a multi-character string:
CoreProcessStates
| Code | State Name | Description |
| R | Running / Runnable | The process is actively running on a CPU core or waiting in the kernel run queue. |
| S | Interruptible Sleep | The process is waiting for an event to complete (such as user input, network packet arrival, or disk I/O). This is the most common state. |
| D | Uninterruptible Sleep | The process is waiting for hardware I/O (usually disk storage) and cannot be killed or interrupted until the operation finishes. |
| Z | Zombie / Defunct | A terminated child process whose parent has not yet read its exit status. It consumes no CPU/RAM but clogs the process table. |
| T | Stopped / Traced | The process has been paused (suspended) by a job control signal (e.g., pressing Ctrl + Z) or debugging tracer. |
Additional State Modifiers
- <: High-priority process (nice negative value).
- N: Low-priority “nice” process.
- s: Session leader (manages a group of child processes).
- l: Multi-threaded process (uses multiple execution threads).
- +|: Foreground process group member.
Part 3: UNIX/POSIX-Style Full System Listing (ps -ef)
Another industry standard is the UNIX-style syntax ps -ef:
ps -ef
Decoding the ps -ef Output Columns
UID PID PPID C STIME TTY TIME CMD
root 1 0 0 Nov07 ? 00:00:05 /sbin/init
alex 1420 1400 0 Nov07 ? 00:02:14 /usr/lib/gnome-terminal
Notice the key differences compared to ps aux:
- UID: Displays the numeric or symbolic user ID of the owner.
- PPID: Displays the Parent Process ID, allowing you to trace which process spawned another.
- C: Processor utilization factor (CPU scheduling weight).
- STIME: Start time.
- CMD: The full command path and arguments.
Part 4: Advanced Filtering and Customization
Because ps can return thousands of active system processes, piping its output into grep or utilizing built-in filters is essential for effective administration.
1. Filtering by User (-u)
To inspect only the processes owned by a specific user account:
ps -u alex
2. Displaying Process Hierarchies (–forest)
To visualize parent-child process relationships graphically as an ASCII tree:
ps -ef –forest
3. Customizing Output Columns (-o)
If you want to isolate specific metrics without cluttering your screen with unwanted columns, use the -o (output format) flag:
ps -eo pid,ppid,%cpu,%mem,comm –sort=-%cpu
pid,ppid,%cpu,%mem,comm: Selects only Process ID, Parent PID, CPU usage, Memory usage, and command name.- –sort=-%cpu: Sorts the output automatically in descending order (-) by CPU consumption, putting the highest resource hogs directly at the top.
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how ps operates across everyday system administration workflows.
Example 1: Finding a Running Process by Name
Suppose you are running a Python script or a web server and want to find its specific Process ID (PID) without scrolling through hundreds of lines:
ps aux | grep python3
(Combined with the pipe and grep utilities you mastered in Chapter 3, ps instantly isolates the matching process line).
Example 2: Identifying the Top CPU Consumers
If your system is running hot and you want to see which processes are hoarding CPU cycles, sort the output using custom formatting:
ps -eo pid,user,%cpu,%mem,command –sort=-%cpu | head -n 10
This pipeline isolates the top 10 most CPU-intensive processes on your entire system, displaying their PID, owner, CPU percentage, memory consumption, and command.
Example 3: Tracing Parent-Child Relationships
If you notice a strange background process running and want to know what program launched it, check its Parent PID (PPID):
ps -ef | grep 2480
By noting the PPID value, you can inspect the parent process to understand how the task was initiated.
Summary Checklist for ps
- [ ] Use ps to capture a static, instantaneous snapshot of active system processes and their kernel states.
- [ ] Master ps aux (BSD style) for comprehensive system auditing displaying CPU, memory, and runtime statistics.
- [ ] Master ps -ef (UNIX style) for tracking Parent Process IDs (PPIDs) and process ownership.
- [ ] Understand process state codes (R for running, S for sleeping, D for uninterruptible disk wait, Z for zombie).
- [ ] Use ps -ef –forest to visualize process trees graphically.
- [ ] Use ps -eo [columns] –sort=[metric] to customize output fields and sort processes by resource consumption.
Section 5.2: Interactive System Monitors — The top and htop Commands
In the previous section, we explored the static process snapshot utility ps, learning how to capture instantaneous kernel process tables, inspect CPU and memory utilization metrics, track process state codes (R, S, D, Z), and trace parent-child hierarchies (PPIDs).
While ps is indispensable for scripting, automated auditing, and quick point-in-time checks, it suffers from a fundamental limitation: it is static. If a runaway background process spikes CPU utilization to 100% two seconds after you run ps aux, your terminal will not show it unless you manually re-run the command or wrap it inside an infinite monitoring loop (like watch).
When you need to actively diagnose performance bottlenecks, investigate real-time resource spikes, identify misbehaving memory leaks, and dynamically terminate rogue processes on the fly, you need an interactive system monitor.
In this section, we examine the two primary interactive monitoring tools in Linux: top (the traditional classic) and htop (the modern, feature-rich visual enhancement).
Part 1: The Classic Real-Time Monitor — The top Command
The top command (short for table of processes or top processes) is a real-time, interactive system monitoring utility built into virtually every Unix and Linux distribution.
top[options]
When you execute top, your terminal transforms into a live dashboard that updates every few seconds, streaming real-time statistics regarding CPU load, memory consumption, swap utilization, and an actively sorted table of running processes.
Dissecting the top Dashboard Interface
When you launch top, the screen is divided into two distinct zones: the System Summary Header (top rows) and the Process Task Table (bottom rows).
top – 09:28:00 up 14 days, 3:12, 2 users, load average: 0.45, 0.62, 0.78
Tasks: 245 total, 1 running, 244 sleeping, 0 stopped, 0 zombie
%Cpu(s): 5.2 us, 1.8 sy, 0.0 ni, 92.5 id, 0.3 wa, 0.1 hi, 0.1 si, 0.0 st
MiB Mem : 7894.2 total, 2140.5 free, 3412.1 used, 2341.6 buff/cache
MiB Swap: 2048.0 total, 2048.0 free, 0.0 used, 4120.4 avail Mem
PID USER PR NI VIRT RES SHR S %CPU %MEM TIME+ COMMAND
1420 alex 20 0 942104 74210 42100 S 2.3 0.9 2:14.20 gnome-terminal
2810 root 20 0 412040 24120 18420 S 1.0 0.3 0:15.82 nginx
1 root 20 0 169280 13428 9120 S 0.0 0.4 0:05.12 systemd
1. The Summary Header Breakdown
- Line 1 (System Status & Load Averages):
- Current system time (09:28:00), total uptime (14 days), active user count (2 users).
- Load Averages (0.45, 0.62, 0.78): Represent the average number of processes in the run queue or waiting for disk I/O over the last 1, 5, and 15 minutes, respectively. On a single-core CPU, a load of 1.0 means 100% capacity; on multi-core systems, divide the load by your total CPU core count to gauge true system stress.
- Current system time (09:28:00), total uptime (14 days), active user count (2 users).
- Line 2 (Task Summary): Total active processes, along with how many are running, sleeping, stopped, or defunct (zombies).
- Line 3 (CPU Utilization Metrics):
- us (User space CPU time), sy (System / Kernel space CPU time), ni (Nice / low-priority user processes), id (Idle CPU capacity—higher is better), wa (Wait time for I/O operations—high wa indicates disk bottlenecks), hi/si (Hardware and software interrupt handling), and st (Steal time stolen by hypervisors in virtualized cloud environments).
- us (User space CPU time), sy (System / Kernel space CPU time), ni (Nice / low-priority user processes), id (Idle CPU capacity—higher is better), wa (Wait time for I/O operations—high wa indicates disk bottlenecks), hi/si (Hardware and software interrupt handling), and st (Steal time stolen by hypervisors in virtualized cloud environments).
- Lines 4 & 5 (Memory and Swap): Total physical RAM, free memory, used memory, and memory allocated to buffer/cache, alongside swap space utilization.
2. The Process Task Table Columns
- PID: Process ID.
- USER: Effective owner of the process.
- PR & NI: Priority and Niceness values governing CPU scheduling priority.
- VIRT, RES, SHR: Virtual memory, Resident physical memory, and Shared memory allocations.
- S: Process state (R, S, D, Z).
- %CPU & %MEM: Real-time percentage of CPU and RAM utilization.
- TIME+: Total cumulative CPU execution time with centisecond precision.
- COMMAND: Executable name or launch arguments.
Interactive Keyboard Commands Inside top
While top is running, you can press various single-letter keys to manipulate the display, resort data, and control processes without restarting the utility:
Interactive`top`Hotkeys
| Key | Action / Effect |
| h or ? | Opens the interactive help screen listing all available commands. |
| q | Quits and exits top, returning you to your terminal prompt. |
| k | Kill a Process: Prompts you to enter a PID and a signal number (e.g., 15 for graceful termination or 9 for forceful destruction). |
| r | Renice a Process: Changes the scheduling priority (niceness) of a target PID. |
| P | Sorts the process table dynamically by CPU utilization (default behavior). |
| M | Sorts the process table dynamically by Memory consumption (%MEM). |
| T | Sorts processes by cumulative execution time (TIME+). |
| c | Toggles command display between absolute executable names and full command-line arguments. |
| u | Filters the process list to show only processes owned by a specific username. |
| d | Changes the screen refresh update delay interval (in seconds). |
| 1 | Toggles between aggregate total CPU summary and individual multi-core CPU breakdown (Cpu0, Cpu1, etc.). |
Essential Options and Flags for top
Common`top`StartupFlags
| Option | Flag Name | Description |
| -d SECONDS | Delay Interval | Sets the screen refresh rate (e.g., top -d 1 updates every 1 second). |
| -u USER | User Filter | Starts top pre-filtered to display only processes owned by the specified user. |
| -p PID1,PID2 | Process Isolation | Monitors only the specified PIDs, ignoring all other system activity. |
| -b | Batch Mode | Runs top in non-interactive batch mode (ideal for piping output into log files or monitoring scripts). |
Comprehensive Hands-on Practice & Examples (top)
Example 1: Monitoring a Specific User’s Processes
If you want to audit resource consumption exclusively for user postgres or www-data upon launch:
top -u www-data
The process table displays only the web server’s runtime worker processes.
Example 2: High-Speed Diagnostics (-d 1)
If you are troubleshooting a sudden performance spike and need real-time updates every 1 second instead of the default 3 seconds:
top -d 1
Part 2: The Modern Visual Enhancer — The htop Command
While top is universally available on every Linux system, it has remained text-based and spartan for decades. To overcome these limitations, modern system administrators frequently turn to htop.
The htop utility is an interactive, cross-platform process viewer designed as a modern replacement for top.
htop
Why htop Revolutionized System Monitoring
Unlike the monochrome text layout of traditional top, htop provides several massive quality-of-life advantages:
- Full Color Visual Meters: htop renders graphical, color-coded bar meters at the top of your screen for CPU cores, memory bars, and swap space, making resource usage instantly readable at a glance.
- Mouse Navigation: Unlike top, which relies strictly on keyboard shortcuts, htop supports mouse clicking. You can click on column headers to sort processes instantly or click on a specific process row to select it.
- Horizontal and Vertical Scrolling: If command arguments or environment strings exceed your terminal width, htop allows you to scroll horizontally using arrow keys.
- Intuitive Function Key Bar: The bottom of the screen features a persistent interactive menu mapped to function keys (F1 for Help, F2 for Setup, F3 for Search, F4 for Filter, F5 for Tree View, F9 for Kill, F10 for Quit), eliminating the need to memorize cryptic single-letter keystrokes.
- Built-in Process Tree View (F5): Pressing F5 instantly reorganizes the process table into an interactive ASCII process tree, clearly displaying parent-child relationships without needing complex ps flags.
Comprehensive Hands-on Practice & Examples (htop)
Example 1: Launching htop in Tree View Mode (-t)
If you want to inspect process hierarchies immediately upon startup:
htop –tree
The interface opens with parent and child processes nested neatly together.
Example 2: Isolating Processes for a Specific User
To launch htop filtered to a specific user account:
htop -u alex
Summary Checklist for top and htop
- [ ] Use top for a classic, real-time interactive system monitoring dashboard available on every Linux installation.
- [ ] Understand the summary header metrics: load averages, task states, CPU breakdowns (us, sy, id, wa), and memory allocations.
- [ ] Master interactive top hotkeys: P (sort by CPU), M (sort by Memory), k (kill process), u (filter user), and 1 (toggle CPU cores).
- [ ] Use htop for a modern, color-coded, mouse-navigable interactive monitor featuring graphical meters and built-in process trees (F5).
Section 5.3: System Health and Kernel Auditing — The uptime and uname Commands
As we continue exploring Chapter 5 (Process Management and System Monitoring), you have mastered both static process snapshots via ps and dynamic, interactive resource tracking using top and htop. You know how to monitor CPU and memory utilization, interpret process states (R, S, D, Z), track parent-child process relationships (PPIDs), and adjust or terminate misbehaving processes on the fly.
However, monitoring a Linux system requires more than just tracking individual running tasks. As a system administrator, site reliability engineer, or developer, you must also understand the global state of the operating system:
- How long has this machine been running continuously without a reboot?
- Is the overall system load trending upward or stabilizing over time?
- What exact version of the Linux kernel is actively running under the hood?
- What hardware architecture or distribution build is this operating system compiled for?
To answer these high-level infrastructural questions instantly, Linux provides two foundational, lightweight diagnostic utilities: uptime (system load and runtime duration) and uname (kernel and architecture identification).
Part 1: Tracking System Load and Uptime — The uptime Command
The uptime command is a core administrative utility used to display how long the operating system has been running, how many user sessions are currently active, and the system’s average computational workload over recent time intervals.
uptime[options]
When executed without arguments, uptime reads runtime statistics directly from the /proc virtual filesystem (specifically /proc/uptime and /proc/loadavg) and prints a single, concise status line to standard output (stdout).
Decoding the uptime Output Line
Let’s examine a typical output generated by running uptime:
10:15:42 up 42 days, 18:24, 3 users, load average: 0.15, 0.42, 0.88
Reading this output line from left to right, each segment provides critical health metrics:
- 10:15:42 (Current System Time): The current wall-clock time according to the system clock.
- up 42 days, 18:24 (Uptime Duration): The total continuous duration the system has been powered on and running since its last reboot or power-on event (here, 42 days, 18 hours, and 24 minutes).
- 3 users (Active User Sessions): The number of logged-in user accounts currently holding active terminal sessions or SSH connections.
- load average: 0.15, 0.42, 0.88 (System Load Averages): The average number of runnable or uninterruptible processes requesting CPU or disk resources over the past 1 minute, 5 minutes, and 15 minutes, respectively.
Demystifying System Load Averages
Of all the metrics reported by uptime (as well as top), load average is one of the most vital yet frequently misunderstood concepts in performance auditing.
What Does “System Load” Actually Mean?
System load is not simply a CPU percentage. Instead, it measures queue depth—the total number of processes that are either:
- Actively executing on a CPU core,
- Waiting in the CPU run queue for an available processing slice (State R), or
- Waiting for uninterruptible disk I/O operations to complete (State D).
Interpreting Load Numbers Relative to CPU Cores
To evaluate whether a load average is healthy or dangerous, you must compare the load numbers to the total number of logical CPU cores present on your system:
- Single-Core System (1 CPU):
- Load = 0.50: The single CPU core is 50% utilized; the system is running comfortably.
- Load = 1.00: The single CPU core is at 100% capacity. Every processing cycle is fully occupied, but no tasks are queuing up.
- Load = 2.50: The CPU is overwhelmed. For every task being processed, an average of 1.5 other tasks are sitting stalled in line waiting for execution.
- Load = 0.50: The single CPU core is 50% utilized; the system is running comfortably.
- Multi-Core System (e.g., 4 CPUs):
- Load = 1.00: Across 4 cores, overall system processing capacity is only at 25%.
- Load = 4.00: All 4 CPU cores are operating at 100% capacity.
- Load = 8.00: The 4-core machine is running at double its capacity; performance will noticeably degrade.
- Load = 1.00: Across 4 cores, overall system processing capacity is only at 25%.
Analyzing Load Trends Over Time
By comparing the 1-minute, 5-minute, and 15-minute load metrics provided by uptime, you can determine the trajectory of system stress:
- 0.15, 0.42, 0.88 (Trending Down): Load was high 15 minutes ago (0.88), but has dropped significantly in the last minute (0.15). The spike is subsiding.
- 2.50, 1.10, 0.30 (Trending Up): Load was low 15 minutes ago (0.30), but has rapidly escalated in the last minute (2.50). A performance spike or resource leak is actively occurring.
Essential Options and Flags for uptime
Common`uptime`Options
| Option | Flag Name | Description |
| -p, –pretty | Pretty Format | Displays system uptime in a simplified, human-readable text format (e.g., up 6 weeks, 0 days). |
| -s, –since | Up Since | Displays the exact timestamp and date when the system was booted (YYYY-MM-DD HH:MM:SS). |
| -h, –help | Help Menu | Prints usage guidelines and exits. |
| -V, –version | Version Info | Outputs utility version details. |
Comprehensive Hands-on Practice & Examples (uptime)
Example 1: Human-Readable Duration Check (-p)
When writing system audit reports or quick shell scripts, you may want to display pure uptime without load metrics:
uptime -p
Expected Output:
up 6 weeks, 0 days, 18 hours, 24 minutes
Example 2: Checking System Boot Time (-s)
To determine the exact historical moment a server was last restarted:
uptime -s
Expected Output:
2026-09-26 15:51:18
Part 2: Kernel and Hardware Inspection — The uname Command
While uptime monitors runtime load, system administrators also need to verify system architecture details—especially when compiling software, troubleshooting kernel modules, installing device drivers, or auditing security vulnerabilities.
For this purpose, Linux provides the uname command (short for unix name).
uname[options]
When executed without flags, uname simply prints the operating system kernel name (usually Linux). However, combining uname with its various options unlocks detailed diagnostic data about kernel releases, hostnames, hardware architectures, and processor types.
Essential Options and Flags for uname
Common`uname`Options
| Option | Flag Name | Description |
| -a, –all | All Information | Prints all system and kernel information in a single space-separated line. |
| -s, –kernel-name | Kernel Name | Prints the system kernel name (e.g., Linux). |
| -n, –nodename | Network Hostname | Prints the network node hostname of the system. |
| -r, –kernel-release | Kernel Release | Prints the active operating system kernel release version (e.g., 6.8.0-45-generic). |
| -v, –kernel-version | Kernel Build Version | Prints the compilation timestamp and build version details of the kernel. |
| -m, –machine | Hardware Architecture | Prints the machine hardware architecture (e.g., x86_64, aarch64, armv7l). |
| -p, –processor | Processor Type | Prints the processor architecture type or unknown. |
| -i, –hardware-platform | Hardware Platform | Prints the hardware platform identifier or unknown. |
| -o, –operating-system | Operating System | Prints the high-level operating system name (e.g., GNU/Linux). |
Comprehensive Hands-on Practice & Examples (uname)
Example 1: Full System Audit (uname -a)
The most common usage of uname in enterprise troubleshooting is the all-inclusive audit flag -a:
uname -a
Expected Output:
Linux webserver01 6.8.0-45-generic #45-Ubuntu SMP PREEMPT_DYNAMIC Fri Oct 17 12:00:00 UTC 2026 x86_64 x86_64 x86_64 GNU/Linux
Decoding the uname -a Output:
- Linux: Kernel name.
- webserver01: System network hostname.
- 6.8.0-45-generic: Exact kernel release version.
- #45-Ubuntu SMP PREEMPT_DYNAMIC…: Kernel build compilation version and timestamp.
- x86_64: Hardware architecture (64-bit Intel/AMD instruction set).
- GNU/Linux: High-level operating system specification.
Example 2: Isolating the Kernel Version for Driver Installation (uname -r)
When installing third-party kernel modules (like graphics drivers or virtual virtualization drivers), installation scripts often require the exact active kernel release string. You can isolate this string using -r:
uname -r
Expected Output:
6.8.0-45-generic
Example 3: Verifying Machine Architecture (uname -m)
Before downloading software binaries compiled for specific hardware architectures (such as distinguishing between traditional 64-bit PCs and 64-bit ARM processors like Raspberry Pi or cloud ARM instances):
uname -m
Expected Output (on standard 64-bit Intel/AMD systems):
x86_64
Expected Output (on 64-bit ARM systems):
aarch64
Summary Checklist for uptime and uname
- [ ] Use uptime to inspect continuous operational runtime, active user sessions, and 1-, 5-, and 15-minute system load averages.
- [ ] Understand load averages: compare load numbers to your system’s total logical CPU core count to evaluate system stress.
- [ ] Use uptime -p for clean, human-readable uptime strings, and uptime -s to display the exact system boot timestamp.
- [ ] Use uname to query kernel release versions and underlying hardware platform architectures.
- [ ] Master uname -a for comprehensive kernel identity audits.
- [ ] Use uname -r to isolate kernel release versions and uname -m to check machine hardware architecture (x86_64 vs. aarch64).
Section 5.4: Controlling Processes — Signals, kill, pkill, and killall
As we continue exploring Chapter 5 (Process Management and System Monitoring), you have mastered the art of observation. Through ps, top, htop, uptime, and uname, you can capture instantaneous process snapshots, diagnose real-time CPU and memory bottlenecks, track system load trends, and audit kernel releases.
However, monitoring a system is only half the battle. Sooner or later, every administrator or developer encounters a misbehaving process: a runaway Python script caught in an infinite loop consuming 100% CPU, a database daemon stalled in an uninterruptible sleep state, a hung web server worker refusing to release port 80, or a memory leak bloating RAM until the system OOM (Out-Of-Memory) killer threatens to panic the kernel.
When observation is no longer enough, you must intervene. You need to control, pause, or terminate processes safely and decisively.
In this section, we examine the core mechanism of process control in Unix and Linux: signals, and the three essential utilities used to dispatch them—kill, pkill, and killall.
Part 1: The Anatomy of Linux Signals
In Linux, processes do not operate in a vacuum. The kernel and user applications communicate through signals—asynchronous notification messages sent to a running process to alert it that a specific event has occurred.
Think of a signal as a software-level interrupt. When a process receives a signal, it interrupts its normal execution flow and executes a predefined signal handler (either cleaning up files, saving state, pausing, or terminating immediately).
Standard Signals Every Administrator Should Know
While Linux defines over thirty distinct signals, system administration revolves around a handful of core signals. Every signal has both a numerical ID and a symbolic name (usually prefixed with SIG).
CoreLinuxSignalsReferenceTable
| Signal Name | Numeric ID | Default Action | Description & Common Use Case |
| SIGHUP | 1 | Terminate | Hangup: Originally signaled when a telephone line dropped; now widely used by daemons (like Nginx or SSH) to reload their configuration files without restarting. |
| SIGINT | 2 | Terminate | Interrupt: Sent when you press Ctrl + C in your terminal. Asks the foreground process to gracefully abort and shut down. |
| SIGQUIT | 3 | Dump Core | Quit: Sent when you press Ctrl + \. Asks the process to terminate and dump a core memory file for debugging. |
| SIGKILL | 9 | Force Kill | Kill: Caught directly by the kernel. Cannot be ignored, caught, or cleaned up. Instantly destroys the process. Use only as a last resort. |
| SIGTERM | 15 | Terminate | Termination: The standard, polite request to terminate. Asks the process to clean up its state and exit gracefully. (This is the default signal sent by kill). |
| SIGSTOP | 19 | Stop / Pause | Stop: Pauses process execution immediately. Cannot be caught or ignored. |
| SIGCONT | 18 | Resume | Continue: Resumes execution of a process previously paused by SIGSTOP. |
Part 2: Targeting by Process ID — The kill Command
The most fundamental process-control utility in Linux is kill.
Despite its aggressive name, kill does not inherently “destroy” a process; its primary job is to send a signal to a process.
kill[-signal]PID(s)
How kill Works Under the Hood
- You invoke kill and provide a target Process ID (PID) along with an optional signal specifier.
- The kernel verifies your user permissions (you can only signal processes you own, unless you are root).
- The kernel delivers the specified signal to the target process’s Process Control Block.
- The process handles the signal according to its design.
Essential Options and Flags for kill
Common`kill`OptionsandSignalingSyntax
| Syntax / Flag | Description |
| kill PID | Sends the default SIGTERM (Signal 15) to the specified PID. |
| kill -9 PID or kill -SIGKILL PID | Sends the forceful, uncatchable SIGKILL (Signal 9) to terminate immediately. |
| kill -15 PID or kill -SIGTERM PID | Explicitly sends the graceful termination signal SIGTERM. |
| kill -1 PID or kill -SIGHUP PID | Sends SIGHUP to instruct a daemon to reload its configuration files. |
| kill -l | Lists all available signal names and numbers supported by your kernel. |
Comprehensive Hands-on Practice & Examples (kill)
Example 1: Graceful Termination (SIGTERM)
Suppose you have a background process running with PID 4820 that has hung or stopped responding. Always start with a polite request to terminate (SIGTERM):
kill 4820
The process receives signal 15, flushes its log buffers, closes active socket connections, and exits cleanly.
Example 2: Forceful Termination (SIGKILL)
If a process is completely unresponsive and ignores SIGTERM, you must escalate to the uncatchable SIGKILL (Signal 9):
kill -9 4820
⚠️ Critical Warning: Because SIGKILL is handled entirely by the kernel without giving the process a chance to run its cleanup handlers, any unsaved work in that process is instantly lost, and temporary files or database locks may be left orphaned. Use -9 only when graceful termination fails.
Example 3: Reloading a Daemon Configuration Without Downtime (SIGHUP)
Suppose you modify your web server configuration file (nginx.conf) and want the running Nginx master process (PID 1100) to reload its settings without dropping active client connections:
sudo kill -HUP 1100
Nginx intercepts SIGHUP, gracefully reloads its configuration files in memory, and continues running uninterrupted.
Part 3: Targeting by Name and Pattern — The pkill Command
While kill is precise, it requires you to look up the exact numeric Process ID (PID) beforehand using ps or top.
When you want to send signals to processes based on their command names or pattern matches without manually checking PIDs, Linux provides pkill.
pkill[options]pattern
How pkill Works Under the Hood
pkill combines process searching and signal dispatch into a single streamlined operation. It queries the kernel process table, matches pattern strings against process command names, and dispatches the specified signal to all matching PIDs automatically.
Essential Options and Flags for pkill
Common`pkill`Options
| Option | Flag Name | Description |
| -u USER, –uniquely-owned | User Filter | Targets only processes owned by a specific user account. |
| -t TTY, –terminal | Terminal Filter | Targets processes associated with a specific terminal (e.g., pts/1). |
| -n, –newest | Newest Process | Selects only the most recently spawned process matching the pattern. |
| -o, –oldest | Oldest Process | Selects only the oldest process matching the pattern. |
| -s SIGNAL, –signal | Specify Signal | Defines the signal to send (e.g., pkill -9 python3 or pkill -SIGUSR1 process). |
Comprehensive Hands-on Practice & Examples (pkill)
Example 1: Terminating Processes by Name
Suppose you launched multiple instances of a testing script named load_test.py and want to terminate all of them immediately without looking up their individual PIDs:
pkill load_test.py
Every running process matching load_test.py receives a default SIGTERM signal and shuts down.
Example 2: Forcefully Killing All Processes Owned by a Specific User (-u)
If a user account (e.g., testuser) has left stray background processes running that are hoarding system resources, you can terminate them all in one command:
sudo pkill -9 -u testuser
The kernel forcefully kills every process owned by testuser across the system.
Part 4: Terminating All Instances — The killall Command
Similar to pkill, the killall command allows you to terminate processes by name rather than PID. However, while pkill uses regex pattern matching, killall targets processes matching an exact executable name.
killall[options]process_name
Essential Options and Flags for killall
Common`killall`Options
| Option | Flag Name | Description |
| -i, –interactive | Interactive Prompt | Prompts you for confirmation (y/N) before killing each matching process, preventing accidental terminations. |
| -v, –verbose | Verbose Output | Reports whether each signal was successfully delivered. |
| -u USER, –user | User Filter | Limits termination to processes owned by a specific user. |
| -s SIGNAL, –signal | Specify Signal | Specifies the signal to send (e.g., killall -s USR1 nginx). |
Comprehensive Hands-on Practice & Examples (killall)
Example 1: Safely Terminating All Instances of an Application
Suppose your desktop environment has frozen multiple instances of a web browser (e.g., firefox), and you want to shut them all down cleanly:
killall firefox
Example 2: Interactive Bulk Termination (-i)
When terminating critical services, accidental typos can be disastrous. Using the interactive flag (-i) forces killall to ask for verification before executing:
sudo killall -i nginx
Expected Output Prompt:
Kill process “nginx” (1100)? (y/N) y
Kill process “nginx” (1102)? (y/N) y
Summary Checklist for Process Control
- [ ] Use signals as software interrupts to communicate state changes or termination requests to running processes.
- [ ] Master core signals: SIGTERM (15) for polite, graceful shutdown; SIGKILL (9) for immediate, uncatchable force-kills; and SIGHUP (1) for reloading daemon configurations.
- [ ] Use kill PID to target specific processes by their Process ID.
- [ ] Use pkill pattern to search and terminate processes dynamically using name patterns and user filters (-u).
- [ ] Use killall name to terminate all exact instances of a program name, utilizing interactive mode (-i) for safety.
Section 5.5: Job Control — Managing Foreground and Background Execution
As we continue exploring Chapter 5 (Process Management and System Monitoring), you have mastered process observation (ps, top, htop, uptime, uname) and process termination (kill, pkill, killall). You know how to track resource consumption, interpret kernel states, and dispatch signals to rogue or unresponsive programs.
However, up to this point, our interaction with running commands has followed a strict, linear limitation: the foreground blocking model.
When you type a command in your terminal (such as compiling a large software package, running a database backup, or starting a long script) and press Enter, your shell becomes completely blocked. Your terminal prompt vanishes, your keyboard input is trapped by that single running program, and you cannot type another command until that process finishes executing.
If you want to run another command while the first one is still processing, you would traditionally have to open an entirely new terminal window or SSH session.
To overcome this bottleneck and give you multi-tasking control over your terminal sessions, Linux provides job control. In this section, we examine how the shell manages active execution threads, allowing you to seamlessly juggle multiple tasks using the ampersand (&), suspension (Ctrl + Z), the jobs table, and the bg and fg commands.
Understanding the Terminal Session Model
Before exploring job control commands, let’s understand how your shell categorizes processes during an interactive terminal session:
- Foreground Jobs: A process running interactively in your current terminal window. It holds direct control over your standard input (stdin) and standard output (stdout), reading keystrokes directly from your keyboard and printing text to your screen. Only one foreground job can occupy a terminal session at any given time.
- Background Jobs: A process running independently of direct keyboard interaction. While it may still output text to your terminal screen (unless redirected), it does not block your prompt; you can continue typing and executing new commands while background tasks execute concurrently.
Part 1: Launching Tasks Directly in the Background (&)
The simplest way to prevent a command from blocking your terminal is to launch it directly into the background from the very beginning.
To do this, you append the ampersand operator (&) to the end of your command string.
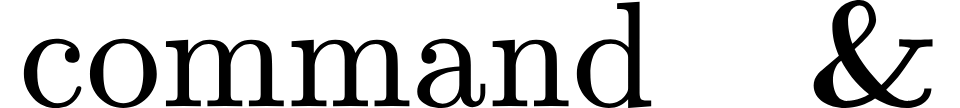
How the Ampersand Works Under the Hood
When the shell encounters the & symbol at the end of a command:
- It creates a new child process for the command just like normal.
- Instead of placing that child process into the active foreground session and handing over control of the keyboard, the shell immediately places the process into the background.
- The shell assigns a Job ID (enclosed in brackets, such as [1]) and reports the process’s numeric Process ID (PID).
- The shell immediately returns your command prompt ($), allowing you to type and execute subsequent commands while the background job runs concurrently.
Comprehensive Example: Background File Compression
Suppose you want to compress a massive directory containing hundreds of gigabytes of raw data using tar, which will take several minutes. Instead of locking up your terminal window:
tar -czf archive.tar.gz /var/data/raw_files/ &
Expected Output:
[1] 14820
[1]: The shell assigned this task Job ID 1.- 14820: The assigned Process ID (PID).
- Your command prompt returns instantly, allowing you to continue working while tar compresses the files in the background.
Part 2: Pausing and Suspending Running Tasks (Ctrl + Z vs. Ctrl + C)
What happens if you launch a long-running command without an ampersand, find your terminal blocked, and realize halfway through that you need your prompt back without killing the process?
Linux provides two essential keyboard interrupt shortcuts for managing active foreground tasks:
1. The Abort Signal (Ctrl + C)
When you press Ctrl + C, the terminal sends a SIGINT (Interrupt, Signal 2) to the foreground process.
- The Effect: It requests an immediate termination of the process, halting execution and returning your prompt. Use Ctrl + C when you want to kill or cancel a runaway task entirely.
2. The Suspension Signal (Ctrl + Z)
When you press Ctrl + Z, the terminal sends a SIGTSTP (Terminal Stop, Signal 20) to the foreground process.
- The Effect: It does not kill the process. Instead, it suspends (pauses) the process instantly in its current state, freezing its CPU and memory allocations, and places it into the background job table in a stopped state (Stopped).
Comprehensive Example: Suspending a Running Task
Suppose you run an interactive text editor or script:
nano configuration.conf
While editing, you realize you need to check a system log in the terminal. Instead of closing your editor, you press:
Ctrl + Z
Expected Output:
[1]+ Stopped nano configuration.conf
The editor is safely paused, and your command prompt is instantly restored.
Part 3: Inspecting Active Jobs (jobs)
Once you have launched tasks into the background using & or paused them using Ctrl + Z, how do you keep track of them?
For this purpose, the shell provides the jobs command.
jobs[options]
The jobs command queries the shell’s internal job table and lists every active background or suspended task associated with your current terminal session.
Decoding the jobs Output Table
When you run jobs -l, the shell displays a detailed status table:
[1]- Running tar -czf archive.tar.gz /var/data/ &
[2]+ Stopped nano configuration.conf
[1] and [2] (Job IDs): The local shell identifier numbers assigned to the jobs.- The Status Indicators (+and–):
- + (Plus Sign): Represents the current job—the task that will be acted upon by default if you run fg or bg without specifying a job ID.
- – (Minus Sign): Represents the previous job—the task that was current before the current job.
- + (Plus Sign): Represents the current job—the task that will be acted upon by default if you run fg or bg without specifying a job ID.
- Execution State: Displays whether the task is currently Running or Stopped.
- Command String: The exact command line used to launch the job.
Essential Options and Flags for jobs
Common`jobs`Options
| Option | Flag Name | Description |
| -l, –list | List with PIDs | Displays normal job information alongside their underlying Process IDs (PIDs). |
| -p, –pids-only | Pids Only | Prints only the Process IDs of the jobs, suppressing command strings. |
| -r, –running | Running Only | Filters the job table to display only tasks that are actively running. |
| -s, –stopped | Stopped Only | Filters the job table to display only tasks that are currently suspended. |
Part 4: Resuming Jobs in the Background (bg)
If you have suspended a task using Ctrl + Z (placing it into a Stopped state) and want to allow it to resume executing in the background without blocking your terminal prompt, you use the bg command (short for background).
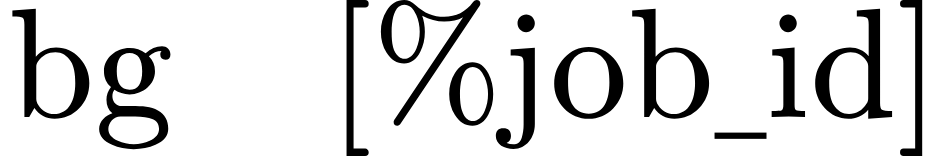
How bg Works Under the Hood
When you invoke bg %1 (referencing Job ID 1):
- The shell sends a SIGCONT (Continue) signal to the suspended process.
- The kernel wakes the process up from its frozen state.
- Because you invoked bg, the process is resumed as a background task, streaming output asynchronously while your prompt remains active.
Part 5: Returning Jobs to the Foreground (fg)
Conversely, if you launched a task in the background using &, or if you previously suspended a task using Ctrl + Z and now want to bring it back into the active foreground session to interact with it, you use the fg command (short for foreground).
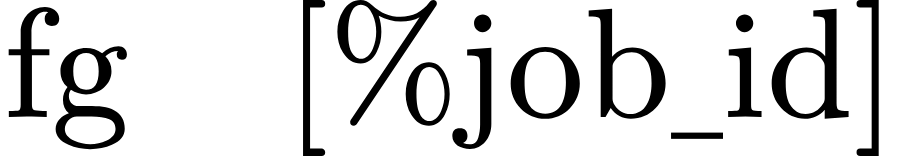
How fg Works Under the Hood
When you invoke fg %2 (referencing Job ID 2):
- The shell transfers control of the terminal’s keyboard and display to that specific job.
- If the job was suspended (Stopped), the shell sends a SIGCONT signal to resume its execution.
- The job takes over your active terminal window, becoming the sole foreground process.
Comprehensive Hands-on Practice & Examples
Let’s walk through a complete, real-world workflow combining &, Ctrl + Z, jobs, bg, and fg.
Scenario: Juggling Multiple Tasks in a Single Terminal
- Step 1: Launch a long task in the background: Suppose you want to run a system backup script in the background:
- Bash
./backup_script.sh &
The script runs silently in the background while your prompt stays active.- Step 2: Start an interactive task in the foreground: You open a configuration file to edit:
- Bash
nano /etc/hosts
Your terminal window is now occupied by nano.- Step 3: Suspend the foreground task: While editing, you need to check the status of your backup script. You press Ctrl + Z.
- nano is paused, and your prompt returns.
- nano is paused, and your prompt returns.
- Step 4: Check the job table: You run jobs -l to verify your active tasks:
- Bash
jobs -l
Expected Output:- Plaintext
[1] Running ./backup_script.sh &
[2]+ Stopped nano /etc/hosts
Step 5: Resume the editor in the background (if desired) or bring backup to foreground: Suppose you want to check if the backup script is still running smoothly by bringing it to the foreground:- Bash
fg %1
./backup_script.sh pops back into your active terminal window, displaying its output live.*
- Step 6: Clean termination: Once finished, you can let it complete or press Ctrl + C to terminate it, then return to your editor using fg %2.
Summary Checklist for Job Control
- [ ] Use Foreground jobs when a process requires active keyboard interaction (stdin) and terminal display control (stdout).
- [ ] Use Background jobs to run tasks concurrently without blocking your command prompt.
- [ ] Append & to any command to launch it directly into the background upon execution.
- [ ] Press Ctrl + C (SIGINT) to abort and terminate a running foreground task.
- [ ] Press Ctrl + Z (SIGTSTP) to pause a running foreground task and place it into a suspended state.
- [ ] Use jobs (or jobs -l) to inspect all active background and stopped tasks in your terminal session.
- [ ] Use bg %job_id to resume a suspended task in the background.
- [ ] Use fg %job_id to bring a background or suspended task back into active foreground interaction.
Section 5.6: Memory Monitoring and Resource Usage — The free Command
Throughout Chapter 5, you have mastered process observation (ps, top, htop), kernel and system health auditing (uptime, uname), process control and signaling (kill, pkill, killall), and interactive shell job management (jobs, bg, fg, &). You can track down CPU-intensive tasks, trace parent-child hierarchies, and manage active execution streams.
However, a modern Linux system is governed by two vital resource pillars: CPU capacity and Memory (RAM) allocation. While CPU bottlenecks manifest as high load averages and sluggish responsiveness, memory bottlenecks present a far more dangerous threat. If a server completely exhausts its physical RAM, applications begin crashing unpredictably, database engines abort queries, and the Linux kernel is forced to invoke its drastic OOM (Out-of-Memory) Killer to terminate critical processes arbitrarily in order to prevent total system panic.
Before memory exhaustion forces the kernel’s hand, you must know how to inspect, audit, and understand memory utilization across your system.
In this section, we examine the quintessential memory auditing utility: free.
What is free?
The free command is a lightweight command-line utility used to display the total amount of physical and swap memory available on the system, along with the amount of memory currently used and abused by running processes and kernel caches.
free[options]
When you execute free, the command reads raw memory statistics directly from the Linux kernel’s virtual memory inspection file located at /proc/meminfo, processes the byte counts, and formats them into a clean, human-readable status table.
Dissecting the free Output Table
When you run free in your terminal without any flags, the output resembles this:
total used free shared buff/cache available
Mem: 8124528 2412040 1542104 421520 4170384 5120412
Swap: 2097152 0 2097152
Let’s break down every column and row in detail to understand what these numbers actually mean.
The Rows
- Mem: (Physical RAM): Represents your computer’s main physical memory modules (DRAM installed on the motherboard).
- Swap: (Swap Space): Represents disk space (either a dedicated swap partition or a swap file) configured on storage media to act as overflow memory when physical RAM is exhausted.
- Total: (Optional Summary): When enabled via flags, displays a combined aggregate total of physical and swap memory.
The Columns
- total: The absolute maximum amount of usable physical RAM installed and recognized by the operating system (excluding kernel reserved memory overhead).
- used: Memory currently allocated and actively held by running programs, kernel structures, and shared libraries.
- free: Unallocated, completely empty memory sitting idle, waiting to be claimed by new applications.
- shared: Memory utilized by tmpfs (temporary filesystems stored directly in RAM) and inter-process communication (IPC) shared memory segments.
- buff/cache: Memory utilized by the Linux kernel to store filesystem disk buffers (metadata blocks) and page caches (recently accessed file contents read from disk).
- available: (The most important metric for system administrators). An estimation of how much physical memory is actually available for starting new applications without swapping data to disk.
The Great Misconception: Why “Free” Memory is Almost Always Low
One of the most common points of confusion for newcomers running the free command for the first time is seeing an alarmingly small number in the free column (e.g., only a few hundred megabytes left out of 16 gigabytes), leading them to panic that their system is out of memory.
This is entirely normal and represents healthy Linux behavior.
How Linux Kernel Caching Works
Unlike some operating systems that leave unused RAM sitting completely dormant, the Linux kernel operates on a core philosophy: “Unused memory is wasted memory.”
When you read files, compile code, execute database queries, or load web pages, the Linux kernel does not discard that data when the program finishes. Instead, it aggressively copies those file blocks into unused RAM (Page Cache and Buffers).
- If you need to read that file again later, the kernel serves it instantly from lightning-fast RAM rather than forcing a slow mechanical hard drive or SSD read.
- The Magic of Cache Reclamation: If a new application launches and suddenly demands 4 gigabytes of physical RAM, the Linux kernel instantly releases the necessary memory from its buff/cache pool in a fraction of a millisecond and hands it over to the application.
Therefore, never judge memory pressure by looking at the free column. Always evaluate memory health by looking at the available column. If available is robust and healthy, your system has plenty of room to breathe.
Essential Options and Flags for free
Common`free`Options
| Option | Flag Name | Description |
| -b, –bytes | Display in Bytes | Displays all memory statistics explicitly in raw bytes. |
| -k, –kibi | Display in Kilobytes | Displays statistics in kibibytes (KiB, default behavior). |
| -m, –mebi | Display in Megabytes | Displays statistics in mebibytes (MiB), making large numbers easier to read. |
| -g, –gibi | Display in Gigabytes | Displays statistics in gibibytes (GiB). |
| -h, –human | Human-Readable | Automatically scales memory figures into appropriate units with suffixes (B, K, M, G, T). |
| -s SECONDS, –seconds=SECONDS | Continuous Polling | Continuously refreshes the free output at specified second intervals (ideal for live monitoring). |
| -t, –total | Show Total Row | Appends a combined total row summing up Mem and Swap memory statistics. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical examples to see how free operates in everyday system administration workflows.
Example 1: Human-Readable Memory Audit (free -h)
By default, free outputs raw kilobyte integers, which require mental math to interpret. Using the human-readable flag (-h) automatically formats numbers into clean Megabytes and Gigabytes:
free -h
Expected Output:
total used free shared buff/cache available
Mem: 7.7Gi 2.3Gi 1.4Gi 411Mi 3.9Gi 4.8Gi
Swap: 2.0Gi B 2.0Gi
Interpretation: Out of 7.7 GiB total RAM, 2.3 GiB is actively used by applications, 3.9 GiB is dedicated to kernel disk caching (buff/cache), and 4.8 GiB is safely available for new workloads. Swap utilization is at zero.
Example 2: Continuous Real-Time Memory Monitoring (free -h -s 2)
If you suspect a memory leak in a running application and want to watch how memory consumption fluctuates over time, combine the human-readable flag (-h) with the continuous polling interval flag (-s for seconds):
free -h -s 2
The terminal clears and updates the memory status table every 2 seconds until you press Ctrl + C to exit.
Example 3: Auditing Swap Space Utilization
Swap space acts as a safety valve when physical RAM is exhausted. If your swap usage (used under the Swap row) begins climbing steadily alongside high CPU I/O wait times (wa), it indicates that your system is thrashing—constantly swapping memory pages back and forth to disk because it lacks sufficient physical RAM.
To inspect swap status specifically:
free -m | grep Swap
Expected Output:
Swap: 2048 0 2048
(Zero used swap indicates healthy physical RAM headroom).
Summary Checklist for free and Memory Usage
- [ ] Use free to inspect physical RAM and swap space utilization.
- [ ] Understand the core memory columns: total, used, free, and buff/cache.
- [ ] Always rely on the available column to assess true system memory headroom rather than looking at free.
- [ ] Remember that Linux aggressively utilizes unused RAM for kernel disk caching (buff/cache), which is automatically released when applications demand memory.
- [ ] Use free -h for clean, human-readable Megabyte and Gigabyte formatting.
- [ ] Use free -s [seconds] to monitor memory trends continuously in real time.
Section 5.7: Disk Space and Directory Usage — The df and du Commands
Throughout Chapter 5, you have mastered process monitoring (ps, top, htop), system load and kernel auditing (uptime, uname), process control and signaling (kill, pkill, killall), job control (jobs, bg, fg, &), and physical RAM and swap monitoring (free). You know how to track down CPU hogs, terminate unresponsive programs, manage background execution streams, and ensure your system has sufficient memory headroom.
However, monitoring a Linux system requires tracking one final, critical physical resource: persistent storage.
Even if your CPU load is minimal and your RAM utilization is healthy, a server can grind to a complete halt or suffer catastrophic data corruption if its physical storage drives run entirely out of space. Log files swell uncontrollably, databases fail to write transactions, temporary caches lock up, and applications crash when they can no longer allocate write buffers.
As a system administrator or developer, you must know how to answer two fundamental storage questions:
- How much total disk space is left across our mounted filesystems and partitions? (df)
- Which specific directories, folders, or files are greedily consuming all that storage space? (du)
In this section, we examine the two essential storage auditing utilities in Linux: df (Disk Free) and du (Disk Usage).
Part 1: Auditing Filesystem-Level Disk Space — The df Command
The df command (short for disk free) is a core system utility used to report the amount of disk space consumed and available across all mounted filesystems.
df[options][file/directory]
When executed without arguments, df queries the Linux kernel’s virtual filesystem tables, inspects every active storage mount point, and prints a structured summary table detailing block allocations, usage percentages, and mount directories.
Dissecting the df Output Table
Let’s examine a typical output generated by running standard df:
Filesystem 1K-blocks Used Available Use% Mounted on
/dev/sda2 102452800 42104200 55120400 44% /
tmpfs 4062264 100 4062164 1% /run
/dev/sdb1 512102400 380102400 106100000 79% /var/www/html
Let’s break down what each column represents:
- Filesystem: The physical block device, partition, or virtual driver associated with the storage volume (e.g., /dev/sda2).
- 1K-blocks: The total capacity of the filesystem measured in 1-kilobyte blocks.
- Used: The exact amount of storage space currently occupied by data.
- Available: The amount of storage space remaining and available for use by standard user applications.
- Use%: The percentage of total storage space currently occupied. (When this hits 100%, write operations fail immediately).
- Mounted on: The directory path in the filesystem tree where that storage volume is attached and accessible.
Essential Options and Flags for df
Common`df`Options
| Option | Flag Name | Description |
| -h, –human-readable | Human-Readable | Automatically scales storage sizes into intuitive units (K, M, G, T), replacing raw 1K-block counts. |
| -T, –print-type | Filesystem Type | Displays an extra column indicating the filesystem type (e.g., ext4, xfs, tmpfs, nfs). |
| -i, –inodes | Inode Usage | Audits inode consumption instead of block storage (crucial for tracking out-of-inode errors). |
| -a, –all | Include Pseudo-Filesystems | Displays all filesystems, including internal pseudo-filesystems with zero block size (like /proc or /sys). |
| -t TYPE, –type=TYPE | Filter by Type | Restricts output to a specific filesystem type (e.g., df -t ext4). |
Understanding Inodes (df -i)
One of the most insidious traps in Linux administration is encountering a “Disk Full” error when your normal storage check (df -h) claims you still have gigabytes of free space remaining.
This happens when you run out of inodes.
- What is an Inode? An inode (index node) is a data structure in a Unix-style filesystem that stores metadata about a file (its permissions, ownership, timestamps, and physical disk block locations) excluding its actual filename and data content.
- The Inode Limit: Every filesystem is created with a finite, pre-allocated number of inodes when it is formatted. If your application creates millions of microscopic files (such as thousands of tiny cache files, PHP sessions, or email queues), you can completely exhaust your available inodes long before your hard drive’s raw gigabytes are filled.
To check your inode consumption, use the -i flag:
df -ih
Expected Output:
Filesystem Inodes IUsed IFree IUse% Mounted on
/dev/sda2 6553600 512000 6041600 8% /
If IUse% reaches 100%, your system cannot create any new files or directories, even if terrabytes of raw disk space remain open.
Comprehensive Hands-on Practice & Examples (df)
Example 1: Human-Readable Storage Audit (df -h)
To check raw disk space across your system using clean, human-readable Gigabyte and Megabyte units:
df -h
Expected Output:
Filesystem Size Used Avail Use% Mounted on
/dev/sda2 98G 41G 53G 44% /
tmpfs 3.9G 100K 3.9G 1% /run
/dev/sdb1 489G 363G 102G 79% /var/www/html
Example 2: Identifying Filesystem Types (df -Th)
When troubleshooting network storage mounts or local disk drivers, combining -T and -h reveals the underlying filesystem architecture:
df -Th
Expected Output:
Filesystem Type Size Used Avail Use% Mounted on
/dev/sda2 ext4 98G 41G 53G 44% /
tmpfs tmpfs 3.9G 100K 3.9G 1% /run
Part 2: Auditing Directory and File-Level Consumption — The du Command
While df tells you the high-level health of entire storage partitions and mount points, it cannot tell you which folders are hoarding your storage. If /dev/sda2 is 90% full, df will not point you to the culprit.
For granular, folder-by-folder analysis, Linux provides the du command (short for disk usage).
du[options][path/file]
Unlike df (which queries the kernel’s mounted filesystem superblocks instantly), du actively crawls and traverses directory trees, recursively calculating the cumulative disk space consumed by every file and subdirectory inside a given path.
Essential Options and Flags for du
Common`du`Options
| Option | Flag Name | Description |
| -h, –human-readable | Human-Readable | Displays sizes in human-readable format (K, M, G). |
| -s, –summarize | Summary Only | Displays only the grand total for the specified directory, suppressing the recursive breakdown of every internal file. |
| -c, –total | Grand Total | Appends a cumulative grand total summary row at the very bottom of the output. |
| –max-depth=N | Depth Limiter | Limits directory recursion depth to N levels (invaluable for keeping output readable). |
| -a, –all | Include Files | Displays space usage for every individual file, not just directories. |
Comprehensive Hands-on Practice & Examples (du)
Example 1: Summarizing a Specific Directory (du -sh)
If you want to know the exact storage footprint consumed by your current project folder or home directory without printing every internal file:
du -sh /home/alex
Expected Output:
4.2G /home/alex
Example 2: Auditing Top-Level Subdirectories (du -h –max-depth=1)
When hunting for where storage space is being consumed inside a bloated directory (like /var or /home), use –max-depth=1 to inspect only the immediate subfolders:
sudo du -h –max-depth=1 /var
Expected Output:
45M /var/log
1.2G /var/lib
12K /var/mail
240K /var/cache
1.3G /var
(This instantly identifies /var/lib as the primary storage consumer).
Example 3: Finding the Largest Files and Folders (Combining du and sort)
System administrators frequently combine du with the text sorting utilities you mastered in Chapter 2 (sort) to isolate space hogs instantly.
To list the top-level directories in /var/www/html sorted from largest to smallest:
sudo du -h –max-depth=1 /var/www/html | sort -hr
Decoding the Pipeline:
- du -h –max-depth=1: Calculates human-readable sizes of immediate subfolders.
- sort -hr: Sorts the output in human-readable numeric reverse order (-h understands K, M, G; -r puts the largest values at the top).
Part 3: The Classic Admin Gotcha — df vs. du Discrepancies
One of the most famous troubleshooting puzzles in Linux administration occurs when you run df -h and see that your disk is 100% full, but when you run du -sh /* to audit your directories, the numbers don’t add up—none of the folders appear large enough to fill the drive.
Why Does This Happen? (Open Deleted Files)
This discrepancy is almost always caused by deleted files still held open by running processes.
- A background application (such as a logging daemon or database engine) opens a file and begins writing massive log data to it.
- An administrator (or automated cleanup script) deletes the file from disk using rm to free up space.
- However, because the running process still has an active file descriptor open to that file, the Linux kernel keeps the file’s data blocks allocated in storage so the process can continue reading/writing to it.
- The Result: The filename is gone from the directory tree (so du cannot see it or calculate its size), but the raw storage blocks remain occupied on disk (so df reports the filesystem as 100% full).
How to Diagnose and Fix Open Deleted Files
You can identify hidden open deleted files across your system by combining lsof (list open files) with grep:
sudo lsof +L1
(Or inspecting deleted files marked as REG with (deleted) states).
To force the kernel to release those storage blocks and reclaim your disk space, you simply need to restart or send a graceful reload signal (SIGHUP) to the process holding the file open, allowing it to close its file descriptors.
Summary Checklist for df and du
- [ ] Use df (disk free) to audit storage capacity, utilization percentages, and mount points across system filesystems.
- [ ] Use df -h for human-readable sizing and df -Th to verify filesystem types (ext4, xfs).
- [ ] Watch out for inode exhaustion (df -ih), which blocks file creation even when raw disk space remains available.
- [ ] Use du (disk usage) to recursively crawl directory trees and measure storage consumption.
- [ ] Use du -sh for summaries and du -h –max-depth=1 to isolate bloated subdirectories.
- [ ] Combine du with sort -hr to rank directories by size.
- [ ] Troubleshoot df vs. du storage discrepancies caused by open deleted files held by running processes.
Congratulations! You have successfully completed Chapter 5. You have transformed from navigating static files into actively observing, diagnosing, and controlling the dynamic lifeblood of a Linux operating system.
Let’s review the core concepts and administrative utilities you’ve mastered throughout this chapter:
- Process Snapshots: Capturing instantaneous system states, process IDs (PIDs), and kernel status codes using ps (ps aux, ps -ef).
- Interactive Monitoring: Real-time resource tracking, sorting by CPU/memory, and process tree navigation using top and htop.
- System Health & Kernel Auditing: Evaluating operational uptime, load average queues, and core architecture specifications using uptime and uname.
- Process Control & Signals: Terminating and signaling misbehaving tasks safely (SIGTERM, SIGKILL, SIGHUP) using kill, pkill, and killall.
- Job Control: Managing concurrent terminal tasks using background execution (&), task suspension (Ctrl + Z), the job table (jobs), and switching streams (bg and fg).
- Memory Management: Auditing physical RAM, swap space, and kernel caching behavior (focusing on the vital available metric) using free.
- Disk & Storage Auditing: Tracking block capacity, inodes, and file-level consumption across mounted filesystems and directory trees using df and du.
You now possess a complete operational toolkit to monitor performance bottlenecks, manage active processes, and maintain absolute control over system resources.
Chapter 6: Networking and Remote Access
Section 6.1: Network Diagnostics and Connectivity Testing — The ping Command
Throughout Chapters 1 through 5, you have mastered the complete standalone lifecycle of a Linux machine. You can navigate complex directory hierarchies, manipulate files, stream and filter text, enforce strict user security and file permissions (chmod, chown, umask), monitor processes and memory (ps, top, htop, free), audit disk storage (df, du), and maintain absolute control over system execution and tasks.
However, a modern Linux server or workstation does not exist in a vacuum. It must communicate with the outside world—resolving domain names, fetching software updates, connecting to remote databases, serving web traffic to global users, and collaborating across local area networks (LANs) and wide area networks (WANs).
When a network connection fails, when a remote database becomes unreachable, or when a web service drops offline, you need an immediate diagnostic tool to answer a foundational question: Can our system physically reach that destination across the network?
In this section, we begin our exploration of networking and remote access by examining the most fundamental and universally deployed diagnostic utility in network engineering: ping.
Understanding Network Connectivity and ICMP
Before executing commands, it is vital to understand the underlying networking protocol that powers ping: the Internet Control Message Protocol (ICMP).
Unlike TCP (Transmission Control Protocol) or UDP (User Datagram Protocol)—which transport application data like web pages, email messages, and streaming video—ICMP is an auxiliary management and error-reporting protocol built directly into the Internet Protocol (IP) suite. ICMP messages are used by network devices (routers, switches, and hosts) to send operational feedback and diagnostic information about network communication issues.
The ping utility specifically utilizes two core ICMP message types:
- ICMP Echo Request (Type 8): A packet sent from your local machine to a target IP address or hostname, asking, “Are you there? Can you hear me?”
- ICMP Echo Reply (Type 0): A response packet sent back from the target host acknowledging receipt of the request.
What is ping?
The ping command is a network administration utility used to test the reachability of a host on an Internet Protocol (IP) network and measure the round-trip time (RTT) for packets transmitted from the local host to a destination node.
ping[options]destination
When executed, ping continuously transmits ICMP Echo Request packets to the target destination and listens for incoming ICMP Echo Replies, printing a live, real-time statistical log directly to your terminal until you manually interrupt it by pressing Ctrl + C.
Dissecting the ping Output Stream
Let’s examine a typical output generated by running standard ping against a destination (such as google.com or an IP address like 8.8.8.8):
PING google.com (142.250.190.46) 56(84) bytes of data.
64 bytes from ord38s31-in-f14.1e100.net (142.250.190.46): icmp_seq=1 ttl=115 time=14.2 ms
64 bytes from ord38s31-in-f14.1e100.net (142.250.190.46): icmp_seq=2 ttl=115 time=13.8 ms
64 bytes from ord38s31-in-f14.1e100.net (142.250.190.46): icmp_seq=3 ttl=115 time=15.1 ms
64 bytes from ord38s31-in-f14.1e100.net (142.250.190.46): icmp_seq=4 ttl=115 time=13.5 ms
— google.com ping statistics —
4 packets transmitted, 4 received, 0% packet loss, time 3004ms
rtt min/avg/max/mdev = 13.501/14.150/15.120/0.601 ms
Reading this output from top to bottom, each segment provides vital diagnostic clues:
- Header Line: Confirms the target domain, resolves its target IP address (142.250.190.46), and displays the packet payload size (typically 56 raw payload bytes plus 8 bytes of ICMP header = 64 bytes total).
- Response Lines: Each individual line represents a successful round-trip interaction:
- 64 bytes from …: Confirms data size and source hostname/IP.
- icmp_seq=N: The sequential packet number (starting at 1). Useful for identifying whether packets are arriving out of order or dropping intermittently.
- ttl=115: Time to Live. A decrementing hop counter designed to prevent packets from circulating in endless routing loops. Each router a packet traverses decreases the TTL by 1. If TTL hits 0, the packet is dropped.
- time=14.2 ms: Round-Trip Time (RTT). The total elapsed time in milliseconds for the packet to travel to the destination and back. Lower is faster; high RTT indicates latency bottlenecks or long geographical routing.
- 64 bytes from …: Confirms data size and source hostname/IP.
- Statistics Block: Summarizes overall connection health when you press Ctrl + C:
- Packet Loss (0%): The percentage of sent packets that failed to return. 0% loss indicates a pristine connection; high loss indicates network congestion, faulty cables, or failing hardware.
- RTT Metrics (min/avg/max/mdev): Minimum, average, maximum, and mean deviation round-trip times across all transmitted packets.
- Packet Loss (0%): The percentage of sent packets that failed to return. 0% loss indicates a pristine connection; high loss indicates network congestion, faulty cables, or failing hardware.
Essential Options and Flags for ping
Common`ping`Options
| Option | Flag Name | Description |
| -c COUNT, –count=COUNT | Packet Count | Stops ping automatically after sending the specified number of packets (preventing infinite loops). |
| -i SECONDS, –interval=SECONDS | Interval Timing | Waits the specified number of seconds between sending each packet (default is 1 second). |
| -s BYTES, –size=BYTES | Packet Payload Size | Specifies the number of data bytes to send in each packet (useful for testing MTU limits). |
| -t TTL, –ttl=TTL | Time to Live | Sets the IP Time-to-Live field explicitly for outgoing packets. |
| -q, –quiet | Quiet Output | Suppresses all intermediate packet lines, displaying only the startup header and final statistics summary upon completion. |
| -v, –verbose | Verbose Output | Prints detailed diagnostic information regarding ICMP packet headers and responses. |
| -W SECONDS, –timeout=SECONDS | Response Timeout | Sets the maximum time to wait for a reply before marking a packet as lost. |
Comprehensive Hands-on Practice & Examples
Let’s walk through several practical scenarios to see how ping operates across everyday system administration and networking workflows.
Example 1: Performing a Controlled, Finite Connectivity Test (-c)
By default, running ping will run infinitely until you press Ctrl + C. In automated scripts or quick diagnostic checks, you almost always want to limit the packet count using the -c flag:
ping -c 4 8.8.8.8
This command sends exactly 4 ICMP Echo Requests to Google’s public DNS server (8.8.8.8), prints the statistics, and exits automatically back to your prompt.
Example 2: Testing Local Network Gateway Connectivity
When troubleshooting why your server cannot reach the internet, your first diagnostic step should always be testing communication with your local network gateway (your router or switch):
ping -c 3 192.168.1.1
If this fails with 100% packet loss, your local physical wiring, switch, or network interface card (NIC) is disconnected or misconfigured.
Example 3: Verifying the Local Loopback Interface (127.0.0.1)
Before troubleshooting external networks, you can verify that your operating system’s internal TCP/IP networking stack is functioning correctly by pinging the localhost loopback address:
ping -c 3 127.0.0.1
Successful replies confirm that your local kernel networking stack is operational, regardless of whether a physical network cable is plugged in.
Example 4: Rapid Stress-Testing with Custom Intervals (-i)
If you are diagnosing intermittent network jitter or packet loss that only appears under heavy request frequency, you can accelerate the packet transmission rate using the interval flag (-i).
(Note: On standard Linux systems, sending intervals under 0.2 seconds generally requires root/sudo privileges to prevent flooding local networks).
sudo ping -i 0.2 -c 20 192.168.1.1
This command transmits 5 packets per second across 4 seconds, giving you a rapid statistical snapshot of network stability.
Example 5: Troubleshooting MTU and Packet Fragmentation (-s)
Sometimes a network connection appears healthy for small web traffic, but large file transfers or SSH sessions freeze unexpectedly. This is often caused by Maximum Transmission Unit (MTU) black holes, where intermediate routers drop oversized packets.
You can test larger packet payloads using the size flag (-s):
ping -c 4 -s 1472 8.8.8.8
(A payload of 1472 bytes plus 28 bytes of IP/ICMP headers equals 1500 bytes—the standard Ethernet MTU limit).
Common Troubleshooting Pitfalls with ping
When running ping, you may occasionally encounter error messages or unexpected behavior. Understanding what they mean saves hours of debugging:
- Destination Host Unreachable: Your local machine’s kernel or routing table does not know how to reach the target network. Check your default gateway and routing configuration (ip route).
- Request timeout for icmp_seq… (100% Packet Loss): The target is either powered off, disconnected, or blocking ICMP traffic via a firewall (such as iptables, ufw, or cloud security groups). Many modern web servers and security-conscious firewalls drop incoming ICMP Echo Requests deliberately as a hardening measure. A failed ping does not always mean the server is offline; it may simply be ignoring pings while running web services perfectly.
Summary Checklist for ping
- [ ] Use ping to test basic IP network reachability and measure round-trip time (RTT) to remote hosts.
- [ ] Understand the role of ICMP Echo Requests and Echo Replies.
- [ ] Decode key ping metrics: sequence numbers (icmp_seq), Time to Live (ttl), and packet loss percentages.
- [ ] Use -c COUNT to limit packet transmission for clean script integration and finite checks.
- [ ] Test network tiers systematically: start with 127.0.0.1 (localhost), move to your local gateway, and finally test external targets (8.8.8.8 or domain names).
- [ ] Remember that firewall configurations frequently block ICMP traffic; a dropped ping does not automatically prove a server is offline.
Section 6.2: Modern Network Interface and Route Management — The ip Command
In the previous section, we explored network diagnostics using ping, learning how to test basic IP reachability, interpret ICMP Echo requests and replies, and evaluate round-trip times (RTT) and packet loss.
However, once you verify that a network connection is failing or functioning correctly, you need the ability to inspect and configure your system’s local networking stack. For decades, Unix and Linux administrators relied on legacy utilities such as ifconfig, route, netstat, and arp. While these tools served early networking well, they were built upon obsolete kernel interfaces that struggled to scale with modern Linux networking features like virtual namespaces, software-defined networking (SDN), traffic shaping, and advanced tunneling.
Today, those legacy tools have been officially deprecated across modern Linux distributions. They have been replaced by a unified, incredibly powerful tool suite known as iproute2, anchored by its central command-line utility: ip.
In this section, we examine how to master the ip command for comprehensive interface configuration and routing table management.
What is the ip Command?
The ip command is the modern, unified Linux utility used to configure, manage, inspect, and troubleshoot network interfaces, IP addresses, routing tables, and tunnel configurations.
ip[options]objectcommand[arguments]
Unlike legacy utilities that required separate commands (ifconfig for interfaces, route for routing, arp for MAC addresses), the ip command uses a modular, object-oriented syntax where you specify the target object you want to manipulate followed by the specific command you want to execute.
Core Objects of the ip Command
The ip utility organizes its functionality around specific networking objects. The most common objects you will work with include:
Core`ip`ObjectsReference
| Object | Abbreviation | Description |
| link | l | Network device physical and logical interfaces (e.g., Ethernet cards, loopback, bridges). |
| address | a | IPv4 and IPv6 addresses assigned to network interfaces. |
| route | r | Kernel routing table entries governing how packets are forwarded across networks. |
| neigh | n | Neighbor table / ARP cache managing MAC address resolution for local network hosts. |
| rule | — | Routing policy database rules for advanced policy-based routing. |
Part 1: Inspecting Network Interfaces and Addresses (ip link & ip address)
Before configuring networks, you must inspect your system’s active interfaces and assigned IP addresses.
1. Inspecting Interface States (ip link show)
To view all physical and virtual network interfaces present on your system along with their link states, MAC addresses, and Maximum Transmission Units (MTUs):
ip link show
Expected Output:
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN mode DEFAULT group default qlen 1000
link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00
2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc fq_codel state UP mode DEFAULT group default qlen 1000
link/ether 52:54:00:12:34:56 brd ff:ff:ff:ff:ff:ff
Decoding the Output:
- 1: lo: The local loopback interface (127.0.0.1).
- 2: eth0: The primary Ethernet network interface card.
- <BROADCAST,MULTICAST,UP,LOWER_UP>: Interface flags. UP means the administrative state is enabled; LOWER_UP means the physical link is connected and receiving carrier signal.
- state UP: Indicates the interface is active and operational.
- link/ether 52:54:00:12:34:56: The physical hardware MAC address of the interface.
2. Inspecting Assigned IP Addresses (ip address show)
While ip link shows hardware interfaces, it does not display IP addresses. To view IP configurations across all interfaces:
ip address show
(You can also use the shorthand alias ip a).
Expected Output:
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN group default qlen 1000
inet 127.0.0.1/8 scope host lo
valid_lft forever preferred_lft forever
inet6 ::1/16 host
2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc fq_codel state UP group default qlen 1000
inet 192.168.1.150/24 brd 192.168.1.255 scope global dynamic eth0
valid_lft 86200sec preferred_lft 86200sec
Key Highlights:
- inet 192.168.1.150/24: The IPv4 address assigned to eth0 using CIDR notation (/24 corresponds to a subnet mask of 255.255.255.0).
- inet6: The IPv6 address associated with the interface.
Part 2: Managing Interface States (ip link set)
System administrators frequently need to bring network interfaces up or down during troubleshooting, hardware replacement, or interface reconfiguration.
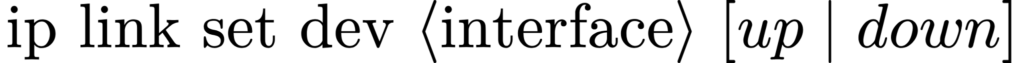
Example 1: Bringing an Interface Down and Up
If a network interface is hanging or needs its configuration reloaded, you can disable it (down) and re-enable it (up):
# Disable the interface
sudo ip link set dev eth0 down
# Re-enable the interface
sudo ip link set dev eth0 up
(⚠️ Warning: If you run sudo ip link set dev eth0 down on a remote cloud server or SSH session over that exact interface, you will instantly sever your connection and lock yourself out until physical or console access is restored).
Example 2: Changing the MTU (Maximum Transmission Unit)
If your network infrastructure requires a custom MTU size (such as 9000 bytes for Jumbo Frames across internal storage networks):
sudo ip link set dev eth0 mtu 9000
Part 3: Assigning and Managing IP Addresses (ip address)
While modern Linux distributions rely on automated DHCP clients (dhcpcd, NetworkManager, systemd-networkd) to assign IP addresses dynamically, servers often require static IP address configurations.
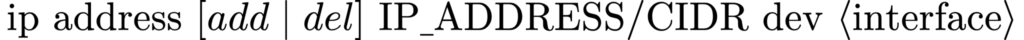
Example 1: Adding a Static IP Address
To assign a static IPv4 address (192.168.1.100 with a 24-bit subnet mask) to interface eth0:
sudo ip address add 192.168.1.100/24 dev eth0
(This takes effect immediately. You can verify it by running ip a).
Example 2: Removing an IP Address
If an incorrect IP address was assigned to an interface and you need to remove it:
sudo ip address del 192.168.1.100/24 dev eth0
Part 4: Routing Table Management (ip route)
When your computer wants to send a packet to a destination outside its local subnet (such as reaching Google over the internet), it cannot deliver the packet directly. It must forward the packet to a gateway router.
The kernel routing table dictates how every outgoing packet is directed across the network.
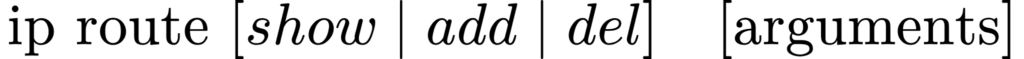
1. Viewing the Routing Table (ip route show)
To inspect your active kernel routing table:
ip route show
(Shorthand: ip r).
Expected Output:
default via 192.168.1.1 dev eth0 proto dhcp metric 100
192.168.1.0/24 dev eth0 proto kernel scope link src 192.168.1.150 metric 100
Decoding the Routes:
- default via 192.168.1.1 dev eth0: The Default Gateway. Any packet destined for an external network address not found on the local subnet is forwarded to the gateway router located at 192.168.1.1 via interface eth0.
- 192.168.1.0/24 dev eth0 …: The Local Subnet Route. Directs traffic destined for devices inside your local 192.168.1.x network straight out of eth0 without involving a router.
2. Adding a Default Gateway (ip route add default)
If your system lacks a default gateway and cannot reach external networks, you can add one manually:
sudo ip route add default via 192.168.1.1 dev eth0
3. Adding a Static Route to a Remote Subnet
Suppose your local server needs to communicate with a private corporate subnet (10.50.0.0/16) located behind a specific internal gateway router (192.168.1.254):
sudo ip route add 10.50.0.0/16 via 192.168.1.254 dev eth0
Now, any traffic bound for 10.50.x.x will be routed explicitly through that gateway.
4. Deleting a Route (ip route del)
To remove an existing route from the kernel table:
sudo ip route del 10.50.0.0/16
Persistence Note: Runtime vs. Permanent Configuration
It is vital to understand that all configuration changes made directly via the ip command (such as adding IP addresses or routes) are runtime changes applied directly to the running kernel.
If you reboot your Linux server, these temporary changes will be wiped clean, and the system will revert to its persistent configuration files managed by your distribution’s network manager (such as Netplan on Ubuntu, NetworkManager, or /etc/sysconfig/network-scripts/ on RHEL/CentOS).
Summary Checklist for the ip Command
- [ ] Use ip as the modern, unified replacement for legacy networking tools like ifconfig and route.
- [ ] Use ip link show to audit physical and logical network interfaces and hardware states.
- [ ] Use ip address show (or ip a) to inspect IPv4 and IPv6 address allocations.
- [ ] Use ip link set dev [interface] [up/down] to control interface administrative states.
- [ ] Use ip address add and ip address del to manage runtime IP assignments.
- [ ] Use ip route show (or ip r) to inspect kernel routing tables and default gateways.
- [ ] Use ip route add and ip route del to manage static routes and gateway forwarding rules.
Section 6.3: Socket Statistics and Active Connections — The ss and netstat Commands
Throughout our journey in Chapter 6, you have mastered network connectivity diagnostics using ping and configured network interfaces and routing tables using the modern ip command suite (ip link, ip address, ip route). You can verify physical reachability, inspect interface hardware states, assign static IPs, and manage gateway routing rules.
However, configuring an IP address and routing packets is only part of network administration. Once packets arrive at your server, which software programs are listening for incoming connections? Which remote client IP addresses are currently connected to your web server, database, or SSH daemon? Are there hung socket states lingering in memory, consuming system resources?
To audit active network sockets, open ports, listening services, and established connections, Linux provides powerful socket-inspection tools. In this section, we examine the legacy standard netstat and its blazing-fast modern replacement, ss.
Understanding Network Sockets
Before diving into commands, let’s define a socket.
In Unix and Linux engineering, a socket is an endpoint of a bidirectional inter-process communication (IPC) flow across a computer network. A network socket is uniquely defined by:
- The Transport Protocol: TCP (reliable, connection-oriented) or UDP (fast, connectionless).
- The Local IP Address and Port Number: (e.g., 192.168.1.150:80 or 0.0.0.0:22).
- The Remote IP Address and Port Number: (e.g., 203.0.113.50:54321 for established connections).
When a server daemon starts (such as an Nginx web server or SSH service), it binds to a network port and enters a listening state, waiting for incoming client connection requests.
Part 1: The Legacy Standard — netstat (Network Statistics)
For decades, the netstat command (part of the legacy net-tools package) was the undisputed king of network socket auditing across Unix and Linux systems.
netstat[options]
Why netstat is Deprecated
While netstat remains deeply embedded in system administrator muscle memory, it has been officially deprecated across modern Linux distributions for many years.
- The Performance Bottleneck: netstat gathers socket information by frantically parsing /proc/net/tcp, /proc/net/udp, and related text files in the virtual filesystem.
- On modern enterprise servers handling tens of thousands of concurrent active connections (such as high-traffic web apps or load balancers), parsing these massive text files becomes extremely slow, CPU-intensive, and resource-heavy.
Part 2: The Modern Standard — ss (Socket Statistics)
To solve the performance limitations of netstat, the Linux kernel introduced Netlink sockets—a high-performance kernel-to-userspace communication channel.
The ss command (short for socket statistics) is the modern utility designed to dump socket statistics directly from the kernel via Netlink.
ss[options]
Why ss is Superior
- Blazing Speed: Because ss queries kernel socket tables directly via Netlink rather than reading bloated text files in /proc, it can instantly retrieve socket statistics on systems with hundreds of thousands of active connections without lagging.
- Rich Filtering: ss supports advanced filtering expressions, allowing you to isolate specific TCP states, ports, or remote IP addresses with surgical precision.
Essential Options and Flags for ss
Common`ss`Options
| Option | Flag Name | Description |
| -t, –tcp | TCP Sockets | Displays only TCP sockets. |
| -u, –udp | UDP Sockets | Displays only UDP sockets. |
| -l, –listening | Listening Sockets | Displays only sockets that are actively listening for incoming connections. |
| -a, –all | All Sockets | Displays both listening and established (non-listening) sockets. |
| -n, –numeric | Numeric Output | Suppresses hostname and service name resolution (displays raw IP addresses and port numbers, speeding up execution). |
| -p, –processes | Show Processes | Displays the PID and program name of the process holding each socket open (requires sudo). |
| -s, –summary | Socket Summary | Prints a concise summary breakdown of total socket usage by protocol type. |
| -e, –extended | Extended Info | Displays detailed socket information, including TCP socket cookie data and UID numbers. |
Dissecting the ss Output Table
Let’s examine a typical output generated by running standard ss:
State Recv-Q Send-Q Local Address:Port Peer Address:Port Process
LISTEN 0 128 0.0.0.0:22 0.0.0.0:* users:((“sshd”,pid=1100,fd=3))
ESTAB 0 0 192.168.1.150:22 192.168.1.50:54321 users:((“sshd”,pid=1420,fd=3))
Reading this table from left to right:
- State: The current TCP socket state (LISTEN, ESTABLISHED, TIME_WAIT, etc.).
- Recv-Q / Send-Q: Receive and send queue byte counts. In a healthy system, these should be 0. Non-zero values indicate network bottlenecks or application lag.
- Local Address:Port: The IP address and port on your local machine bound to the socket. (0.0.0.0 means listening on all available network interfaces).
- Peer Address:Port: The remote client’s IP address and port connected to your machine (* or 0.0.0.0:* for listening sockets).
- Process: The owning application name, PID, and file descriptor (fd), visible when run with -p.
Understanding Core TCP Socket States
When auditing active connections using ss, you will encounter various TCP state codes. Understanding what these states mean is crucial for diagnosing network health:
CoreTCPConnectionStates
| State | Description |
| LISTEN | The server socket is active, waiting and listening for incoming connection requests from clients. |
| SYN-SENT | Your local machine has sent an initial synchronization packet (SYN) and is waiting for a response. |
| SYN-RECV | A connection request has arrived, and the server has acknowledged it while waiting for the final handshake confirmation. |
| ESTABLISHED | A fully active, open connection. Data is actively flowing back and forth between the local and remote hosts. |
| FIN-WAIT / CLOSE-WAIT | The connection is in the process of shutting down gracefully. |
| TIME_WAIT | The connection has closed, but the local socket is waiting briefly to ensure any delayed or retransmitted packets arrive safely before releasing port resources. |
Comprehensive Hands-on Practice & Examples (ss)
Example 1: Listing All Listening Ports with Process Names (ss -tulpn)
One of the most common administrative tasks is auditing what services are running and listening on your server’s network ports:
sudo ss -tulpn
-t: TCP sockets.- -u: UDP sockets.
- -l: Listening sockets only.
- -n: Numeric IP and port numbers (avoids DNS lookup delays).
- -p: Show PIDs and process names.
Expected Output:
Netid State Recv-Q Send-Q Local Address:Port Peer Address:Port Process
udp UNCONN 0 0 0.0.0.0:68 0.0.0.0:* users:((“dhcpcd”,pid=612,fd=6))
tcp LISTEN 0 128 0.0.0.0:22 0.0.0.0:* users:((“sshd”,pid=1100,fd=3))
tcp LISTEN 0 511 0.0.0.0:80 0.0.0.0:* users:((“nginx”,pid=2810,fd=6))
(This output instantly reveals that SSH is listening on port 22 and Nginx is listening on port 80).
Example 2: Viewing All Established TCP Connections (ss -t state established)
If you want to filter out listening and closing sockets and inspect only active, established client connections:
ss -t state established
(The state filter allows you to isolate specific TCP states like established, time-wait, listen, or closed).
Example 3: Filtering Sockets by Specific Port (sport or dport)
If you want to inspect all connections originating from or bound to a specific port (such as checking all incoming SSH connections on port 22):
ss -t ‘( sport = :22 )’
sport: Source port.- dport: Destination port.
Example 4: Displaying Socket Summary Statistics (ss -s)
For a quick, high-level statistical overview of total socket allocations across TCP, UDP, raw, and packet sockets:
ss -s
Expected Output:
Total: 315
TCP: 18 (estab 3, closed 0, orphaned 0, timewait 0), synrecv 0, timewait 0, inuse 4
Transport Total: 22
RAW: 0
UDP: 4
UDPLITE: 0
FRAG: 0
Part 3: Using the Legacy netstat Command
While ss is preferred, you will still encounter netstat in legacy documentation, monitoring scripts, and older enterprise environments.
The legacy equivalent to ss -tulpn using netstat is:
sudo netstat -tulnp
Common`netstat`Flags
| Flag | Description |
| -t | Display TCP connections. |
| -u | Display UDP connections. |
| -l | Display listening server sockets. |
| -n | Display numeric IP addresses instead of resolving hostnames. |
| -p | Display PID and program names holding sockets open. |
| -a | Display all sockets (both listening and established). |
Example: Inspecting Routing Table via Netstat
While ip route is the modern standard, netstat -r was historically used to view the kernel routing table:
netstat -r
Summary Checklist for Socket Statistics
- [ ] Understand that network sockets represent active communication endpoints defined by protocols, IP addresses, and port numbers.
- [ ] Use ss as the modern, high-performance replacement for legacy netstat, leveraging Netlink sockets for instant kernel queries.
- [ ] Master the essential ss flag combination: ss -tulpn to audit all listening TCP and UDP ports alongside their owning process PIDs.
- [ ] Understand core TCP connection states: LISTEN, ESTABLISHED, TIME_WAIT, and CLOSE_WAIT.
- [ ] Use state filters like ss -t state established to isolate active client connections.
- [ ] Use ss -s for a high-level summary of total socket usage across protocols.
Section 6.4: Tracing Packet Paths and Domain Name Resolution — The traceroute and dig Commands
Throughout Chapter 6, you have mastered network diagnostics using ping, configured network interfaces and routing tables using the modern ip utility suite, and audited active connections and listening ports using ss. You can verify physical reachability, assign IP addresses, manage default gateways, and inspect socket states across your system.
However, complex enterprise networks and global internet architectures span vast distances. When a remote server is unreachable, simply knowing that ping packet loss is 100% does not tell you where along the multi-hop journey the breakdown occurred. Is the failure at your local gateway, at an intermediate Internet Service Provider (ISP) router halfway across the country, or at the target data center’s perimeter firewall?
Furthermore, before a packet can be routed anywhere, your system must resolve human-readable domain names (like example.com) into raw numerical IP addresses using the Domain Name System (DNS). If DNS resolution fails, your network is effectively paralyzed, even if physical connectivity is pristine.
To diagnose multi-hop routing bottlenecks and audit deep DNS name resolution records, Linux provides two indispensable administrative utilities: traceroute and dig.
Part 1: Tracing Multi-Hop Packet Paths — The traceroute Command
The traceroute command is a network diagnostic tool used to track the exact physical path (hops) that packets take from your local machine across routers and networks to reach a destination host, measuring the transit delay of each hop along the way.
traceroute[options]destination
How traceroute Works Under the Hood (The Magic of TTL)
Unlike ping, which tests end-to-end reachability in a single stream, traceroute is a masterpiece of protocol engineering that exploits the Time to Live (TTL) field inside IP packet headers.
- The TTL Incrementing Trick:
- When traceroute begins, it sends a packet with a TTL of 1.
- The very first router your packet hits reads the header, decrements the TTL from 1 to 0, realizes the packet has expired, drops it, and sends an ICMP Time-to-Live Exceeded message back to your machine.
- traceroute logs that router’s IP address and measures the round-trip time.
- When traceroute begins, it sends a packet with a TTL of 1.
- Stepping Forward:
- Next, traceroute sends a packet with a TTL of 2. It passes the first router untouched, but expires at the second router, which replies with another expiration notice.
- traceroute repeats this process, incrementing the TTL by 1 each time (TTL = 3, TTL = 4, etc.), systematically mapping every router (hop) along the path until the packet finally reaches the destination host.
- Next, traceroute sends a packet with a TTL of 2. It passes the first router untouched, but expires at the second router, which replies with another expiration notice.
Essential Options and Flags for traceroute
Common`traceroute`Options
| Option | Flag Name | Description |
| -n, –numeric | Numeric Output | Displays IP addresses directly instead of attempting reverse DNS lookups for every router hop (drastically speeds up execution). |
| -m MAX_TTL, –max-hops=MAX_TTL | Max Hops | Sets the maximum number of hops (TTL limit) before stopping (default is 30). |
| -p PORT, –port=PORT | Target Port | Specifies the destination port number for UDP/TCP probes (default is UDP port 33434). |
| -w SECS, –wait=SECS | Wait Timeout | Sets the timeout duration in seconds to wait for a router response (default is 5.0 seconds). |
| -I, –icmp | ICMP Echo Probes | Uses standard ICMP Echo requests instead of UDP packets for tracing (useful if firewalls block UDP probes). |
| -T, –tcp | TCP SYN Probes | Uses TCP SYN packets for tracing (ideal for bypassing corporate firewalls that block ICMP and UDP). |
Dissecting the traceroute Output Table
Let’s examine a typical output generated by running standard traceroute:
traceroute to google.com (142.250.190.46), 30 hops max, 64 byte packets
1 _gateway (192.168.1.1) 1.210 ms 1.105 ms 0.980 ms
2 10.20.30.1 (10.20.30.1) 5.420 ms 5.100 ms 4.890 ms
3 core-router-01.isp.net (192.0.2.14) 12.400 ms 11.900 ms 12.100 ms
4 * * *
5 142.250.190.46 (142.250.190.46) 14.150 ms 13.800 ms 14.020 ms
Reading this output from top to bottom:
- Header Line: Displays the target domain, resolved IP, maximum hop limit (30), and packet payload size.
- Hop Rows: Each numbered line represents a router node the packet traversed:
- Hop 1 (192.168.1.1): Your local network gateway router. Three separate probe timings are listed (1.210 ms, 1.105 ms, 0.980 ms).
- Hop 4 (* * *): A silent router. The asterisks indicate that all three probes timed out without receiving a response. This does not necessarily mean the network is broken; many enterprise routers and firewalls are explicitly configured to ignore traceroute probes to hide their internal topology from security scanning.
- Hop 1 (192.168.1.1): Your local network gateway router. Three separate probe timings are listed (1.210 ms, 1.105 ms, 0.980 ms).
Comprehensive Hands-on Practice & Examples (traceroute)
Example 1: Fast Numeric Tracing (traceroute -n)
To prevent traceroute from wasting time performing reverse DNS lookups on every intermediate ISP router IP address:
traceroute -n 8.8.8.8
Example 2: Bypassing Firewall Restrictions Using ICMP (traceroute -I)
If standard UDP probes hang indefinitely due to strict firewall rules along your route, force traceroute to use ICMP Echo requests (-I):
sudo traceroute -I google.com
Example 3: Tracing via TCP Ports (traceroute -T -p 443)
Many corporate or cloud firewalls block ICMP and UDP entirely while permitting outbound HTTPS traffic on port 443. You can trace packet paths using TCP SYN probes bound to port 443:
sudo traceroute -T -p 443 example.com
Part 2: Domain Name Resolution and DNS Auditing — The dig Command
While traceroute maps the physical journey of packets across routers, network communication always begins with a name lookup. When you type google.com into your browser or terminal, your operating system queries a DNS server to translate that human-readable domain into a machine-readable IP address (142.250.190.46).
When DNS resolution fails, or when you need to inspect DNS record configurations (such as MX mail records, CNAME aliases, or TXT verification keys), you need a professional query tool.
For decades, administrators used nslookup. However, nslookup is widely considered outdated and provides limited debugging capabilities. The modern industry standard for querying DNS name servers is dig (short for Domain Information Groper).
dig[server]domain[type][options]
Essential Options, Flags, and Record Types for dig
Common`dig`RecordTypes
| Record Type | Description |
| A | IPv4 Address record (maps a domain name to a 32-bit IPv4 address). |
| AAAA | IPv6 Address record (maps a domain name to a 128-bit IPv6 address). |
| CNAME | Canonical Name record (creates an alias pointing one domain name to another). |
| MX | Mail Exchange record (specifies mail servers responsible for handling email for the domain). |
| NS | Name Server records (authoritative DNS servers designated for the domain). |
| TXT | Text record (stores arbitrary text data, widely used for SPF, DKIM, and domain ownership verification). |
| SOA | Start of Authority record (stores core administrative details about the DNS zone). |
Common`dig`OptionsandFlags
| Option / Flag | Description |
| +short | Suppresses all verbose header and footer metadata, returning only the raw answer (ideal for shell scripts). |
| +trace | DNS Tracing: Performs an iterative root-server lookup, tracing the entire delegation path from root name servers down to the authoritative server. |
| @server | Queries a specific DNS resolver instead of your system default (e.g., @8.8.8.8 or @1.1.1.1). |
| -x IP_ADDRESS | Performs a Reverse DNS Lookup, mapping an IP address back to its registered domain name. |
Dissecting the dig Output Stream
Let’s examine a typical output generated by running standard dig example.com:
; <<>> DiG 9.18.18-0ubuntu0.22.04.1-Ubuntu <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 45120
;; flags: qr rd ra; QUERY: 1, ANSWER: 1, AUTHORITY: 0, ADDITIONAL: 1
;; QUESTION SECTION:
;example.com. IN A
;; ANSWER SECTION:
example.com. 300 IN A 93.184.216.34
;; QUERY TIME: 24ms
;; SERVER: 127.0.0.53#53(127.0.0.1)
;; WHEN: Sun Nov 08 09:43:00 EST 2026
;; MSG SIZE rcvd: 56
;; AUTHORITY_SECTION:
+————————————————————-+
Reading this output:
- Header Block: Displays the dig version and query status (status: NOERROR confirms a successful lookup with no errors).
- Question Section (;; QUESTION SECTION): Confirms what your system asked for (an A record for example.com).
- Answer Section (;; ANSWER SECTION): The core result. Reveals that example.com resolves to IP 93.184.216.34 with a TTL (Time-to-Live caching duration) of 300 seconds.
- Footer Metadata: Reports query latency (24ms), the local DNS resolver queried (127.0.0.53), and timestamp details.
Comprehensive Hands-on Practice & Examples (dig)
Example 1: Basic DNS Lookup (dig example.com)
To query all default A records associated with a domain:
dig example.com
Example 2: Streamlining Output for Scripts (dig +short)
When writing shell scripts or verifying IP addresses quickly without wading through verbose headers:
dig +short example.com
Expected Output:
93.184.216.34
Example 3: Querying Specific DNS Record Types (MX or TXT)
To inspect mail exchange servers responsible for handling email for a domain:
dig mx google.com
To inspect security and verification TXT records (such as SPF/DKIM policies):
dig txt github.com
Example 4: Querying a Specific External DNS Resolver (@8.8.8.8)
If your local network’s DNS resolver is misbehaving or returning cached stale records, you can bypass it entirely and query Google’s public DNS server (8.8.8.8) directly:
dig @8.8.8.8 example.com
Example 5: Performing a Step-by-Step DNS Trace (dig +trace)
If you want to diagnose why a domain is failing to resolve across global name servers, the +trace flag commands dig to perform an iterative walkthrough starting from the internet root name servers (.):
dig +trace example.com
This output walks you through root servers, TLD (.com) servers, and finally the domain’s authoritative registrar name servers.
Example 6: Performing a Reverse DNS Lookup (dig -x)
If you have an IP address (such as 8.8.8.8) and want to find its registered hostname pointer (PTR record):
dig -x 8.8.8.8
Expected Output:
;; ANSWER SECTION:
8.8.8.8.in-addr.arpa. 86400 IN PTR dns.google.
Summary Checklist for traceroute and dig
- [ ] Use traceroute to map the multi-hop path packets take across intermediate routers to reach a destination.
- [ ] Understand how traceroute utilizes incrementing Time to Live (TTL) packet headers to trigger ICMP expiration notices from routers.
- [ ] Use traceroute -n for fast numeric routing audits, and -I or -T to bypass firewalls blocking default UDP probes.
- [ ] Use dig as the modern industry-standard utility for querying DNS name servers and inspecting record types (A, AAAA, CNAME, MX, TXT).
- [ ] Use dig +short for clean, script-friendly output filtering.
- [ ] Use dig +trace to debug iterative DNS delegation paths from root servers down to authoritative hosts.
- [ ] Use dig @[server] to query specific external DNS resolvers (like 8.8.8.8 or 1.1.1.1), and dig -x for reverse IP lookups.
Section 6.5: Data Transfer and API Interaction — The wget and curl Commands
Throughout Chapter 6, you have mastered network connectivity diagnostics (ping), interface and routing configuration (ip), socket and port auditing (ss), multi-hop packet tracing (traceroute), and Domain Name System (DNS) resolution (dig). You can verify physical reachability, manage gateway routing rules, audit listening services, and troubleshoot domain lookup failures.
However, once a network link is established and DNS is fully operational, how do systems actually exchange data across the internet? How do administrators download software packages, pull configuration files, fetch remote backups, or automate cloud deployments? Furthermore, in modern cloud architectures, servers rarely interact with static web pages alone; they communicate dynamically with web services, microservices, and external REST APIs.
To accomplish these tasks directly from the command line without relying on graphical browsers, Linux provides two exceptionally powerful data transfer utilities: wget (the non-interactive file downloader) and curl (the Swiss Army knife of protocol data transfer and API interaction).
Part 1: Non-Interactive File Downloading — The wget Command
The wget command (short for World Wide Web get) is a non-interactive network downloader designed to retrieve files from the web using HTTP, HTTPS, and FTP protocols.
wget[options]URL
Why wget is Essential for Administration
- Non-Interactive Resilience: Unlike web browsers that require human clicks, wget is designed specifically for scripts, background cron jobs, and unattended server automation. If your network connection drops halfway through downloading a massive 10-gigabyte database backup file, wget can automatically detect the interruption and resume the download exactly where it left off.
- Recursive Mirroring: wget can recursively crawl an entire website or directory tree, downloading all linked files, images, and documents to create a local offline mirror.
Essential Options and Flags for wget
Common`wget`Options
| Option | Flag Name | Description |
| -O FILE, –output-document=FILE | Rename Output | Saves the downloaded file under a custom local filename instead of using the remote URL’s default name. |
| -c, –continue | Resume Download | Resumes a broken or partially completed download (crucial for large files). |
| -r, –recursive | Recursive Download | Recursively downloads an entire website or directory structure. |
| -b, –background | Background Execution | Immediately sends the download process into the background, logging activity to wget-log. |
| -q, –quiet | Quiet Mode | Suppresses all output messages and progress bars (ideal for shell scripts). |
| –limit-rate=RATE | Bandwidth Limiter | Restricts download speed (e.g., –limit-rate=500k or 2m) to prevent saturating network bandwidth. |
Comprehensive Hands-on Practice & Examples (wget)
Example 1: Basic File Download
To download a remote file (such as a software archive or configuration script) and save it locally with its original filename:
wget https://example.com/downloads/package-v1.0.tar.gz
wget connects to the server, displays a real-time progress bar showing transfer speed and estimated completion time, and saves the file in your current working directory.
Example 2: Downloading and Renaming a File (-O)
If a URL points to a dynamic download script with an unhelpful filename (like download.php?id=482), you can save it directly with a proper, descriptive name using the -O flag:
wget -O master_config.yaml https://example.com/download.php?id=482
Example 3: Resuming an Interrupted Large Download (-c)
Suppose you are downloading a 5-gigabyte operating system ISO image, and your SSH session disconnects after 3 gigabytes have downloaded. Instead of restarting from zero, use the continue flag (-c):
wget -c https://releases.ubuntu.com/24.04/ubuntu-24.04-live-server-amd64.iso
wget inspects the partial local file on disk, negotiates with the remote server, and downloads only the remaining 2 gigabytes.
Example 4: Downloading in the Background (-b)
If you are initiating a massive multi-gigabyte transfer that will take hours, and you want to close your terminal without killing the download:
wget -b https://example.com/massive_dataset.zip
The process detaches into the background immediately, and progress is appended to a local wget-log file.
Part 2: The Swiss Army Knife of Data Transfer — The curl Command
While wget excels primarily at downloading files and mirroring websites, curl (client URL) is an infinitely more versatile data transfer utility supporting over two dozen protocols (including HTTP, HTTPS, FTP, SFTP, LDAP, SMB, and SMTP).
curl[options]URL
curl vs. wget: What’s the Difference?
- wget was built specifically to download files to disk. It handles recursive directory mirroring and broken-connection resumption natively.
- curl was built to transfer data to and from servers. By default, curl outputs the retrieved data directly to your terminal screen (stdout) rather than saving it to disk, making it the premier tool for interacting with web applications and REST APIs.
Essential Options and Flags for curl
Common`curl`Options
| Option | Flag Name | Description |
| -o FILE, –output | Save to File | Writes output to a specified local file instead of printing to the terminal screen. |
| -O, –remote-name | Keep Remote Name | Saves the downloaded file using the exact remote filename found in the URL. |
| -I, –head | Headers Only | Fetches only the HTTP response headers, omitting the body (essential for checking web server status). |
| -L, –location | Follow Redirects | Automatically follows HTTP 301/302 redirection headers to the final destination URL. |
| -s, –silent | Silent Mode | Suppresses progress meters and error messages. |
| -u USER:PASS, –user | Basic Authentication | Supplies username and password credentials for protected endpoints. |
Comprehensive Hands-on Practice & Examples (curl)
Example 1: Fetching Web Content to Terminal (stdout)
Running curl without output flags prints the HTML source code or response data directly to your terminal:
curl https://example.com
Example 2: Downloading and Saving a File (-o and -O)
To download a file and save it locally using its original remote filename:
curl -O https://example.com/sample_image.png
To save it under a custom local filename:
curl -o custom_name.png https://example.com/sample_image.png
Example 3: Inspecting HTTP Headers (-I)
When troubleshooting web server configuration, SSL certificates, or caching behavior, you often need to see server response headers without downloading the full webpage body:
curl -I https://google.com
Expected Output:
HTTP/2 200
content-type: text/html; charset=ISO-8859-1
content-security-policy-report-only: …
date: Sun, 08 Nov 2026 10:00:00 GMT
server: gws
(Confirms an HTTP/2 status of 200 OK).
Part 3: Interacting with APIs and Web Services Using curl
In modern cloud environments, microservices communicate via Representational State Transfer (REST) Application Programming Interfaces (APIs). Because curl gives you absolute control over HTTP methods, headers, and request payloads, it is the primary command-line tool used by developers and system administrators to query APIs, test webhooks, and automate cloud infrastructure.
Understanding HTTP Methods in CLI
When interacting with REST APIs, you specify the action using the -X (or –request) flag:
- GET (Default): Retrieves data from a server.
- POST: Sends new data to a server to create a resource.
- PUT: Updates or replaces an existing resource on a server.
- DELETE: Removes a resource from a server.
Essential API Options for curl
APIInteractionFlags
| Option | Flag Name | Description |
| -X METHOD, –request | HTTP Method | Specifies the request method (GET, POST, PUT, DELETE). |
| -H HEADER, –header | Custom Header | Adds custom HTTP headers (e.g., content types or authorization tokens). |
| -d DATA, –data | Request Body Data | Sends data payload in a POST/PUT request. |
Comprehensive Hands-on Practice & Examples (APIs)
Example 1: Performing a Basic API Query (GET)
Suppose you want to query a public REST API that returns weather data or JSON status info:
curl -s https://api.ipify.org?format=json
(Combines silent mode -s with a public IP lookup API).
Example 2: Sending Data to an API (POST with JSON Payload)
When sending structured JSON data to a webhook or API endpoint, you must explicitly declare the Content-Type header as application/json and provide the data payload using -d:
curl -X POST https://api.example.com/v1/devices \
-H “Content-Type: application/json” \
-d ‘{“device_id”: “sensor_01”, “status”: “active”}’
-X POST: Specifies a data creation request.- -H “Content-Type: application/json”: Informs the server that the payload is formatted in JSON.
- -d ‘…’: Passes the JSON dictionary string.
Example 3: Authenticating with Bearer Tokens
Most secure APIs require token-based authentication. You pass authentication credentials securely via HTTP authorization headers using -H:
curl -H “Authorization: Bearer eyJhbGciOiJIUzI1Ni…” \
Summary Checklist for wget and curl
- [ ] Use wget for robust, non-interactive file downloading, supporting recursive website mirroring and connection resumption (-c).
- [ ] Use wget -O to rename downloaded files and wget -b for background transfers.
- [ ] Use curl as the ultimate multi-protocol data transfer tool, outputting to terminal by default or saving files using -o / -O.
- [ ] Use curl -I to inspect HTTP response headers and status codes.
- [ ] Master curl API interactions by combining HTTP methods (-X POST), custom headers (-H), and JSON data payloads (-d).
- [ ] Use authorization headers (Authorization: Bearer [token]) to authenticate secure API requests directly from the command line.
Section 6.6: Secure Remote Administration — The ssh Command
Throughout Chapter 6, you have mastered network connectivity diagnostics (ping), interface and routing configuration (ip), active socket and port auditing (ss), multi-hop packet tracing (traceroute), Domain Name System resolution (dig), and web data transfer and API interactions (wget, curl). You can verify physical reachability, inspect listening services, track routing paths, and pull remote files from the command line.
However, in professional system administration, DevOps engineering, and cloud infrastructure management, you rarely sit physically in front of every server you manage. Instead, servers sit headless in remote data centers or distributed cloud availability zones across the globe.
To manage these systems, you need a secure, encrypted communication channel that allows you to log into remote machines, execute administrative commands, modify configuration files, and manage services as if you were sitting directly at their local console.
In this section, we examine the foundational pillar of secure remote access: the ssh (Secure Shell) command.
The Evolution of Remote Access: From Plaintext to Cryptography
Before the advent of Secure Shell in the mid-1990s, remote administration across Unix and Linux networks relied on legacy protocols such as telnet, rlogin, and rsh.
- The Fatal Flaw: These legacy protocols transmitted all data—including usernames, administrative passwords, and executed commands—in completely clear text across the network.
- Any malicious actor sitting on an intermediate switch, local router, or public Wi-Fi network could easily run a packet sniffer (like Wireshark or tcpdump) and capture plaintext administrator credentials instantly.
ssh was engineered to solve this vulnerability fundamentally. By implementing robust cryptographic algorithms, SSH establishes an encrypted tunnel between your local client machine and the remote server. Even if network traffic is intercepted en route, an attacker sees only unreadable ciphertext.
How ssh Works Under the Hood
When you execute an SSH connection request, the client-server architecture undergoes a rigorous cryptographic handshake divided into three distinct phases:
- Phase 1: Version Exchange and Key Negotiation: The client and server negotiate supported cryptographic ciphers, hashing algorithms, and key exchange methods to ensure both ends agree on secure encryption standards.
- Phase 2: Server Authentication and Host Key Verification: The server proves its identity to your client using a cryptographic host key. When connecting to a server for the first time, SSH warns you that the server’s authenticity cannot be established and displays its unique cryptographic fingerprint:
- Plaintext
The authenticity of host ‘192.168.1.50 (192.168.1.50)’ can’t be established.
ED25519 key fingerprint is SHA256:AbC123XyZ…
Are you sure you want to continue connecting (yes/no/[fingerprint])?
Security Warning: Typing yes saves this key to your local ~/.ssh/known_hosts file. If the server’s host key ever changes unexpectedly in the future, SSH will throw a terrifying Man-in-the-Middle (MitM) warning, refusing to connect because the server’s cryptographic identity no longer matches your local record.
- Phase 3: User Authentication: Once the connection is encrypted and the server is verified, you authenticate your user identity—either by entering a user password or, preferably, by utilizing cryptographic SSH Public Key Authentication.
What is ssh?
The ssh command is a client-side utility used to log into a remote machine executing an SSH daemon (sshd), execute commands on that remote system, and securely tunnel data between systems.
ssh[options][user@]hostname
Essential Options and Flags for ssh
Common`ssh`Options
| Option | Flag Name | Description |
| -p PORT, –port=PORT | Remote Port | Specifies the TCP port number on the remote server (default is port 22). |
| -i FILE, –identity-file=FILE | Private Key File | Specifies a custom private key file to use for public-key authentication (e.g., ~/.ssh/id_rsa). |
| -v, –verbose | Verbose Output | Prints detailed diagnostic debugging steps regarding connection negotiation and handshake protocols. |
| -X / -Y | X11 Forwarding | Enables GUI graphical application forwarding from the remote server back to your local X11 display. |
| -N, –no-remote-cmd | No Command Execution | Tells SSH not to execute a remote command; widely used when setting up background port forwarding tunnels. |
| -L, -R | Port Forwarding | Establishes local or remote port forwarding tunnels for secure network bridging. |
Comprehensive Hands-on Practice & Examples (ssh)
Example 1: Basic Remote Login
To log into a remote server with IP 192.168.1.50 under the remote username alex:
ssh alex@192.168.1.50
(If your local username matches your remote username, you can omit alex@ and simply run ssh 192.168.1.50).
Once authenticated, your terminal prompt changes from your local machine to the remote server, indicating that all commands you type are now executing on the remote host. To disconnect and return to your local machine, type exit or press Ctrl + D.
Example 2: Connecting on a Non-Standard Port (-p)
For security hardening, many system administrators reconfigure their SSH daemons to listen on a non-standard port (such as 2222) instead of default port 22 to evade automated botnet brute-force scans.
To connect to a server using a custom port, use the -p flag:
ssh -p 2222 alex@192.168.1.50
Example 3: Authenticating with Cryptographic Private Keys (-i)
Password authentication is vulnerable to brute-force attacks and credential stuffing. Professional environments enforce SSH Key Pairs (a public key placed on the remote server in ~/.ssh/authorized_keys, and a private key kept strictly secret on your local machine).
To connect using a specific private key identity file:
ssh -i ~/.ssh/id_ed25519_production alex@192.168.1.50
Example 4: Executing a Single Remote Command Without Interactive Login
Sometimes you do not need an interactive shell session; you simply want to run a quick maintenance command on a remote server and bring the output back to your local terminal.
You can append the command directly to the end of your ssh invocation:
ssh alex@192.168.1.50 uptime
SSH logs in, executes uptime on the remote server, prints the result to your local screen, and disconnects immediately.
Example 5: Troubleshooting Connection Issues with Verbose Mode (-v)
If an SSH connection hangs or fails with a cryptic error message, you can diagnose the handshake process by enabling verbose mode (-v, -vv, or -vvv for maximum debugging depth):
ssh -v alex@192.168.1.50
This outputs hundreds of lines of cryptographic negotiation, allowing you to see exactly where the connection stalls.
Essential SSH Security Best Practices
Because SSH is the primary backdoor into your infrastructure, securing your SSH daemon configuration (/etc/ssh/sshd_config) is one of the most critical security tasks an administrator performs:
- Disable Root Password Logins: Never allow the all-powerful root user to log in directly via SSH using a password. Force administrators to log in as standard users and elevate privileges using sudo.
- Enforce SSH Key Pairs & Disable Passwords: Where possible, disable password authentication entirely (PasswordAuthentication no), forcing users to authenticate exclusively via cryptographic keys.
- Change the Default Port: Move SSH off port 22 to drastically reduce automated brute-force bot noise in your system logs.
- Use Fail2ban: Install intrusion-prevention frameworks like Fail2ban to automatically ban IP addresses after repeated failed SSH login attempts.
Summary Checklist for ssh
- [ ] Use ssh to establish secure, encrypted remote login sessions and execute commands across remote infrastructure.
- [ ] Understand the cryptographic handshake, host key verification, and how to manage ~/.ssh/known_hosts fingerprints safely.
- [ ] Use -p PORT to connect to servers configured on non-standard ports.
- [ ] Use -i FILE to authenticate using secure private key files instead of passwords.
- [ ] Execute single remote commands by appending them directly to your ssh connection string.
- [ ] Use -v verbose debugging flags to troubleshoot failed connection handshakes.
- [ ] Harden your SSH daemon configuration (sshd_config) by disabling root logins and enforcing key-based authentication.
Section 6.7: Secure File Transfer and Synchronization — The scp and rsync Commands
Throughout Chapter 6, you have mastered network connectivity diagnostics (ping), interface and routing configuration (ip), active socket and port auditing (ss), multi-hop packet tracing (traceroute), Domain Name System resolution (dig), web data transfer and API interactions (wget, curl), and secure remote login (ssh). You can inspect routing tables, troubleshoot DNS failures, pull remote web resources, and log into headless servers securely.
However, once you are connected to a remote server via SSH, a frequent administrative necessity arises: moving files between systems.
- How do you securely upload a compiled application binary or configuration file to a production server?
- How do you download daily database backups or server logs from a remote cloud instance back to your local workstation?
- How do you synchronize an entire directory tree across multiple servers efficiently, ensuring that only modified files are transferred without wasting network bandwidth?
In this section, we examine the two primary tools for secure file transfer and synchronization in Linux: scp (Secure Copy) and rsync (Remote Sync).
Part 1: Secure File Copying — The scp Command
The scp command (short for secure copy) is a command-line utility used to securely copy files and directories between local and remote hosts, or between two remote hosts, over an encrypted SSH channel.
scp[options]source_pathdestination_path
How scp Works Under the Hood
Under the hood, scp does not implement its own networking protocol. Instead, it relies entirely on SSH for underlying data transfer, authentication, and encryption.
- It authenticates using the exact same mechanisms as the ssh command (passwords or cryptographic private keys).
- All data transmitted across the network is encrypted using SSH ciphers, ensuring complete protection against packet sniffing and interception.
Essential Options and Flags for scp
Common`scp`Options
| Option | Flag Name | Description |
| -r, -R, –recursive | Recursive Copy | Recursively copies entire directories and their contents. |
| -P PORT | Remote Port | Specifies a non-standard SSH port on the remote host (note the capital -P, unlike lowercase -p in other commands). |
| -i FILE | Identity Key File | Specifies a custom private key file for public-key authentication. |
| -p, –preserve | Preserve Attributes | Preserves modification times, access times, and file permission modes from the original source files. |
| -C | Compression | Enables compression of data stream during transfer over slow networks. |
| -q, –quiet | Quiet Mode | Suppresses progress meters and warning diagnostic output. |
Comprehensive Hands-on Practice & Examples (scp)
Example 1: Copying a Local File to a Remote Server
Suppose you have a local configuration file named nginx.conf in your current directory, and you want to upload it to a remote server (192.168.1.50) into the home directory of user alex:
scp nginx.conf alex@192.168.1.50:~
(The tilde ~ represents the remote user’s home directory).
Example 2: Copying a File from a Remote Server to Local Storage
To download a remote database backup file (backup.sql.gz) from a server back to your local current directory (.):
scp alex@192.168.1.50:/var/backups/backup.sql.gz .
Example 3: Recursively Copying Entire Directories (-r)
To copy an entire local project folder (/var/www/my_website) to a remote server’s web directory, you must use the recursive flag (-r):
scp -r /var/www/my_website alex@192.168.1.50:/var/www/
Example 4: Using Non-Standard Ports (-P) and Private Keys (-i)
If your remote server listens on a hardened custom SSH port (such as 2222) and requires an explicit SSH identity private key file, combine -P and -i:
scp -P 2222 -i ~/.ssh/id_ed25519_production local_app.tar.gz alex@192.168.1.50:/opt/apps/
Limitations of scp
While scp is quick and straightforward for simple file transfers, it suffers from significant architectural limitations in enterprise environments:
- No Incremental Transfers: If you use scp to copy a 10-gigabyte file, and the network drops at 9.9 gigabytes, scp cannot resume. You must restart the entire transfer from zero. Furthermore, if you re-copy a directory, scp re-transfers every single file from scratch, even if 99% of the files haven’t changed.
- Poor Progress Feedback: Traditional scp implementations provided minimal progress visualization.
To overcome these limitations for backups, server mirroring, and large data synchronization, system administrators turn to rsync.
Part 2: Fast, Incremental Remote Synchronization — The rsync Command
The rsync command (short for remote sync) is a fast, extraordinarily versatile file copying and synchronization utility.
rsync[options]sourcedestination
The Magic of the Delta-Transfer Algorithm
Unlike scp (which blindly copies complete files every time), rsync utilizes a clever delta-transfer algorithm.
- When syncing files between local and remote systems, rsync analyzes both the source and destination files block by block.
- It transmits only the differences (deltas) across the network. If a 1-gigabyte log file has only had a single line appended to it, rsync sends just that single line rather than re-transferring the entire 1 gigabyte.
Essential Options and Flags for rsync
Common`rsync`Options
| Option | Flag Name | Description |
| -a, –archive | Archive Mode | The master backup flag. Equivalent to -rlptgoD (recursively copies directories, preserves symlinks, permissions, user/group ownership, and modification timestamps). |
| -v, –verbose | Verbose Output | Increases information detail, printing a list of every file transferred. |
| -z, –compress | Data Compression | Compresses file data during transfer over network connections, speeding up transmission. |
| -h, –human-readable | Human-Readable | Displays file sizes in clean, readable units (K, M, G). |
| -P | Progress & Partial | Combines –progress (displays a live progress bar per file) and –partial (keeps partially downloaded files if interrupted, allowing resumption). |
| –delete | Delete Extraneous | Deletes files in the destination directory that no longer exist in the source directory (makes the destination an exact mirror). |
| -e “ssh …” | Remote Shell | Specifies the remote shell command to use (such as passing custom SSH ports or identity keys). |
Comprehensive Hands-on Practice & Examples (rsync)
Example 1: Local Directory Synchronization
To synchronize a local development directory (/home/alex/projects/) to an external backup hard drive mounted at /mnt/backup/:
rsync -avh /home/alex/projects/ /mnt/backup/projects_backup/
(⚠️ Crucial Trailing Slash Note in Rsync: Notice the trailing slash / on the source path /home/alex/projects/. In rsync, adding a trailing slash means “copy the contents inside this directory”. Omitting the trailing slash means “copy the directory itself along with its contents into the destination”).
Example 2: Remote Server Backup via SSH (-avzP)
To create a complete backup of a remote server’s web directory (/var/www/html) down to your local backup server, using archive mode, verbose output, compression, and progress bars:
rsync -avzP alex@192.168.1.50:/var/www/html /local/backup/path/
Expected Output:
receiving incremental file list
html/
html/index.html
1,250 100% 0.00kB/s 0:00:00 (xfr#1, to-chk=5/6)
html/styles.css
15,420 100% 14.69MiB/s 0:00:00 (xfr#2, to-chk=4/6)
sent 145 bytes received 17,210 bytes 3,471.20 bytes/sec
total size is 45,200 speedup is 2.22
Example 3: Mirroring and Deleting Extraneous Files (–delete)
When maintaining exact server mirrors or backup replicas, you want files deleted on the source to be automatically purged from the destination backup as well.
rsync -avz –delete /var/www/html/ alex@192.168.1.50:/var/www/html/
(⚠️ Warning: Use –delete with extreme caution. If your source directory is empty due to a misconfiguration, –delete will wipe out the entire destination directory to match it).
Example 4: Using Custom SSH Ports and Identity Keys with rsync (-e)
Because rsync uses SSH for remote transfers, you can instruct it to use custom ports or private keys by wrapping the command inside the -e flag:
rsync -avz -e “ssh -p 2222 -i ~/.ssh/id_ed25519” /local/data/ alex@192.168.1.50:/remote/data/
Summary Checklist for scp and rsync
- [ ] Use scp for quick, secure file copies between local and remote systems over encrypted SSH channels.
- [ ] Use scp -r for recursive directory copying, and note that scp uses capital -P for custom ports.
- [ ] Understand the limitations of scp: no incremental transfers, no resumable downloads for interrupted streams.
- [ ] Use rsync as the industry-standard utility for fast, bandwidth-efficient file synchronization and backups.
- [ ] Leverage rsync’s delta-transfer algorithm to transmit only modified file blocks rather than full re-transfers.
- [ ] Master the master backup flag combination: rsync -avzP (Archive, Verbose, Compress, Progress/Partial).
- [ ] Use –delete to maintain exact mirror replicas, and -e “ssh -p [port]” to configure custom SSH parameters.
Congratulations! You have successfully completed Chapter 6. You have expanded your Linux mastery from local system administration to connecting infrastructure with the outside world, diagnosing network bottlenecks, and managing remote systems securely.
Let’s review the core concepts and networking utilities you’ve mastered throughout this chapter:
- Connectivity Testing (ping): Verifying IP reachability, evaluating ICMP Echo requests/replies, and measuring round-trip times (RTT) and packet loss.
- Interface & Route Management (ip): Configuring physical and logical network interfaces (ip link), managing IP addresses (ip address), and controlling kernel routing tables and default gateways (ip route).
- Socket Statistics (ss & netstat): Auditing active listening ports, established client connections, process PIDs, and core TCP states (LISTEN, ESTABLISHED, TIME_WAIT).
- Packet Tracing & DNS (traceroute & dig): Mapping multi-hop packet paths across intermediate routers using Time to Live (TTL) metrics, and querying domain name servers across record types (A, MX, TXT).
- Data Transfer & APIs (wget & curl): Non-interactive file downloading with resumable streams (wget), and advanced web data transfer, HTTP header inspection, and REST API interaction (curl).
- Secure Remote Administration (ssh): Establishing encrypted remote terminal sessions, handling cryptographic host key verification, and utilizing public-key authentication.
- File Transfer & Synchronization (scp & rsync): Moving files securely across remote hosts (scp) and performing efficient, bandwidth-optimized incremental backups using the delta-transfer algorithm (rsync).
You now possess a complete professional toolkit to diagnose network failures, secure remote infrastructure, and manage distributed systems.
Chapter 7: Package Management and Software
Section 7.1: The Debian/Ubuntu Ecosystem — dpkg and apt
Throughout Chapters 1 through 6, you have mastered the complete operational lifecycle of a Linux system. You can navigate directory trees, manipulate files, stream and filter text, enforce strict user security and permissions, monitor processes and system resources, audit disk storage, and manage network connectivity, secure remote logins, file transfers, and synchronization.
However, mastering the command line is only half the battle. Sooner or later, you need to expand your system’s capabilities by installing new software, upgrading existing applications, patching security vulnerabilities, and removing obsolete programs.
In the early days of Unix, installing software meant downloading raw source code written in C or C++, configuring makefiles, compiling binaries from scratch, and manually resolving complex dependency chains where one missing library could cause a build to fail.
Modern Linux distributions solved this administrative bottleneck through Package Management Systems. In this section, we begin Chapter 7 by examining the premier package management ecosystem for Debian, Ubuntu, Linux Mint, and their derivatives—mastering both the low-level utility dpkg and the high-level package management suite apt.
Understanding the Package Management Ecosystem
Before executing commands, it is vital to understand how software distribution is organized in Debian-based systems. Software is packaged into compressed archive files ending with the .deb extension. A .deb package contains:
- The pre-compiled binary executables and libraries.
- Configuration files and man pages.
- Metadata, including package name, version number, architecture compatibility (e.g., amd64, arm64), and dependencies (other packages or libraries required for this software to function).
Linux package management is divided into two distinct layers:
- Low-Level Management (dpkg): Directly installs, removes, and inspects individual .deb files stored locally on your hard drive. It does not automatically resolve or download missing dependencies from the internet.
- High-Level Management (apt): Operates as a sophisticated wrapper around dpkg. It connects to remote software repositories across the internet, automatically calculates dependency trees, downloads required packages, and handles system-wide upgrades.
Part 1: Low-Level Package Management — The dpkg Command
The dpkg command (short for Debian Package Manager) is the foundational tool at the core of all Debian-based packaging systems.
dpkg[options]package_file.deb
While everyday software management is handled by high-level tools like apt, dpkg is indispensable when you download a standalone .deb package directly from a vendor (such as Google Chrome, Visual Studio Code, or Discord) and need to install it manually.
Essential Options and Flags for dpkg
Common`dpkg`Options
| Option | Flag Name | Description |
| -i, –install | Install Package | Installs a .deb package file from the local filesystem. |
| -r, –remove | Remove Package | Removes an installed package, but leaves configuration files intact. |
| -P, –purge | Purge Package | Completely removes a package along with all its associated configuration files. |
| -l, –list | List Installed | Lists all packages currently installed on the system matching a name pattern. |
| -L, –listfiles | List Package Files | Lists every file installed on the system by a specific package. |
| -s, –status | Package Status | Displays detailed status, version, and dependency information for an installed package. |
| -S, –search | Search Filename | Finds which installed package owns a specific file path on disk. |
Comprehensive Hands-on Practice & Examples (dpkg)
Example 1: Installing a Local .deb File (dpkg -i)
Suppose you downloaded the .deb installer for a software package named example-tool_1.0_amd64.deb into your ~/Downloads folder. To install it:
sudo dpkg -i ~/Downloads/example-tool_1.0_amd64.deb
⚠️ The Dependency Pitfall: If example-tool requires shared libraries that are not currently present on your system, dpkg will halt installation, throw an error regarding missing dependencies, and leave the package in an unconfigured state.- To fix broken dependencies left behind by dpkg, you immediately follow up with the high-level repair command: sudo apt –fix-broken install.
Example 2: Inspecting Installed Package Status (dpkg -s)
To verify whether a specific package (such as nginx) is installed and check its exact build version and architectural details:
dpkg -s nginx
Expected Output:
Package: nginx
Status: install ok installed
Priority: optional
Version: 1.18.0-6ubuntu14.3
Architecture: amd64
Description: high-performance web and reverse proxy server
Example 3: Listing All Files Installed by a Package (dpkg -L)
If you need to know where a package placed its binaries, configuration templates, or log directories on your filesystem:
dpkg -L nginx
Expected Output:
/.
/etc
/etc/nginx
/etc/nginx/nginx.conf
/usr
/usr/sbin
/usr/sbin/nginx
/usr/share/man/man8/nginx.8.gz
Example 4: Finding Which Package Owns a File (dpkg -S)
Conversely, if you stumble upon an unknown configuration file or binary (e.g., /etc/network/interfaces) and want to know which package installed it:
dpkg -S /etc/network/interfaces
Expected Output:
ifupdown: /etc/network/interfaces
Part 2: High-Level Package Management — The apt Suite
While dpkg manages individual local files, system administrators rely primarily on apt (Advanced Package Tool).
The apt toolset manages software by connecting to remote repositories—massive online servers hosted by Debian, Ubuntu, or third-party maintainers that house thousands of indexed packages. When you request software via apt, it automatically queries remote repositories, calculates every required dependency across multiple packages, downloads them in correct chronological order, and configures them seamlessly.
Part 3: Updating and Upgrading Packages (apt update & apt upgrade)
Before installing or upgrading software on your Linux system, your local machine must know what software versions are currently available across remote repositories.
1. Refreshing Local Package Lists: apt update
The apt update command does not upgrade any software on your computer. Instead, it contacts every repository configured in your system’s source lists (located in /etc/apt/sources.list and /etc/apt/sources.list.d/), downloads the latest package index catalogs, and refreshes your local database.
sudoaptupdate
sudo apt update
Expected Output:
Hit:1 http://archive.ubuntu.com/ubuntu jammy InRelease
Get:2 http://archive.ubuntu.com/ubuntu jammy-updates InRelease [119 kB]
Get:3 http://archive.ubuntu.com/ubuntu jammy-security [110 kB]
Fetched 229 kB in 1s (205 kB/s)
Reading package lists… Done
Building dependency tree… Done
Reading state information… Done
Calculated 42 packages can be upgraded. Run ‘apt list –upgradable’ to see them.
Best Practice: Always run sudo apt update before installing new software or performing system upgrades to ensure your package indexes are current.
2. Upgrading Installed Software: apt upgrade
Once your package lists are refreshed, the apt upgrade command compares the version numbers of all currently installed packages against the newly downloaded repository catalogs and upgrades every outdated package to its latest stable release.
sudoaptupgrade[options]
sudo apt upgrade
When executed, apt calculates dependencies, presents a summary of packages to be upgraded, and prompts for confirmation (Y/n).
Essential Flags for apt upgrade:
- -y, –yes: Automatically answers yes to all installation confirmation prompts (vital for automated scripts and cloud server provisioning).
- –only-upgrade: Upgrades only currently installed packages without installing new ones.
Part 4: Installing and Removing Packages (apt install & apt remove)
Once your repositories are synchronized and updated, you can manage software installations and removals effortlessly.
1. Installing Software: apt install
The apt install command downloads and installs a specified software package along with all its required dependencies.
sudoaptinstall[options]package_name(s)
Example: Installing an Application Stack
Suppose you need to install the Apache web server and the Git version control system on your server:
sudo apt install apache2 git
Automatic Dependency Resolution: apt analyzes both packages, determines if additional shared libraries are needed, displays a summary of disk space consumption, and installs everything in the correct order.
2. Removing Software: apt remove vs. apt purge
When you no longer need an application, Linux gives you two distinct ways to remove it:
- apt remove: Uninstalls the application binaries and executable files, but intentionally preserves configuration files in /etc/ in case you decide to reinstall the package later.
- sudoaptremovepackage_name
- Bash
sudo apt remove apache2
apt purge: Completely strips the application from your system, deleting all associated configuration files, logs, and state data. Use purge when you want to wipe an application completely without leaving residual settings behind.- sudoaptpurgepackage_name
- Bash
sudo apt purge apache2
3. Cleaning Up Orphaned Dependencies: apt autoremove
When you install packages via apt, it often pulls in dozens of auxiliary dependency libraries. When you later remove those parent applications, those auxiliary libraries often remain orphaned on your disk, consuming space.
To safely prune all unneeded orphaned dependencies across your system:
sudo apt autoremove
Summary Checklist for Package Management
- [ ] Use dpkg -i to install standalone local .deb package files, and pair it with sudo apt –fix-broken install if missing dependencies occur.
- [ ] Use dpkg -s to inspect package installation status and dpkg -L to list files installed by a package.
- [ ] Always run sudo apt update first to refresh local package index lists from remote repositories.
- [ ] Use sudo apt upgrade to safely update all installed system packages to their latest stable releases.
- [ ] Use sudo apt install [package] to install new software with automatic dependency resolution.
- [ ] Use sudo apt remove to uninstall software while keeping configs, or sudo apt purge to wipe software and configs entirely.
- [ ] Use sudo apt autoremove to clean up orphaned dependency libraries and reclaim disk space.
Section 7.2: The Red Hat / Fedora Ecosystem — rpm, yum, and dnf
In the previous section, we explored the Debian and Ubuntu package management ecosystem, mastering low-level .deb handling via dpkg and high-level repository management through apt.
However, the Linux enterprise landscape is diverse. A massive share of enterprise servers, cloud infrastructure, and enterprise-grade distributions—including Red Hat Enterprise Linux (RHEL), Fedora, AlmaLinux, Rocky Linux, and older systems like CentOS—operates under an entirely different packaging architecture: the Red Hat ecosystem.
In this section, we examine the tools that power Red Hat-based distributions, exploring the low-level rpm command, the legacy high-level manager yum, and the blazing-fast modern standard, dnf.
Understanding the Red Hat Package Ecosystem
Just as Debian utilizes .deb archives, the Red Hat ecosystem packages software into compressed archive files ending with the .rpm (Red Hat Package Manager) extension.
An RPM package contains pre-compiled binaries, configuration files, man pages, and strict metadata defining dependencies and architecture compatibility (such as x86_64, aarch64, or ppc64le).
Package management in this ecosystem is similarly stratified into two layers:
- Low-Level Management (rpm): Directly queries, installs, verifies, and removes individual .rpm files stored locally on disk. Like dpkg, rpm does not resolve or download missing dependencies automatically from the internet.
- High-Level Management (dnf / yum): Connects to remote software repositories, automatically calculates complex dependency trees, downloads required packages, and handles system-wide security updates and upgrades.
Part 1: Low-Level Package Management — The rpm Command
The rpm command is the foundational low-level utility responsible for manipulating individual RPM packages directly on the filesystem.
rpm[options]package_file.rpm
When to Use rpm
In day-to-day administration, you will rarely use rpm to install software because it lacks dependency resolution. However, rpm is invaluable for:
- Inspecting installed package metadata.
- Auditing files installed by a specific package.
- Querying which package owns a specific file path on disk.
- Installing a standalone vendor .rpm package when required.
Essential Options and Flags for rpm
Common`rpm`Options
| Option | Flag Name | Description |
| -i, –install | Install Package | Installs a new RPM package onto the system. |
| -v, –verbose | Verbose Output | Provides detailed diagnostic output during operations. |
| -h, –hash | Hash Progress Bar | Prints hash marks (###) as a visual progress bar during installation. |
| -U, –upgrade | Upgrade Package | Upgrades an existing package or installs it if not already present. |
| -e, –erase | Remove Package | Uninstalls/erases an installed package by its package name. |
| -q, –query | Query Package | Queries package databases to inspect installed software. |
| -qa | Query All | Lists every single RPM package currently installed on the system. |
| -ql | Query List Files | Lists all individual files installed by a specific package. |
| -qf | Query File Owner | Finds which installed package owns a specific file path on disk. |
Comprehensive Hands-on Practice & Examples (rpm)
Example 1: Installing a Local Package with Verbose Progress (rpm -ivh)
The most famous invocation in Red Hat administration is rpm -ivh (Install, Verbose, Hash):
sudo rpm -ivh example-software-2.0-1.x86_64.rpm
Expected Output:
Verifying… ################################# [100%]
Preparing… ################################# [100%]
Updating / installing…
1: example-software-2.0-1 ################################# [100%]
⚠️ The Dependency Trap: If example-software requires shared libraries that are missing from your system, rpm will abort the installation and output a list of missing dependency requirements. It will not fetch them from the internet for you.
Example 2: Querying an Installed Package (rpm -qi)
To inspect detailed metadata, build dates, maintainers, and descriptions of an installed package (e.g., nginx):
rpm -qi nginx
Expected Output:
Name : nginx
Version : 1.20.1
Release : 14.el9
Architecture: x86_64
Install Date: Sun Nov 8 10:00:00 2026
Group : Unspecified
Size : 1624500
License : BSD
Description : High-performance web server and reverse proxy server
Example 3: Finding Which Package Owns a File (rpm -qf)
If you encounter a binary or configuration file on your system (such as /etc/ssh/sshd_config) and want to know which RPM package installed it:
rpm -qf /etc/ssh/sshd_config
Expected Output:
openssh-server-8.7p1-34.el9.x86_64
Part 2: The Legacy High-Level Standard — The yum Command
For over a decade, yum (Yellowdog Updater, Modified) was the default high-level package management tool for Red Hat, CentOS, and Fedora. It introduced automated dependency resolution, repository management, and transactional safety.
While modern Red Hat and Fedora distributions have officially replaced yum with dnf, you will still encounter yum in legacy documentation, older enterprise servers running RHEL 7, and automated shell scripts.
(On modern systems like Fedora, Rocky Linux 9, and RHEL 9, running yum automatically invokes a compatibility wrapper that redirects commands transparently to dnf).
Part 3: The Modern High-Level Standard — The dnf Command
Introduced in Fedora 22 and adopted as the default package manager in RHEL 8 and newer, dnf (Dandified YUM) is the modern, high-performance package management suite for Red Hat ecosystems.
dnf[options]command[arguments]
Why dnf is Superior to yum
- Blazing-Fast Dependency Solver: dnf replaces Yum’s legacy Python dependency solver with libsolv, a powerful external library written in C that calculates complex dependency trees instantaneously.
- Native Python 3 Support: Built entirely for Python 3, making it cleaner, faster, and more modular.
- API Extensibility: Supports a robust plugin architecture, allowing developers to extend its functionality seamlessly.
Essential Options and Flags for dnf
Common`dnf`CommandsandOptions
| Command / Flag | Description |
| dnf install <package> | Downloads and installs a package along with all required dependencies. |
| dnf update or dnf upgrade | Upgrades all installed packages to their latest available repository versions. |
| dnf remove <package> | Uninstalls a package and removes its associated dependencies if no longer needed. |
| dnf search <keyword> | Searches remote repositories for packages matching a keyword. |
| dnf info <package> | Displays comprehensive metadata, repository origin, and descriptions. |
| dnf clean all | Clears local repository metadata caches, downloaded headers, and temporary files. |
| -y, –assumeyes | Automatically answers yes to all installation prompts (essential for automation). |
Comprehensive Hands-on Practice & Examples (dnf)
Example 1: Searching for Packages (dnf search)
If you know what software you need (e.g., a PostgreSQL database client) but don’t know the exact package name in the repository:
dnf search postgresql
Example 2: Installing Software (dnf install)
To install the Git version control system and the Nginx web server:
sudo dnf install git nginx
dnf automatically calculates dependencies, resolves conflicts, displays a transaction summary table, and prompts for confirmation (y/N).
Example 3: Upgrading System Software (dnf update)
To check for updates across all installed packages and apply security patches and version upgrades:
sudo dnf update
(To automate this in scripts without manual intervention, append -y: sudo dnf update -y).
Example 4: Removing Packages and Orphaned Dependencies (dnf remove)
When you no longer need an application, you can remove it safely:
sudo dnf remove nginx
Unlike legacy yum, dnf automatically tracks and removes orphaned dependencies (auxiliary libraries pulled in during installation that are no longer required by any other application), keeping your system pristine.
Part 4: Managing Software Repositories (dnf repolist)
Software repositories (repos) are remote servers containing indexed collections of RPM packages.
1. Listing Active Repositories
To inspect all enabled software repositories configured on your system:
dnf repolist
Expected Output:
repo id repo name
appstream AlmaLinux 9 – AppStream
baseos AlmaLinux 9 – BaseOS
extras AlmaLinux 9 – Extras
epel Extra Packages for Enterprise Linux 9
(Notice EPEL—Extra Packages for Enterprise Linux. EPEL is an essential repository maintained by the Fedora project that provides thousands of additional open-source packages not included in standard enterprise base builds).
2. Enabling or Disabling Repositories (dnf config-manager)
If you need to enable an optional repository (such as CodeReady Builder or EPEL):
sudo dnf config-manager –enable epel
Part 5: Transactional Safety and Rollbacks (dnf history)
One of the most powerful enterprise features built into dnf is transaction history tracking.
Every time you install, update, or remove software, dnf records that operation as a numbered transaction in an internal SQLite database. If an update breaks your system or introduces a regression, you can roll back the entire transaction.
1. Viewing Transaction History (dnf history)
To list past package management transactions:
dnf history
Expected Output:
ID Command line Date and time Action(s) Altered
3 install nginx 2026-11-08 10:15 Install 1 <
2 update 2026-11-08 09:30 U, I 14
1 install git 2026-11-08 08:00 Install 2
2. Undoing a Transaction (dnf history undo)
If transaction ID 3 (installing Nginx) caused unforeseen issues and you want to reverse it completely:
sudo dnf history undo 3
dnf automatically inspects transaction #3, determines what changes were made, and rolls back the system state precisely.
Summary Checklist for Red Hat Package Management
- [ ] Use rpm -ivh for low-level local package installations and rpm -q for auditing installed metadata.
- [ ] Remember that low-level rpm commands do not resolve dependencies automatically; missing libraries will abort the installation.
- [ ] Use dnf as the modern, high-performance successor to yum, powered by the lightning-fast libsolv dependency solver.
- [ ] Use sudo dnf install and sudo dnf update to manage remote repository software installations and system updates.
- [ ] Leverage EPEL (Extra Packages for Enterprise Linux) to access extended open-source packages.
- [ ] Use dnf history and dnf history undo for transactional safety and system rollbacks.
Section 7.3: Universal Package Managers — snap and flatpak
Throughout Chapter 7, you have explored traditional, distribution-native package management ecosystems: mastering low-level .deb manipulation (dpkg) and high-level repository management (apt) in Debian and Ubuntu, as well as low-level .rpm handling (rpm) and modern transactional management (dnf) in Red Hat and Fedora distributions.
However, traditional packaging models present a persistent challenge for both developers and system administrators: distribution fragmentation.
- If a software developer writes a new application, how do they distribute it? They traditionally have to package it separately for Debian, Ubuntu, Fedora, Arch Linux, openSUSE, and Gentoo, managing different dependency versions, library paths, and packaging formats for each.
- Furthermore, enterprise distributions prioritize extreme stability over bleeding-edge features. As a result, the version of software available in an official distribution repository (like an LTS release) is often years behind upstream development, frustrating users who need modern application features.
To solve these cross-distro friction points and decouple application lifecycles from core operating system libraries, the Linux ecosystem embraced universal, containerized package managers.
In this section, we examine the two dominant universal packaging systems: snap (pioneered by Canonical) and flatpak (driven by the broader open-source community and Red Hat).
The Philosophy of Containerized Applications
Unlike native packages (apt or dnf) that rely on shared system libraries installed across the root filesystem, universal package managers bundle an application together with all its required dependencies, libraries, runtimes, and interpreters into a self-contained, compressed container image.
Key advantages of this architecture include:
- Cross-Distro Compatibility: A single universal package can run unmodified on Ubuntu, Fedora, Arch, Debian, or openSUSE.
- Upstream Freshness: Developers can ship the absolute latest version of their software directly to users without waiting for distribution maintainers to recompile packages.
- Sandboxing and Security: Applications run in isolated environments with restricted access to the host filesystem, hardware, and user data, enhancing overall system security.
Part 1: Canonical’s Universal Ecosystem — The snap Command
The snap command is the primary client utility used to manage Snap packages—universal containerized software packages created by Canonical.
snap[options]command[arguments]
How Snaps Work Under the Hood
- Compressed SquashFS Images: Every snap package is delivered as a single compressed filesystem image (SquashFS). When you install a snap, the system mounts this read-only filesystem dynamically using the kernel’s loop device driver.
- The snapd Daemon: Background management is handled by snapd, a system daemon that monitors, updates, and enforces security policies for all installed snaps.
- Strict Confinement & Sandboxing: Snaps run inside rigorous security boundaries enforced by AppArmor, cgroups, and namespaces. By default, a snap cannot access your personal files outside its designated home directory or interact with other system components unless granted specific “interfaces” (permissions).
Essential Options and Flags for snap
Common`snap`CommandsandOptions
| Command / Flag | Description |
| snap search <keyword> | Searches the online Snap Store for packages matching a keyword. |
| snap install <package> | Downloads and installs a snap package from the Snap Store. |
| snap remove <package> | Completely uninstalls a snap package and its mounted filesystem image. |
| snap list | Lists all snap packages currently installed on your system along with their versions and revisions. |
| snap refresh | Checks for and applies updates to all installed snap packages automatically. |
| snap info <package> | Displays detailed metadata, available channels, confinement levels, and developer info. |
Comprehensive Hands-on Practice & Examples (snap)
Example 1: Searching for Software in the Snap Store (snap search)
To find available packages matching a specific search term (such as a text editor or developer tool):
snap search vlc
Expected Output:
Name Publisher Notes Summary
vlc videolan✓ – The ultimate media player
Example 2: Installing a Snap Package (snap install)
To install a verified package (such as the VLC media player):
sudo snap install vlc
snapd downloads the compressed SquashFS image, mounts it, configures AppArmor security policies, and registers the application launcher automatically.*
Example 3: Installing Classic Confinement Applications (–classic)
By default, snaps run under strict sandboxing confinement. However, certain developer tools (like Visual Studio Code or IDEs) require deep access to your system’s compiler toolchains, shell environments, and unrestricted filesystem paths to function properly.
For these applications, developers use classic confinement, which bypasses the sandbox. You must explicitly authorize classic installation by appending the –classic flag:
sudo snap install –classic code
Example 4: Managing Software Updates (snap refresh)
Snap packages manage their own background update schedules independently of apt or dnf. However, you can force an immediate check for updates across all installed snaps:
sudo snap refresh
Part 2: The Desktop-Centric Universal Standard — The flatpak Command
While snap is widely used across both desktop and server environments (especially within the Ubuntu ecosystem), the broader open-source Linux desktop community (including GNOME, KDE, Fedora Workstation, and Linux Mint) coalesced around Flatpak.
The flatpak command is the utility used to build, install, and run containerized desktop applications.
flatpak[options]command[arguments]
How Flatpak Works Under the Hood
- Flathub as the Central Hub: Unlike Snap (which is centrally hosted by Canonical’s proprietary Snap Store backend), Flatpak is fully decentralized. While Flathub serves as the primary public repository for desktop apps, anyone can host their own Flatpak repository.
- Shared Runtimes: To prevent every application from bloating your disk by bundling massive core libraries (like GTK or Qt) independently, Flatpak introduces Runtimes. A runtime provides a foundational software platform (e.g., org.gnome.Platform or org.kde.Platform), allowing multiple applications to share common libraries efficiently.
- Bubblewrap Sandboxing: Flatpak isolates applications using Bubblewrap (bwrap), leveraging kernel namespaces, seccomp filters, and Wayland/X11 display server isolation to ensure apps cannot snoop on other desktop windows or unauthorized files.
Essential Options and Flags for flatpak
Common`flatpak`CommandsandOptions
| Command / Flag | Description |
| flatpak remote-add … | Adds a new remote software repository (such as Flathub) to your system. |
| flatpak search <keyword> | Searches remote repositories for desktop applications. |
| flatpak install <ref> | Installs a specified application or runtime from a remote repository. |
| flatpak uninstall <app> | Removes an installed Flatpak application. |
| flatpak update | Upgrades all installed Flatpak applications and runtimes. |
| flatpak list | Lists all installed Flatpak applications and runtimes on the system. |
Comprehensive Hands-on Practice & Examples (flatpak)
Example 1: Configuring the Flathub Repository
Before installing Flatpak applications, you must add the Flathub repository to your system if it is not already configured:
flatpak remote-add –if-not-exists flathub https://dl.flathub.org/repo/flathub.flatpakrepo
Example 2: Searching and Installing Applications (flatpak install)
To search for an application (such as GIMP image editor) and install it:
flatpak search gimp
flatpak install flathub org.gimp.GIMP
When installing, Flatpak will prompt you to confirm the installation of the application alongside its required shared runtime environment.
Example 3: Running Flatpak Applications
While desktop environments automatically populate application menus with Flatpak shortcuts, you can also launch a Flatpak application directly from your terminal using its application ID:
flatpak run org.gimp.GIMP
Example 4: Updating Flatpak Software (flatpak update)
To check for and apply updates across all installed Flatpak applications and shared runtimes:
flatpak update
Part 3: Snap vs. Flatpak — Architectural Comparison
When designing a Linux workstation or server deployment, understanding when to use snap versus flatpak is crucial for system administrators.
Snapvs.FlatpakArchitecturalComparison
| Feature | Snap (snap) | Flatpak (flatpak) |
| Primary Domain | Universal (Command-line tools, server daemons, and desktop apps). | Desktop GUI applications exclusively. |
| Repository Model | Centralized (Controlled primarily by Canonical’s Snap Store). | Decentralized (Powered by Flathub and independent custom repositories). |
| Sandboxing Tech | AppArmor, cgroups, namespaces. | Bubblewrap (bwrap), seccomp, Wayland/X11 isolation. |
| Dependency Model | Bundles all dependencies within the package or links to core snaps. | Utilizes shared Runtimes (GNOME, KDE) to reduce storage duplication. |
| Server Support | Native, first-class support for headless servers and background daemons. | Not designed for server environments (requires a graphical session runtime). |
Summary Checklist for Universal Package Managers
- [ ] Understand the core philosophy of containerized universal packaging: solving distro fragmentation and shipping upstream software versions.
- [ ] Use snap for cross-distro deployment spanning both CLI tools, server daemons, and desktop software.
- [ ] Master essential snap commands: snap search, snap install, snap list, and snap refresh.
- [ ] Use the –classic flag with snap when installing developer tools that require unconfined system access.
- [ ] Use flatpak as the premier decentralized standard for graphical desktop applications.
- [ ] Configure Flathub repositories and manage desktop apps using flatpak install and flatpak update.
- [ ] Leverage Flatpak Shared Runtimes to maintain storage efficiency across graphical applications.
Section 7.4: The Arch Linux Ecosystem — The pacman Command
Throughout Chapter 7, you have explored traditional and containerized package management ecosystems: mastering low-level .deb manipulation (dpkg) and high-level management (apt) in Debian and Ubuntu, low-level .rpm handling (rpm) and transactional management (dnf) in Red Hat and Fedora, and universal containerized runtimes (snap and flatpak).
However, for advanced users, systems engineers, and developers seeking absolute control, transparency, and cutting-edge software performance, there is another premier Linux ecosystem: Arch Linux.
Arch Linux operates on a fundamentally different philosophy than Debian or Red Hat. It rejects rigid, milestone-based releases in favor of a rolling-release model, meaning your system is continuously updated to the latest upstream software versions without requiring major operating system upgrades every few years.
At the heart of this minimalist, highly flexible ecosystem lies pacman (Package Manager)—one of the fastest, most elegant, and surgically precise package management utilities in the Unix world.
The Philosophy of Arch Linux and pacman
Unlike heavy distributions that pre-install graphical software centers, background daemons, and bloated abstraction layers, Arch Linux installs only a pristine base system. You build your environment from the ground up, choosing your own display managers, kernels, and window managers.
pacman reflects this philosophy:
- Speed and Efficiency: Written in C, pacman is blazing fast, compiling dependency resolution and package synchronization directly into optimized machine code.
- Simplicity in Design: Instead of relying on sprawling configuration trees, pacman is governed by a single, human-readable configuration file located at /etc/pacman.conf and a mirrored repository structure.
- Transparent Control: pacman does not hide what it is doing behind animated progress bars or confusing abstractions; it gives you direct visibility into transactions, file conflicts, and dependency trees.
Understanding Package Formats and Database Sinks
Arch Linux packages are distributed as compressed archive tarballs ending with the .pkg.tar.zst extension (compressed using Zstandard compression for rapid extraction speed).
Internally, pacman maintains a local relational database in /var/lib/pacman/local/ that tracks every installed file, version number, and dependency relationship. Remote package synchronization relies on database sync files (.db) downloaded from official Arch mirrors defined in /etc/pacman.conf.
The Unique Syntax of pacman
Unlike apt or dnf, which use English-like verbs as commands (apt install, dnf update), pacman utilizes a concise, single-character operation flag system combined with target modifiers.
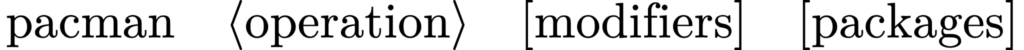
The four primary operations in pacman are:
- -S (Sync): Install, update, and search packages from remote repositories.
- -R (Remove): Uninstall packages from the local system.
- -Q (Query): Inspect, search, and audit locally installed packages.
- -U (Upgrade/Local): Install or upgrade a local package file (.pkg.tar.zst).
Part 1: Synchronizing and Upgrading the System (-S & -Syu)
The most common operational workflow in Arch Linux is managing remote packages and performing system updates.
1. The Arch Full System Upgrade: pacman -Syu
Because Arch Linux is a rolling-release distribution, mixing partial updates (updating only select packages while leaving others behind) can break shared library dependencies and destabilize the kernel.
Therefore, Arch administration revolves around the full system upgrade:
sudopacman-Syu
- What happens under the hood:
- -Sy: Refreshes local package database catalogs by fetching the latest sync files from remote mirrors.
- -Su: Compares all installed packages against the updated databases and upgrades every outdated package on the system simultaneously.
- -Sy: Refreshes local package database catalogs by fetching the latest sync files from remote mirrors.
2. Installing Packages (pacman -S)
To install a new software package or application stack (such as the Git version control system and the Nginx web server):
sudo pacman -S git nginx
pacman connects to the mirrors, calculates dependencies instantly, displays a clean installation summary table, and prompts for confirmation (Y/n).
3. Searching Remote Repositories (pacman -Ss)
If you need to find a package by keyword or description across remote repositories:
pacman -Ss postgresql
Expected Output:
extra/postgresql 16.2-1
Sophisticated object-relational DBMS
extra/postgresql-libs 16.2-1
PostgreSQL libraries
4. Viewing Package Information (pacman -Si)
To inspect detailed metadata, maintainers, download sizes, and dependencies of a remote package before installing it:
pacman -Si nginx
Part 2: Removing Packages (-R, -Rs, and -Rsc)
When software is no longer needed, pacman provides granular control over how packages and their dependencies are erased.
pacman-R[modifiers]package_name
1. Standard Removal (pacman -R)
To uninstall a specific package while leaving its installed dependencies untouched:
sudo pacman -R nginx
2. Removing Packages and Unused Dependencies (pacman -Rs)
When you install an application, it often pulls in auxiliary libraries. If you remove the application using standard -R, those auxiliary libraries remain orphaned on disk.
Using the recursive flag -Rs ensures that any dependencies installed solely for that package—and no longer required by any other software—are wiped out simultaneously:
sudo pacman -Rs nginx
Part 3: Querying the Local Database (-Q)
The query operation (-Q) allows you to inspect, audit, and search software installed locally on your machine without querying remote servers.
pacman-Q[modifiers][package_name]
Essential Query Flags
- pacman -Q: Lists every single package installed on the system.
- pacman -Qe: Query Explicitly Installed: Filters the list to show only packages you manually installed yourself, omitting background dependency libraries. (Invaluable when auditing system bloat).
- pacman -Qdt: Query Orphans: Lists all packages that were installed as dependencies but are no longer required by anything else.
- pacman -Qi <package>: Displays detailed metadata about a locally installed package.
- pacman -Ql <package>: Lists every individual file installed on disk by a specific package.
- pacman -Qo <path>: Finds which local package owns a specific file path on disk (the Arch equivalent of dpkg -S or rpm -qf).
Comprehensive Hands-on Practice & Examples (pacman)
Example 1: Finding Which Package Owns a File (pacman -Qo)
If you want to know what installed package owns /usr/bin/ping:
pacman -Qo /usr/bin/ping
Expected Output:
/usr/bin/ping is owned by iputils 20240117-1
Example 2: Pruning Orphaned Dependencies
Over months of installing and removing software, orphaned packages accumulate on your drive. You can identify and remove all orphans in two clean commands:
# 1. List current orphaned dependencies
pacman -Qdt
# 2. Purge them completely from the system
sudo pacman -Rns $(pacman -Qdtq)
(Where -Qdtq outputs quiet, PIDs/names-only lists of orphans to pass directly into pacman -Rns).
Part 4: Package Cache Maintenance (pacman -Sc & -Scc)
Unlike apt or dnf, which automatically clean up downloaded installer packages after installation, pacman retains every downloaded package version in a local cache directory located at /var/cache/pacman/pkg/.
- Why? This local cache is a lifesaver on Arch Linux. If an update introduces a bug or breaks an application, you can instantly downgrade to a previous working package version stored in your cache.
- The Downside: Over time, this cache swells gigabytes in size as packages update continuously.
1. Cleaning Old Cached Packages (pacman -Sc)
To remove all cached versions of packages that are not currently installed on your system, while keeping backups of installed packages:
sudo pacman -Sc
2. Purging the Entire Cache (pacman -Scc)
To wipe the cache directory completely clean and recover maximum disk space (caution: you will lose local downgrade archives):
sudo pacman -Scc
Part 5: Extending pacman — The Arch User Repository (AUR)
While official Arch repositories contain thousands of software packages, developers across the world publish countless specialized tools, bleeding-edge libraries, and niche applications on the Arch User Repository (AUR)—a community-driven repository maintained by Arch users.
- What is the AUR? The AUR does not host pre-compiled binary packages. Instead, it hosts PKGBUILD scripts—recipe files containing instructions on how to download upstream source code, compile it locally, and package it into a .pkg.tar.zst for pacman.
- AUR Helpers: Because pacman itself does not natively download or build from the AUR, users utilize community command-line wrappers called AUR Helpers (such as yay or paru) to automate searching, downloading, and compiling AUR packages seamlessly.
Example of installing an AUR package using an AUR helper:
yay -S visual-studio-code-bin
Summary Checklist for Arch Linux and pacman
- [ ] Understand the Arch Linux rolling-release model and the role of pacman as a high-speed, minimalist package manager.
- [ ] Master the core operation flag structure: -S (Sync), -R (Remove), and -Q (Query).
- [ ] Always execute system updates using the full system upgrade command: sudo pacman -Syu.
- [ ] Use pacman -S to install packages and pacman -Rs to remove packages alongside their unused dependencies.
- [ ] Leverage query modifiers like pacman -Qe (explicitly installed) and pacman -Qdt (orphans) to audit system health.
- [ ] Manage the local package cache at /var/cache/pacman/pkg/ using pacman -Sc to reclaim disk space while preserving downgrade safety.
- [ ] Understand the Arch User Repository (AUR) and how AUR helpers like yay extend pacman functionality.
Congratulations! You have successfully completed Chapter 7. You have expanded your Linux administration skillset from system maintenance and networking to full control over software installation, dependency resolution, application sandboxing, and package architecture across every major Linux distribution ecosystem.
Let’s review the core concepts and administrative tools you’ve mastered throughout this chapter:
- Debian & Ubuntu Ecosystem (dpkg & apt): Installing local .deb binaries directly (dpkg -i), inspecting package file manifests (dpkg -L), synchronizing remote repository index databases (apt update), performing safe distribution-wide upgrades (apt upgrade), managing clean software installations and purges (apt install, apt remove, apt purge), and clearing orphaned dependency libraries (apt autoremove).
- Red Hat & Fedora Ecosystem (rpm, yum, & dnf): Auditing low-level .rpm packages (rpm -ivh, rpm -qf), using high-level modern package management with dnf, managing EPEL repositories, and utilizing transactional safety and rollbacks (dnf history undo).
- Universal Package Managers (snap & flatpak): Understanding containerized application packaging to bypass distro fragmentation, managing snap SquashFS mounted images and confinement levels (snap install, –classic), and leveraging desktop sandboxing with shared runtimes on Flathub (flatpak).
- Arch Linux Ecosystem (pacman): Operating within a rolling-release distribution model, mastering pacman’s fast single-character operation flags for full system upgrades (pacman -Syu), recursive package removal (pacman -Rs), local database queries (pacman -Qe, pacman -Qdt), cache maintenance (pacman -Sc), and compiling software from the Arch User Repository (AUR).
You now possess a complete understanding of how software is built, distributed, updated, and isolated across the entire Linux landscape.
Chapter 8: Environment Variables, Aliases, and Configuration
Section 8.1: Shell Environment Variables — env, printenv, export, and Core Variables ($PATH, $USER, $HOME)
Throughout Chapters 1 through 7, you have mastered file navigation, text filtering, user permissions, process monitoring, network diagnostics, remote access via SSH, data transfer, and multi-distribution package management (apt, dnf, pacman, snap, flatpak). You can build, secure, update, and maintain complex Linux systems with precision.
However, as you spend more time in the terminal, you will notice that your shell environment—the interactive command-line interface waiting for your input—maintains a wealth of invisible state information behind the scenes.
- How does your shell instantly know where to look when you type git or nginx without you specifying the absolute file path /usr/bin/git?
- How do scripts know which user is currently executing them?
- How do applications locate configuration directories, system languages, and temporary storage paths?
In this section, we begin Chapter 8 by examining the foundational mechanism that powers shell customization and process communication: Environment Variables.
What is an Environment Variable?
In Unix and Linux operating systems, every running process possesses an environment block—a dynamically allocated block of memory containing key-value pairs (KEY=value) passed from a parent process to its child processes.
When you open a terminal, your login shell initializes an environment filled with configuration settings, user preferences, and system paths. When you execute a command (such as running a Python script or launching a compiler), that command spawns as a child process and automatically inherits a copy of those environment variables.
Shell Variables vs. Environment Variables
It is important to distinguish between local shell variables and true environment variables:
- Local Shell Variables: Stored exclusively within the current shell session. They are invisible to external programs or child processes spawned from your shell.
- Environment Variables: Exported variables that are passed down to any child process or script executed within that session.
Part 1: Inspecting the Environment (env and printenv)
Before modifying your environment, you must know how to inspect it. Linux provides two primary utilities for viewing active environment variables: env and printenv.
envorprintenv[variable_name]
1. The env Command
Running env without arguments dumps every single active environment variable currently defined in your shell session to the terminal screen:
env
Expected Output (Truncated):
SHELL=/bin/bash
USER=alex
PWD=/home/alex
HOME=/home/alex
MAIL=/var/mail/alex
TERM=xterm-256color
SHLVL=1
PATH=/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin
_=/usr/bin/env
2. The printenv Command
While env can also run command wrappers, printenv is specifically optimized for printing environment variables. If you want to inspect a single variable without wading through hundreds of lines of output, pass the variable name as an argument:
printenv USER
Expected Output:
alex
Part 2: Creating and Exporting Variables (export)
If you define a variable in your shell using standard assignment syntax (MY_VAR=”hello”), it remains a local shell variable and will not be accessible to child scripts or programs.
To convert a shell variable into a true environment variable that can be inherited by child processes, you must use the export command.
exportVARIABLE_NAME=”value”
Comprehensive Hands-on Practice: Exporting and Inheritance
Let’s observe how export scoping works in practice.
- Define a local shell variable:
- Bash
MY_SETTING=”production”
Verify it with printenv:- Bash
printenv MY_SETTING
(Notice that nothing prints out because the variable is local to the shell, not exported to the environment).- Export the variable:
- Bash
export MY_SETTING=”production”
Verify it again:- Bash
printenv MY_SETTING
Expected Output:- Plaintext
production
Test Child Process Inheritance: Spawn a sub-shell to verify that child processes inherit exported variables:- Bash
# Launch a new nested bash sub-shell
# Check if the variable survived into the child process
echo $MY_SETTING
Expected Output:- Plaintext
production
(Exit the sub-shell by typing exit).
Part 3: Core System Environment Variables
While you can create custom environment variables for your own applications, Linux relies on several core standard variables to govern system behavior.
CoreSystemEnvironmentVariablesReference
| Variable Name | Description | Example Value |
| $PATH | The colon-separated list of directory paths where the shell searches for executable binaries. | /usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin |
| $USER | The username of the currently logged-in user executing the shell session. | alex |
| $HOME | The absolute file path to the current user’s home directory. | /home/alex |
| $SHELL | The absolute path to the user’s default login shell interpreter. | /bin/bash or /bin/zsh |
| $PWD | Present Working Directory: The absolute path of the directory you are currently standing in. | /var/www/html |
| $LANG | Specifies the system character encoding and language localization setting. | en_US.UTF-8 |
Deep Dive into Core Variables
1. The Execution Lifeline: $PATH
When you type a command like ls, git, or python into your terminal, how does the Linux kernel know where that program’s binary file lives on disk? It does not search your entire hard drive (which would take agonizingly long). Instead, it consults the $PATH environment variable.
Let’s inspect your current $PATH:
echo $PATH
Expected Output:
/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin
How the Shell Uses $PATH:
- The paths are separated by colons (:).
- When you execute ls, the shell scans directories from left to right:
- First, it checks /usr/local/sbin/ls. If not found…
- It checks /usr/local/bin/ls. If not found…
- It checks /usr/sbin/ls. If not found…
- It checks /usr/bin/ls. Found! It executes the binary immediately.
- First, it checks /usr/local/sbin/ls. If not found…
- If the executable is not present in any directory listed in $PATH, the shell halts and returns the famous error: bash: command not found.
Adding a Custom Directory to $PATH
If you write custom scripts or install binary tools into a personal folder (such as ~/bin/), you can add that directory to your $PATH dynamically:
export PATH=”$HOME/bin:$PATH”
(By prepending $HOME/bin to the front of the existing $PATH, your custom scripts will take search precedence over system binaries).
2. User Identity: $USER and $LOGNAME
The $USER environment variable stores the username of the account currently operating the terminal session.
echo “Current active user is: $USER”
In shell scripts, $USER is frequently used in conditional logic to ensure that a maintenance script is not accidentally executed by an unprivileged standard user instead of root.
3. The Home Directory: $HOME
The $HOME variable points directly to the authenticated user’s home directory (/home/username or /root).
Using $HOME in scripts and commands is much safer and more portable than hardcoding absolute user paths, because it adapts automatically regardless of which user account executes the script.
# Safely navigate to your configuration backup folder inside your home directory
cd “$HOME/.config”
Summary Checklist for Environment Variables
- [ ] Understand that environment variables pass configuration state and key-value data from parent shells down to child processes.
- [ ] Use env to dump all active environment variables, and printenv [VAR] to inspect specific variables.
- [ ] Use export KEY=”value” to convert local shell variables into inherited environment variables.
- [ ] Understand how the colon-separated $PATH variable dictates where the shell searches for executable binaries.
- [ ] Utilize core variables like $USER and $HOME in scripts for dynamic, portable path resolution.
Section 8.2: Shell Customization — Aliases, Command History, and Initialization Files
In the previous section, we explored the mechanics of shell environment variables (env, printenv, export) and examined how core variables like $PATH, $USER, and $HOME govern system behavior and executable binary lookups.
While understanding environment variables allows you to control where the shell searches for programs and how child processes inherit configuration state, typing long, complex command strings repeatedly throughout your administrative workday is inefficient.
- What if you want a shortcut to execute a complex, multi-flag log-tailing or backup command with a single word?
- How do you quickly recall and re-execute a command you typed twenty minutes ago without re-typing it from scratch?
- How do you ensure that your custom environment variables, PATH modifications, and shortcuts load automatically every single time you open a new terminal session?
In this section, we examine shell customization through custom command aliases, command history management, and permanent shell configuration initialization files (.bashrc, .bash_profile, .zshrc, and source).
Part 1: Creating Custom Command Shortcuts — The alias and unalias Commands
As a Linux administrator, you will frequently find yourself typing identical long command variations multiple times a day. For example, instead of running a basic ls, you might prefer a detailed, human-readable file list with hidden files included: ls -lah –color=auto.
Instead of typing those flags every time, you can create a custom shorthand using the alias command.
aliasname=’commandstring’
Comprehensive Hands-on Practice: Using alias
Example 1: Creating a Custom ll Alias
To map the shorthand ll to a verbose, colored listing command:
alias ll=’ls -lah –color=auto’
Once executed, whenever you type ll into your terminal, the shell transparently expands it and runs ls -lah –color=auto.
Example 2: Viewing Active Aliases
To view all active aliases currently defined in your interactive shell session, run alias without arguments:
alias
Expected Output:
alias egrep=’egrep –color=auto’
alias fgrep=’fgrep –color=auto’
alias grep=’grep –color=auto’
alias l=’ls -CF’
alias la=’ls -A’
alias ll=’ls -alF’
alias ls=’ls –color=auto’
Example 3: Removing an Alias with unalias
If you no longer want an alias active in your current shell session, you can remove it using the unalias command:
unalias ll
The Scope and Limitation of Runtime Aliases
⚠️ Crucial Caveat: Aliases created directly on the command line using alias are temporary. They exist solely in the memory of your current active terminal session. If you close your terminal window or open a new SSH connection, those aliases disappear entirely. To make aliases permanent, they must be written into your shell configuration files (which we will explore shortly).
Part 2: Reviewing and Repeating Previous Commands — The history Command
Every time you type a command into your terminal, your shell records it in an internal history list. When your session ends or closes gracefully, that history is saved to a disk file (such as ~/.bash_history).
The history command is an indispensable productivity utility used to review past commands, search for previous syntax, and re-execute complex operations without retyping them.
history[options]or!number
Essential History Shortcuts and Syntax
CommandHistoryReference
| Syntax / Command | Description |
| history | Dumps a numbered list of all commands stored in your current session history buffer. |
| history 20 | Displays only the last 20 commands executed in your session. |
| !N | Re-executes command number N from your history list (e.g., !42). |
| !! | Re-executes the immediately preceding command. (Invaluable when you forget to prepend sudo: type sudo !!). |
| !string | Re-executes the most recent command starting with the string (e.g., !nginx). |
| Ctrl + R | Reverse Incremental Search: An interactive search tool that lets you type a keyword to find past commands instantly. |
Comprehensive Hands-on Practice: Mastering History
Example 1: The Magic of sudo !!
Imagine you spend two minutes crafting a complex system update command, press Enter, and get a permission denied error:
apt update && apt upgrade -y
# Output: Permission denied. E: Could not open lock file…
Instead of pressing the Up arrow and moving your cursor to the front, you simply type:
sudo !!
The shell instantly evaluates !! as the previous command, expanding it into sudo apt update && apt upgrade -y and executing it with root privileges.
Example 2: Interactive Reverse Search (Ctrl + R)
If you executed a complex database backup script three days ago and cannot remember the exact syntax, press Ctrl + R in your terminal.
The prompt changes to:
(reverse-i-search)`’:
As you begin typing letters (e.g., pg_dump), the terminal dynamically searches through your historical logs and displays the most recent matching command. Press Enter to execute it immediately, or Left/Right arrow keys to edit it before running.
Part 3: Shell Configuration Files and Initialization
We have now explored environment variables, aliases, and command history. But how do we tie these customizations together so they load automatically every time we open a terminal?
The answer lies in Shell Configuration Initialization Files—hidden text files located in your home directory (~) that execute automatically whenever a shell session starts.
The Shell Startup Lifecycle: Login vs. Non-Login Shells
To understand which configuration file to edit, you must understand the two primary types of shell sessions:
- Login Shell: The initial shell session you enter when you log into a machine physically, via SSH (ssh user@host), or after entering your credentials. A login shell reads comprehensive environment settings.
- Non-Login Shell (Interactive Shell): A sub-shell opened inside a GUI terminal emulator (like GNOME Terminal or iTerm2) or when you spawn a nested shell (bash) from an existing session.
Core Configuration Files Reference
ConfigurationFilesEcosystem
| File Path | Description | Applicable Shell |
| ~/.bash_profile or ~/.profile | Login Shell Configuration: Executed only when starting a login session. Used for environment variables ($PATH) that only need to be set once per login. | Bash |
| ~/.bashrc | Non-Login / Interactive Shell Configuration: Executed every time you open a new interactive terminal window or tab. Used for aliases, prompt styling, and shell functions. | Bash |
| ~/.zshrc | Zsh Configuration: The primary initialization file for the Z shell (zsh), handling both login and interactive settings. | Zsh (zsh) |
| ~/.bash_history | The disk-storage file where command history strings are persisted across sessions. | Bash |
Part 4: Applying Configuration Changes Instantly — The source Command
When you edit your configuration file (such as adding a new alias to ~/.bashrc), those changes do not automatically affect your current open terminal window. By default, configuration files are read only when a shell starts.
To force your current active shell session to re-read and apply updates from a configuration file immediately without restarting your terminal, you use the source command (or its POSIX shorthand, the dot operator .).
source/.bashrcor./.bashrc
Comprehensive Hands-on Practice: Building a Permanent Customization Workflow
Let’s walk through a complete, end-to-end workflow demonstrating how to create permanent aliases and environment variables using configuration files.
Step 1: Open Your Configuration File
Open your interactive Bash configuration file in your favorite command-line text editor (such as nano):
nano ~/.bashrc
Step 2: Add Custom Aliases and Variables
Scroll to the bottom of the file and append your custom configurations:
# — Custom System Administrator Aliases —
alias update=’sudo apt update && sudo apt upgrade -y’
alias cls=’clear’
alias k9=’kill -9′
# — Custom Environment Variables —
export EDITOR=’nano’
export WORKSPACE=”$HOME/development/projects”
Step 3: Save and Exit
In nano, save your changes by pressing Ctrl + O, hit Enter to confirm the filename, and exit by pressing Ctrl + X.
Step 4: Apply Changes Instantly via source
Instead of closing your terminal and logging back in, activate your changes immediately:
source ~/.bashrc
Step 5: Test Your Customizations
Verify that your new aliases and environment variables are active:
# Test the new cls alias
cls
# Test the new WORKSPACE environment variable
echo $WORKSPACE
Expected Output:
/home/alex/development/projects
Your custom shortcuts and environment variables are now permanently saved in ~/.bashrc and will load automatically every time you open a new terminal session.
Summary Checklist for Shell Customization
- [ ] Use alias to create temporary shorthand shortcuts for complex or frequently used commands.
- [ ] Use unalias to remove active session aliases.
- [ ] Use history to audit past commands, and master shortcuts like !! (sudo !!) and Ctrl + R (reverse search) to boost terminal productivity.
- [ ] Understand the distinction between Login Shells (~/.bash_profile) and Interactive Non-Login Shells (~/.bashrc).
- [ ] Persistently store aliases, functions, and environment variables inside your shell configuration files.
- [ ] Use source ~/.bashrc to apply configuration modifications instantly to your active terminal session without logging out.
Congratulations! You have successfully completed Chapter 8. You have learned how to customize your shell environment, manage environment variables, and tailor your terminal workflow for maximum efficiency.
Let’s review the core concepts and utilities you’ve mastered throughout this chapter:
- Environment Variables (env, printenv, export): Understanding how processes inherit configuration state, inspecting active variables with env and printenv, and promoting local shell variables into inherited environment variables using export.
- Core System Variables ($PATH, $USER, $HOME): Mastering the colon-separated binary search path ($PATH), user identity tracking ($USER), and portable path resolution ($HOME).
- Command Shortcuts (alias and unalias): Creating temporary shorthand aliases for complex commands and removing them when no longer needed.
- Command History (history, !!, Ctrl + R): Reviewing session history buffers, instantly repeating the previous command with !! (such as sudo !!), and searching past syntax interactively using reverse-search (Ctrl + R).
- Initialization Files (.bashrc, .bash_profile, .zshrc) & Sourcing (source): Structuring persistent terminal configurations across login and interactive shell sessions, and applying changes instantly to your active terminal window without logging out.
You now have complete control over your shell environment and custom workflows.
Chapter 9: Shell Scripting Fundamentals
Section 9.1: Anatomy of a Script — Shebangs, Permissions, and Execution
Throughout Chapters 1 through 8, you have mastered an extensive array of Linux administration skills: navigating the filesystem, filtering text streams, managing users and file permissions, monitoring active processes, auditing disk storage, configuring networks, troubleshooting DNS and packet paths, downloading web resources, administering package ecosystems across Debian, Red Hat, and Arch, and customizing your shell environment with variables, aliases, and initialization files.
Every command you have executed thus far has been interactive—typed directly into the terminal prompt, evaluated by the shell, and discarded or saved to history. But as an administrator or developer, you will frequently encounter repetitive operational workflows: deploying applications, parsing log files every night, backing up databases, or provisioning cloud infrastructure. Typing dozens of individual commands manually every day is tedious, error-prone, and inefficient.
To eliminate repetitive manual toil, we turn to Shell Scripting. In this section, we begin Chapter 9 by examining what shell scripting is, dissecting the anatomy of a script, exploring the critical role of the shebang line, and understanding how to grant execution permissions using chmod +x.
What is Shell Scripting?
At its core, a shell script is a plain-text file containing a sequence of shell commands. Instead of typing commands one by one into an interactive terminal prompt, you save them inside a file. When you execute that file, the shell reads the script line by line and executes each command sequentially, exactly as if you had typed them by hand.
Why Use Shell Scripts?
- Automation: Transform multi-step operational tasks (like updating systems, backing up directories, and pruning old logs) into a single command that runs automatically via cron jobs or background schedulers.
- Receptivity and Logic: Scripts are not merely static lists of commands; they support programming constructs like variables, loops, conditional branching (if/else), and error handling, turning the command line into a fully fledged programming environment.
- Reproducibility: Document complex infrastructure deployments in repeatable, version-controlled text files that can be executed identically across multiple servers.
Part 1: The Anatomy of a Basic Script
Let’s examine the structural makeup of a standard Bash script. Every robust script is composed of three foundational elements:
- The Interpreter Directive (The Shebang Line): Tells the operating system which interpreter should execute the file.
- Comments: Human-readable documentation explaining what the script does.
- Command Logic: The actual instructions executed sequentially.
Part 2: The Shebang Line (#!/bin/bash)
When you write a text file containing commands, how does the Linux kernel know how to execute it? When you run a script, the kernel reads the first line of the file to determine which program interpreter to load into memory.
This first line is universally known as the Shebang (derived from “sharp” for # and “bang” for !).
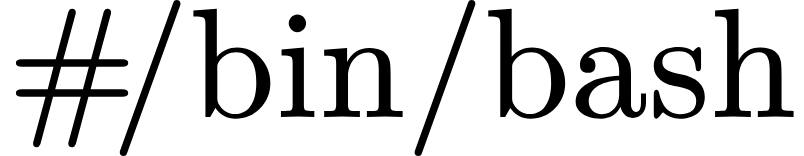
How the Shebang Works Under the Hood
- #! (Magic Number): The kernel recognizes the first two bytes of the file as #! (executable magic bytes). This signals that the file is an interpreted script rather than a raw binary executable.
- /bin/bash: The absolute path to the interpreter binary (in this case, the Bourne Again SHell). When you execute the script, the kernel automatically spawns /bin/bash and passes the script file path as an argument to it.
Common Shebang Variations
Depending on your script requirements, you may encounter different interpreter declarations:
- #!/bin/bash — Explicitly invokes the Bash shell.
- #!/bin/sh — Invokes the POSIX-compliant system shell (usually symbolic-linked to dash on Ubuntu for high execution speed).
- #!/usr/bin/env bash — A portable shebang that searches the user’s $PATH environment variable to find the bash binary, making it ideal for cross-platform compatibility.
Part 3: File Permissions and Execution (chmod +x)
Writing a script file and specifying a shebang line is not enough to run it directly. By default, when you create a new text file in Linux, the operating system denies execution permissions for security reasons.
If you attempt to run your script immediately after saving it:
./myscript.sh
Expected Output:
bash: ./myscript.sh: Permission denied
Why Permission is Denied
Linux enforces strict security access controls via permission bits (r, w, x). A newly created file possesses read (r) and write (w) permissions, but lacks the execute (x) permission bit. The kernel refuses to run code from a file that is not explicitly marked as executable.
Granting Execution Rights: chmod +x
To give the file execution permissions, you use the chmod (change mode) command with the +x (add execute) flag:
chmod+xscript_name.sh
chmod +x myscript.sh
Once executed, the file’s permission flags update, allowing you to run it directly as an executable program.
Part 4: Running Your Script — ./script.sh vs. bash script.sh
Once execution permissions are set, there are two primary ways to run a script, and understanding the difference is critical for system administrators:
1. Direct Execution (./myscript.sh)
When you run a script using its relative or absolute path (prefixed with ./):
- The kernel reads the shebang line (#!/bin/bash).
- The kernel spawns a new, isolated sub-shell process running Bash.
- The script executes inside that child environment. When the script finishes, the sub-shell terminates, and you return to your interactive parent shell.
- Requirement: Requires explicit execution permissions (chmod +x).
2. Interpreted Execution (bash myscript.sh)
When you explicitly invoke the interpreter from the command line:
- You bypass the shebang line entirely; you are explicitly commanding the bash binary to open and parse the text file.
- Requirement: Does not require execution permissions (chmod +x is optional here) because you are not executing the file directly; you are passing it as a text file argument to the bash program.
Comprehensive Hands-on Practice: Writing Your First Script
Let’s walk through a complete, end-to-end workflow demonstrating how to create, format, permission, and execute your very first shell script.
Step 1: Create the Script File
Open a new file named hello.sh using your preferred terminal text editor (such as nano):
nano hello.sh
Step 2: Write the Script Content
Type the following code into the editor:
#!/bin/bash
# ==========================================
# Script Name: hello.sh
# Description: A simple demonstration script
# ==========================================
echo “Hello, Linux Administrator!”
echo “Current active user: $USER”
echo “Current working directory: $PWD”
echo “System uptime:”
uptime
Step 3: Save and Exit
In nano, save the file by pressing Ctrl + O, hit Enter to confirm, and exit by pressing Ctrl + X.
Step 4: Grant Execution Permissions
Before running the script, grant execution rights using chmod:
chmod +x hello.sh
Step 5: Execute the Script
Run your script from the terminal:
./hello.sh
Expected Output:
Hello, Linux Administrator!
Current active user: alex
Current working directory: /home/alex
System uptime:
10:05:00 up 5 days, 2:14, 2 users, load average: 0.00, 0.01, 0.05
Best Practices for Script Anatomy
- Always Include a Shebang: Never omit #!/bin/bash. Without it, the operating system relies on whatever default shell the user happens to be running, which can cause syntax errors if the script relies on Bash-specific features.
- Document with Comments (#): Use hash symbols to write comments explaining why the script performs specific actions, especially when dealing with complex automation logic or file paths.
- Use Meaningful Filenames: Name your script files clearly (e.g., backup_db.sh or deploy_app.sh) and avoid naming custom scripts after existing system commands (like naming a script test or ls).
Summary Checklist for Script Anatomy
- [ ] Understand that shell scripts automate multi-step command sequences and support programming logic, variables, and conditionals.
- [ ] Use the Shebang line (#!/bin/bash) as the first line of every script to instruct the kernel on which interpreter to load.
- [ ] Recognize that newly created script files lack execution rights and will throw Permission denied errors.
- [ ] Use chmod +x to grant execution permissions to script files.
- [ ] Differentiate between direct execution (./script.sh, which respects the shebang and spawns a sub-shell) and explicit interpreter invocation (bash script.sh).
Section 9.2: Variables, User Input, and Positional Arguments
In the previous section, we examined the anatomy of a shell script, learning how the kernel interprets the shebang line (#!/bin/bash), why execution permissions (chmod +x) are required, and how scripts execute sequentially within a sub-shell environment.
However, the script we built in Section 9.1 was entirely static. It printed a hardcoded greeting, outputted current user information, and executed system commands identically every single time it ran. A truly powerful automation script cannot be entirely static; it must possess the ability to store state dynamically, prompt users for interactive input, and accept configuration parameters directly from the command line when invoked.
In this section, we examine the core mechanics of variables, interactive user input via read, and positional command-line arguments ($1, $2, $#).
Part 1: Assigning and Referencing Variables in Bash
A variable is a symbolic name associated with a value stored in memory. In shell scripting, variables allow you to store text strings, numbers, file paths, and command outputs for later reuse.
1. Variable Assignment Syntax
Assigning a variable in Bash is straightforward: you write the variable name, an equals sign (=), and the value.
VARIABLE_NAME=”value”
SERVER_NAME=”web-server-01″
MAX_CONNECTIONS=500
BACKUP_DIR=”/var/backups”
⚠️ The Golden Rule of Bash Assignment: No Spaces
Unlike modern programming languages (Python, JavaScript), Bash is extremely sensitive to whitespace around the equals sign.
- Correct: USERNAME=”alex” (No spaces).
- Incorrect: USERNAME = “alex” (Bash will interpret USERNAME as a command name and throw a “command not found” error).
2. Referencing Variables ($)
To retrieve or expand the value stored inside a variable, you must prepend a dollar sign ($) to its name.
SERVER_NAME=”production-db”
echo “Connecting to $SERVER_NAME…”
While you can often reference variables simply as $VAR, using explicit curly braces—${VAR}—is considered best practice when variables are immediately adjacent to other text or punctuation.
PREFIX=”app”
# Without braces, Bash looks for a variable named $PREFIX_v1 (which is empty)
echo “Deploying version ${PREFIX}_v1.0”
3. String Interpolation: Double Quotes vs. Single Quotes
When assigning or echoing variables, the type of quotation marks you use dictates how Bash handles string evaluation:
- Double Quotes (” “): Enable variable interpolation. Bash evaluates variables inside double quotes, replacing $VAR with its actual stored value.
- Bash
NAME=”Alex”
echo “Hello, $NAME” # Output: Hello, Alex
Single Quotes (‘ ‘): Enforce literal interpretation. Bash treats everything inside single quotes as raw literal text, ignoring dollar signs entirely.- Bash
NAME=”Alex”
echo ‘Hello, $NAME’ # Output: Hello, $NAME
4. Capturing Command Output into Variables (Command Substitution)
One of the most powerful features in shell scripting is Command Substitution. You can execute any valid shell command and store its stdout output directly inside a variable using backticks (`) or modern syntax ($(…)).
# Capture the current date and time
CURRENT_DATE=$(date +”%Y-%m-%d_%H-%M-%S”)
echo “Backup initiated on: $CURRENT_DATE”
# Capture the currently active system kernel
KERNEL_VERSION=$(uname -r)
echo “Running kernel: $KERNEL_VERSION”
Part 2: Interactive User Input with the read Command
While scripts are often automated, many administrative workflows require interactive input—prompting an operator for confirmation, asking for a database password, or requesting a target IP address before execution.
The read command pauses script execution, waits for the user to type input on the keyboard, and stores that input into one or more variables.
read[options]variable_name
Essential Options and Flags for read
Common`read`Options
| Option | Flag Name | Description |
| -p “PROMPT”, –prompt=”PROMPT” | Custom Prompt | Prints a descriptive text prompt before pausing for input on the same line. |
| -s, –silent | Silent Mode | Hides user input from echoing back to the screen (vital for secure password entry). |
| -t SECS, –timeout=SECS | Timeout Limit | Automatically aborts the read request if the user does not respond within SECS seconds. |
| -a ARRAY, –array=ARRAY | Array Input | Reads multiple space-separated words into an indexed array variable. |
Comprehensive Hands-on Practice: Interactive Scripts
Example 1: Basic Prompting
Let’s write a script that interactively asks for a user’s name and age:
#!/bin/bash
read -p “Enter your username: ” USER_INPUT
echo “Welcome back, $USER_INPUT!”
Example 2: Secure Password Input (-s)
When writing scripts that require sensitive credentials (such as database administrative passwords), you must prevent the password from echoing to the terminal screen where onlookers or system history logs can capture it:
#!/bin/bash
echo “=== Secure Database Setup ===”
read -p “Enter database username: ” DB_USER
read -s -p “Enter database password: ” DB_PASS
echo “” # Prints a newline after silent input
echo “Configuration received for user: $DB_USER”
The -s flag suppresses keyboard echoing, ensuring confidential passwords remain invisible during typing.
Part 3: Positional Arguments ($1, $2, $#, $@)
While interactive prompts (read) are useful for user-facing setup scripts, they are impractical for automation tools, cron jobs, and CI/CD deployment pipelines where human operators are not present to type answers.
Instead, production scripts receive inputs from the command line when invoked. These are known as Positional Arguments.
When you execute a script like this:
./deploy.sh production v2.1.0 9090
Bash automatically assigns each space-separated word following the script name to special, pre-defined system variables known as positional parameters.
PositionalParametersReference
| Parameter | Description |
| $0 | The filename of the script itself (./deploy.sh). |
| $1 | The first argument passed to the script (production). |
| $2 | The second argument passed to the script (v2.1.0). |
| $3 | The third argument passed to the script (9090). |
| ${10} | The tenth argument (Note: double digits require curly braces ${10}). |
| $# | Argument Count: The total number of arguments passed to the script. |
| $@ | All Arguments: Expands to all positional arguments as separate individual strings. |
Comprehensive Hands-on Practice: Positional Argument Scripting
Let’s build a robust, production-grade backup script that accepts a source directory and a destination path as command-line arguments.
Create a file named safe_backup.sh:
#!/bin/bash
# ====================================================
# Script: safe_backup.sh
# Description: Demonstrates positional arguments & validation
# ====================================================
# 1. Validate that exactly 2 arguments were provided
if [ “$#” -ne 2 ]; then
echo “Error: Invalid argument count!”
echo “Usage: $0 <source_directory> <destination_directory>”
exit 1
fi
# 2. Assign positional arguments to descriptive variable names
SRC_DIR=”$1″
DEST_DIR=”$2″
echo “—————————————-“
echo “Initiating backup process…”
echo “Source path : $SRC_DIR”
echo “Destination path : $DEST_DIR”
echo “—————————————-“
# 3. Verify source directory exists
if [ ! -d “$SRC_DIR” ]; then
echo “Error: Source directory ‘$SRC_DIR’ does not exist!”
exit 2
fi
# 4. Perform the synchronization using rsync
rsync -avh “$SRC_DIR” “$DEST_DIR”
echo “Backup completed successfully!”
How to Execute This Script:
- Test with missing arguments:
- Bash
./safe_backup.sh
Output: Triggers the error check, prints usage instructions (Usage: ./safe_backup.sh <source> <destination>), and exits safely.- Test with valid arguments:
- Bash
./safe_backup.sh /etc/nginx /var/backups/nginx_backup
Output: Assigns /etc/nginx to $1, /var/backups/nginx_backup to $2, validates existence, and executes the backup.
Summary Checklist for Variables and User Input
- [ ] Understand variable assignment syntax (VAR=”value”) and remember the golden rule: absolutely no spaces around the equals sign.
- [ ] Use double quotes (” “) for variable interpolation and single quotes (‘ ‘) for literal string preservation.
- [ ] Capture command output into variables using command substitution ($(command)).
- [ ] Use the read command for interactive input, leveraging -p for custom prompts and -s for silent password security.
- [ ] Master positional arguments ($1, $2, $3) to pass runtime parameters into scripts from the command line.
- [ ] Use $# to validate argument counts and $0 to reference the executing script filename in usage messages.
Section 9.3: Control Flow — Conditionals and Iteration Loops
Throughout Chapter 9, you have mastered the foundational mechanics of shell scripting: understanding the shebang line (#!/bin/bash), granting execution permissions (chmod +x), assigning and referencing variables, capturing command outputs via substitution, prompting for interactive input with read, and parsing command-line parameters using positional arguments ($1, $2, $#).
However, all the scripts we have built thus far execute in a strictly linear fashion. Every line runs sequentially from top to bottom, without deviation, branching, or repetition. In the real world of systems administration and software deployment, scripts must be intelligent.
- How does a backup script check if a destination directory exists before attempting to write files, failing gracefully or creating the directory if it is missing?
- How does an administrative monitoring script iterate through a list of fifty remote server IP addresses to check network reachability?
- How does a log-parsing script read through gigabytes of text line by line until it finds a specific error pattern?
To answer these questions, we turn to Control Flow. In this section, we examine conditional branching (if, elif, else, test operators) and iterative repetition loops (for loops and while loops).
Part 1: Conditional Branching — The if Statement
Conditional branching allows your script to evaluate conditions and execute different blocks of code depending on whether those conditions evaluate to true or false.
The Core Anatomy of a Bash if Statement
Unlike traditional programming languages that use curly braces {} or indentation to define code blocks, Bash relies on explicit keywords: if, then, elif (else if), else, and fi (if spelled backward to close the block).
if [ condition ]; then
# Code executed if condition is true
elif [ another_condition ]; then
# Code executed if the second condition is true
else
# Code executed if all conditions are false
fi
The Secret Engine: Exit Statuses ($?)
Behind the scenes, Bash does not evaluate “true” or “false” as boolean data types. Instead, every command and test in Linux returns an Exit Status integer upon completion:
- 0 (Zero): Indicates Success (evaluated as true in conditional checks).
- Non-zero integer (1 through 255): Indicates Failure or Error (evaluated as false in conditional checks).
You can inspect the exit status of the immediately preceding command by echoing $?:
ls /etc/hosts
echo $? # Outputs 0 (success)
ls /nonexistent_directory
echo $? # Outputs 2 (or another non-zero integer representing failure)
Test Operators and Bracket Types
When writing conditional tests in Bash, you will encounter three primary syntactical wrappers. Understanding their differences is vital:
- Test Brackets ([ … ]): The standard POSIX test command wrapper. Crucial Rule: You must include spaces inside the brackets (e.g., [ “$VAR” = “value” ]). Omitting spaces causes syntax errors.
- Advanced Test Brackets ([[ … ]]): A modern Bash extension that offers enhanced features, including string pattern matching, regular expression support (=~), and safety against unquoted variable expansion errors.
- Arithmetic Evaluation ((( … ))): Designed specifically for mathematical and numeric comparisons (>, <, >=, <=, ==).
Comprehensive File, String, and Numeric Test Operators
BashTestOperatorsReference
| Operator Type | Flag / Syntax | Description | Example |
| File Tests | -f FILE | True if FILE exists and is a regular file. | [ -f /etc/passwd ] |
| -d DIR | True if DIR exists and is a directory. | [ -d /var/www ] | |
| -e PATH | True if PATH exists (file or directory). | [ -e /opt/app ] | |
| -r / -w / -x | True if file has read, write, or execute permissions. | [ -x /usr/bin/git ] | |
| String Tests | STR1 = STR2 | True if strings are identical. | [ “$ENV” = “prod” ] |
| STR1 != STR2 | True if strings are not identical. | [ “$ROLE” != “admin” ] | |
| -z STR | True if string length is zero (empty string). | [ -z “$USERNAME” ] | |
| -n STR | True if string length is non-zero (not empty). | [ -n “$PASSWORD” ] | |
| Numeric Tests | -eq / -ne | Equal (=) / Not Equal (!=) | [ “$COUNT” -eq 10 ] |
| -gt / -lt | Greater Than (>) / Less Than (<) | [ “$PORT” -gt 1024 ] | |
| -ge / -le | Greater/Equal (>=) / Less/Equal (<=) | [ “$DISK” -le 90 ] |
Comprehensive Hands-on Practice: Conditionals
Let’s write a robust script named check_service.sh that evaluates whether a configuration file exists and checks user privileges before executing administrative tasks.
#!/bin/bash
# ====================================================
# Script: check_service.sh
# Description: Demonstrates conditionals and test operators
# ====================================================
CONFIG_FILE=”/etc/nginx/nginx.conf”
# 1. Check if the current user is root (UID 0)
if [ “$EUID” -ne 0 ]; then
echo “Error: This script must be run as root or with sudo privileges!”
exit 1
fi
# 2. Check if the configuration file exists (-f)
if [ -f “$CONFIG_FILE” ]; then
echo “Success: Configuration file ‘$CONFIG_FILE’ found.”
# 3. Check if the file is readable (-r)
if [ -r “$CONFIG_FILE” ]; then
echo “Permissions OK: File is readable.”
else
echo “Warning: File exists but is unreadable!”
fi
else
echo “Error: Configuration file ‘$CONFIG_FILE’ does not exist!”
exit 2
fi
Part 2: Iteration and Loops (for and while)
When automation tasks require repeating an operation across multiple files, servers, or numerical increments, writing linear code becomes impossible. Loops allow your script to execute a block of code repeatedly until a specific condition is met or a collection is exhausted.
The for Loop
The for loop is used to iterate over a fixed list of items, such as a sequence of numbers, words, filenames, or command outputs.
Syntax 1: Iterating Over an Explicit List
for item in item1 item2 item3; do
echo “Current item: $item”
done
Syntax 2: Iterating Over Files and Glob Patterns
You can combine filename expansion wildcards with for loops to perform batch processing across directories:
for logfile in /var/log/*.log; do
echo “Processing log file: $logfile”
# Insert processing logic here
done
Syntax 3: C-Style Numeric for Loops
For traditional numeric counting (e.g., repeating a task exactly 10 times), Bash supports C-style loop syntax using double arithmetic parentheses:
for ((i=1; i<=5; i++)); do
echo “Iteration count: $i”
done
Comprehensive Hands-on Practice: The for Loop
Let’s build a batch server ping utility (ping_check.sh) that iterates through a list of server IP addresses and tests network connectivity:
#!/bin/bash
# ====================================================
# Script: ping_check.sh
# Description: Demonstrates for loop iteration over servers
# ====================================================
SERVERS=(“192.168.1.1” “192.168.1.50” “8.8.8.8” “10.0.0.254”)
echo “Starting network reachability audit…”
echo “—————————————-“
for ip in “${SERVERS[@]}”; do
# Ping each server once (-c 1), suppressing output (-q)
if ping -c 1 -W 2 “$ip” &> /dev/null; then
echo “[ONLINE] Server $ip is responding.”
else
echo “[OFFLINE] Server $ip is unreachable!”
fi
done
echo “—————————————-“
echo “Audit complete.”
The while Loop
While for loops iterate over a predefined collection, the while loop executes a block of code repeatedly as long as a specified condition remains true.
If the condition evaluates to false when the loop starts—or becomes false during execution—the loop terminates immediately.
Core Syntax of a while Loop
while [ condition ]; do
# Code executed repeatedly while condition is true
# (Ensure something inside modifies the condition to avoid infinite loops!)
Classic Use Case 1: Counting Down
COUNTER=3
while [ “$COUNTER” -gt 0 ]; do
echo “Countdown: $COUNTER”
((COUNTER–)) # Decrement counter
sleep 1 # Pause for 1 second
done
echo “Liftoff!”
Classic Use Case 2: Reading Files Line-by-Line
One of the most powerful administrative applications of while loops is parsing text files or configuration logs line by line using the read command:
#!/bin/bash
# Read through a server inventory file line by line
while IFS= read -r line; do
echo “Processing inventory entry: $line”
done < /etc/hosts
Loop Control Statements: break and continue
Inside both for and while loops, you can alter execution flow using two essential control statements:
- break: Immediately terminates and exits the loop entirely, jumping to the code immediately following the loop block.
- continue: Skips the remainder of the current iteration and forces the loop to jump straight to the next iteration cycle.
# Example: Skip processing for a specific server IP using ‘continue’
for ip in “192.168.1.1” “10.0.0.1” “192.168.1.50”; do
if [ “$ip” = “10.0.0.1” ]; then
echo “Skipping restricted gateway $ip…”
continue
fi
echo “Processing server: $ip”
done
Summary Checklist for Control Flow
- [ ] Understand how conditional branching (if, elif, else, fi) alters script execution based on command exit statuses ($?).
- [ ] Master test operator brackets ([ … ], [[ … ]], and arithmetic (( … ))).
- [ ] Utilize file test operators (-f, -d, -e), string operators (=, !=, -z), and numeric operators (-eq, -gt) correctly.
- [ ] Use for loops to iterate over explicit lists, globbed file paths, and C-style numeric ranges.
- [ ] Use while loops for condition-driven repetition and robust line-by-line file reading.
- [ ] Control loop execution paths using break (to exit loops early) and continue (to skip iterations).
Section 9.4: Script Debugging and Error Handling
Throughout Chapter 9, you have mastered the foundational components of shell scripting: structuring scripts with shebang lines, granting execution permissions (chmod +x), assigning variables, capturing command substitutions, prompting for interactive input (read), parsing command-line parameters ($1, $2, $#), evaluating conditions with test operators, and executing repetitive tasks using for and while loops.
However, as your scripts grow in complexity—spanning hundreds of lines of logic, multiple nested loops, conditional branches, and file manipulations—things will inevitably break.
- What happens when a variable evaluates to an empty string, causing a file deletion command to wipe out an entire directory instead of a single log file?
- How do you pinpoint which line in a 300-line automation script caused a silent failure halfway through execution?
- How can you prevent a script from blindly marching forward after a critical command fails?
In this section, we examine the art and science of Shell Script Debugging and Error Handling.
Part 1: The Ultimate Tracing Utility — Running Scripts with bash -x
When an interactive command fails in your terminal, error messages usually print directly to your screen, allowing you to troubleshoot immediately. In shell scripts, however, errors often fail silently, produce confusing side effects, or leave you wondering why a variable evaluation evaluated incorrectly.
The most powerful built-in debugging mechanism in Bash is Execution Tracing, invoked via the -x flag.
bash-xscript_name.sh
How Execution Tracing Works Under the Hood
When you run a script with bash -x, the Bash interpreter enters debug mode. Before executing each line of code, Bash prints that line to your terminal screen preceded by a plus sign (+), showing you the exact expansion of variables, arguments, and command substitutions in real time.
TracingOutputNotation
- + (Plus Sign): Denotes a traced command line after variable expansion.
- ++ (Double Plus): Denotes nested command substitutions or sub-shells.
- Unpreceded lines: Represent the actual standard output (stdout) generated by your script’s commands.
Comprehensive Hands-on Practice: Debugging with bash -x
Let’s examine a deliberately flawed script named bad_backup.sh that contains a logic error:
#!/bin/bash
# ====================================================
# Script: bad_backup.sh (Flawed Version)
# ====================================================
BACKUP_DIR=”/var/backups”
TARGET_FILE=”$1″
echo “Starting backup for: $TARGET_FILE”
# Bug: If $TARGET_FILE is empty, this expands to “rm -rf /var/backups/”
rm -rf “$BACKUP_DIR/$TARGET_FILE”
echo “Backup cleanup complete.”
Running the Script in Debug Mode
If you execute this script with an empty argument while passing -x to the interpreter:
bash -x bad_backup.sh
Expected Traced Output:
+ BACKUP_DIR=/var/backups
+ TARGET_FILE=
+ echo ‘Starting backup for: ‘
Starting backup for:
+ rm -rf /var/backups/
+ echo ‘Backup cleanup complete.’
Backup cleanup complete.
Analysis: Looking at the traced output (+ rm -rf /var/backups/), you instantly identify the catastrophic bug: because $TARGET_FILE was empty, the deletion command expanded to wipe out the entire /var/backups/ directory! Tracing allows you to spot variable expansion failures before they cause irreversible production damage.
Part 2: Inline Tracing Control — set -x and set +x
Running an entire script under bash -x can generate thousands of lines of terminal output, making it difficult to isolate bugs in massive scripts.
Instead of tracing the entire file from start to finish, you can toggle debugging on and off dynamically inside specific sections of your script using the set command.
set-x(Enablestracingfromthislineonward)
set+x(Disablestracing)
Comprehensive Hands-on Practice: Targeted Tracing
#!/bin/bash
echo “Initializing system checks…”
# Normal execution here (not traced)
# Enable tracing exclusively around complex logic
set -x
USER_COUNT=$(cat /etc/passwd | grep -c “bash”)
HOME_DIR=”/home/alex”
set +x
echo “System checks completed. Found $USER_COUNT users.”
By bracketing only the suspect logic between set -x and set +x, you keep your debugging output clean and focused.
Part 3: Defensive Shell Scripting and Fail-Safe Options
By default, Bash is notoriously forgiving. If a command fails halfway through a script (e.g., a network download fails or a database connection drops), Bash ignores the error and blindly proceeds to execute the next line.
In professional administration and deployment scripting, this behavior is dangerous. To build robust, bulletproof scripts, administrators rely on Defensive Shell Options placed at the very top of their scripts.
Essential Defensive set Flags
DefensiveShellOptionsReference
| Option Flag | Name | Description |
| set -e | Exit on Error | Immediately terminates the script if any command exits with a non-zero (failure) status. |
| set -u | Unset Variables | Treats unset or uninitialized variables as fatal errors and aborts execution immediately. |
| set -o pipefail | Pipeline Failure | Ensures that if any command inside a multi-pipe fails, the entire pipeline’s exit status reflects that failure. |
Deep Dive into Defensive Options
1. set -e (Exit Immediately on Error)
Without set -e, if a critical command fails (like failing to mount a filesystem), the script continues running subsequent commands against an unmounted directory, potentially causing data corruption.
#!/bin/bash
set -e
echo “Step 1: Updating package lists…”
apt update # If this fails, the script stops immediately!
echo “Step 2: Installing packages…”
apt install -y nginx
2. set -u (Catch Typos in Variables)
Typing errors are common. If you define a variable named CONFIG_PATH but accidentally reference it later as $CONFG_PATH, Bash normally treats the typo as an empty string, leading to unpredictable behavior.
With set -u, Bash catches the typo instantly, prints an unbound variable error, and aborts execution.
#!/bin/bash
set -u
BACKUP_PATH=”/var/backups”
# Typo: $BACKUP_PAT instead of $BACKUP_PATH
cp -r /etc/nginx “$BACKUP_PAT”
# Output: bash: BACKUP_PAT: unbound variable (Script terminates)
3. set -o pipefail (Pipeline Safety)
Consider a pipeline that counts active connections: netstat -an | grep ESTABLISHED | wc -l.
- By default, the exit status of a pipeline is determined solely by the last command (wc -l), which almost always succeeds (0).
- If netstat encounters a fatal error and fails, the pipeline still returns 0 because of wc.
- Enabling set -o pipefail ensures that if any command in the chain fails, the entire pipeline reports failure.
Part 4: Error Trapping and Cleanup — The trap Command
When a script terminates unexpectedly due to an error, user cancellation (Ctrl + C), or system signals, it often leaves behind temporary files, lock files, or unfinished partial downloads scattered across the filesystem.
The trap command allows you to intercept operating system signals and script exits, executing a cleanup function automatically before the process dies.
trap’commands_to_run’SIGNAL_NAMES
Common Signals and Triggers
- EXIT: Triggers whenever the script exits (whether successfully or via error).
- ERR: Triggers specifically when a command returns a non-zero error status.
- SIGINT (Ctrl + C): Triggers when the user attempts to abort the script interactively.
Comprehensive Hands-on Practice: Robust Error Trapping
Let’s build a production-grade deployment script (secure_deploy.sh) that utilizes defensive set flags and a trap cleanup mechanism to ensure temporary files are never left behind:
#!/bin/bash
# ====================================================
# Script: secure_deploy.sh
# Description: Demonstrates defensive programming & trap cleanup
# ====================================================
# 1. Enable defensive flags
set -euo pipefail
# 2. Create a secure temporary working directory
TEMP_DIR=$(mktemp -d)
echo “Created temporary workspace at: $TEMP_DIR”
# 3. Define a cleanup function to remove temp files on exit
cleanup() {
echo “—————————————-“
echo “Running cleanup trap…”
if [ -d “$TEMP_DIR” ]; then
rm -rf “$TEMP_DIR”
echo “Temporary workspace removed successfully.”
fi
}
# 4. Bind the cleanup function to the EXIT signal
trap cleanup EXIT
# 5. Simulate deployment tasks
echo “Downloading application package…”
# (Simulated work inside $TEMP_DIR)
touch “$TEMP_DIR/app.tar.gz”
echo “Deploying application files…”
# If an error occurs here, ‘trap’ still executes cleanup() automatically!
# cp /nonexistent_file /var/www/html/
echo “Deployment completed successfully!”
Summary Checklist for Debugging and Error Handling
- [ ] Use bash -x script.sh to run scripts in execution trace mode, revealing variable expansions and command execution flow.
- [ ] Use inline set -x and set +x to toggle tracing dynamically around specific blocks of suspect code.
- [ ] Implement defensive programming by placing set -euo pipefail at the top of your scripts to catch errors, unbound variables, and silent pipeline failures.
- [ ] Use the trap command to intercept script exits and signals, ensuring automatic cleanup of temporary files and locks.
Congratulations! You have successfully completed Chapter 9. You have transformed your command-line expertise into automated script engineering, learning how to write, parameterize, control, and debug robust shell scripts.
Let’s review the core concepts and utilities you’ve mastered throughout this chapter:
- Script Anatomy & Execution (#!/bin/bash, chmod +x): Structuring scripts with proper shebang lines, understanding how the kernel interprets execution permissions, and executing files safely.
- Variables & User Input (read, $1, $2, $#): Assigning variables without whitespace errors, capturing command substitutions, prompting users interactively, and parsing command-line positional arguments.
- Control Flow (if, for, while): Implementing conditional branching based on command exit statuses and test operators, and automating repetitive tasks using for and while loops.
- Debugging & Error Handling (bash -x, set -euo pipefail, trap): Tracing execution logic with -x, enforcing defensive scripting standards with set -euo pipefail, and automating resource cleanup using signal traps.
You now possess a complete foundation in shell scripting automation.
Chapter 10: Advanced Productivity and Power Tools
Section 10.1: Archiving and Compression — tar, gzip, gunzip, zip, and unzip
Throughout Chapters 1 through 9, you have mastered file navigation, text filtering, user permissions, process monitoring, network diagnostics, secure remote administration, multi-distribution package management, shell environment customization, and robust shell scripting automation. You can build, secure, update, automate, and debug complex Linux infrastructure with complete confidence.
As you reach the final chapter of your Linux mastery, we turn our focus to Advanced Productivity and Power Tools—utilities designed to streamline your daily workflow, optimize storage, and handle complex file operations efficiently.
In this section, we begin Chapter 10 by examining Archiving and Compression. Whether you are backing up system configurations, bundling source code for distribution, or transferring massive datasets across remote servers, knowing how to efficiently archive multiple files into a single stream and compress them to minimize disk space is an indispensable skill for every system administrator.
Archiving vs. Compression: Understanding the Difference
Before executing commands, it is essential to distinguish between two distinct operations that are frequently confused:
- Archiving (tar): The process of combining multiple files, directory trees, file permissions, ownership metadata, and timestamp attributes into a single contiguous archive file. Archiving does not reduce file size; its purpose is organization and structural preservation.
- Compression (gzip, zip): The process of taking a file (or an archive) and running mathematical algorithms (such as DEFLATE) to eliminate redundancy and reduce the total file size in bytes on disk.
In traditional Unix environments, these two operations are combined: you first create an uncompressed archive using tar, and then compress that archive using a compression utility like gzip.
Part 1: Tape Archiving — The tar Command
The tar command (originally standing for Tape Archive, designed historically for writing data to magnetic tape drives) is the gold standard for archiving files and directories in Linux.
tar[options]archive_name.tar[file_or_directory_paths]
Why tar is Essential
Unlike simple file copying (cp), tar preserves critical filesystem metadata—including hard links, symbolic links, file ownership (UID/GID), access permissions, and modification timestamps—making it the ideal utility for system backups and migrations.
Essential Options and Flags for tar
Common`tar`OperationModes(MutuallyExclusive)
| Option | Flag Name | Description |
| -c, –create | Create Archive | Creates a new archive file from specified files and directories. |
| -x, –extract | Extract Archive | Extracts (unpacks) files and directories from an existing archive. |
| -t, –list | List Contents | Lists the contents of an archive without extracting them. |
Common`tar`ModifierFlags
| Option | Flag Name | Description |
| -f FILE, –file=FILE | Archive Filename | Specifies the filename of the archive to create or extract. (Always required) |
| -v, –verbose | Verbose Output | Prints every file name to the screen as it is archived or extracted. |
| -z, –gzip | Gzip Compression | Filters the archive through gzip, creating or reading .tar.gz / .tgz files. |
| -j, –bzip2 | Bzip2 Compression | Filters the archive through bzip2, creating or reading .tar.bz2 files. |
| -p, –preserve-permissions | Preserve Permissions | Preserves original file permissions and ownership bits strictly. |
Comprehensive Hands-on Practice & Examples (tar)
Example 1: Creating an Uncompressed Archive (tar -cvf)
Suppose you want to bundle a project directory named /var/www/html into an uncompressed archive named website_backup.tar:
tar -cvf website_backup.tar /var/www/html
Flags Breakdown: -c (create), -v (verbose listing of files being archived), -f (specify the output filename website_backup.tar).
Example 2: Creating a Compressed Gzip Archive (tar -czvf)
Because uncompressed .tar archives can be massive, administrators almost always compress them immediately using Gzip (-z):
tar -czvf project_backup.tar.gz ~/development/projects/
Expected Output:
home/alex/development/projects/
home/alex/development/projects/app.py
home/alex/development/projects/config.json
home/alex/development/projects/README.md
Example 3: Extracting an Archive (tar -xzvf)
When you need to restore files from a compressed tarball archive into your current working directory:
tar -xzvf project_backup.tar.gz
Flags Breakdown: -x (extract), -z (decompress gzip), -v (verbose output), -f (target archive file).
Extracting to a Specific Directory (-C)
If you want to extract the archive contents directly into a specific destination path (such as /var/www/) rather than your current working directory, use the -C flag:
sudo tar -xzvf website_backup.tar.gz -C /var/www/
Example 4: Listing Archive Contents Without Extracting (tar -tzvf)
If you receive a large archive file and want to inspect its internal file structure before extracting it to your disk:
tar -tzvf project_backup.tar.gz
Part 2: Compression Utilities — gzip, gunzip, bzip2, and bunzip2
While tar can invoke compression flags directly (-z for gzip, -j for bzip2), you will frequently encounter standalone compressed files on Linux systems.
1. The gzip and gunzip Commands
gzip (GNU Zip) is the most widely used compression utility in the Unix world. It compresses individual files using the Lempel-Ziv coding (LZ77) algorithm.
gzip[options]filename
Common`gzip`Options
- gzip filename: Compresses the file and replaces it with a new compressed file named filename.gz. The original uncompressed file is deleted.
- gzip -k filename: The –keep flag compresses the file while retaining the original uncompressed file on disk.
- gzip -9 filename: Applies maximum compression ratio (slower processing speed, smallest file size).
- gunzip filename.gz (or gzip -d): Decompresses a .gz file back to its original state.
Comprehensive Example (gzip)
# Compress a server log file while keeping the original
gzip -k /var/log/syslog
# Decompress the resulting syslog.gz file
gunzip /var/log/syslog.gz
Part 3: The Cross-Platform Standard — zip and unzip
While tar.gz is the undisputed standard for Linux-to-Linux administration, you will frequently need to exchange files with Windows users or unpack software archives downloaded from the web packaged in the ubiquitous .zip format.
In Linux, we use the zip and unzip command-line utilities to manage these archives.
zip[options]archive.zipfiles_to_include
unzip[options]archive.zip
Essential Options and Flags for zip and unzip
Common`zip`and`unzip`Options
| Command / Flag | Description |
| zip archive.zip file1 file2 | Creates a new .zip archive containing specified files. |
| zip -r archive.zip directory/ | Recursive Zip: Recursively compresses an entire directory tree into a .zip archive. |
| zip -e archive.zip file.txt | Encrypted Zip: Prompts for a secure password to encrypt the archive contents. |
| unzip archive.zip | Extracts all files from a .zip archive into the current directory. |
| unzip -l archive.zip | Lists the internal file contents of a .zip archive without extracting. |
| unzip archive.zip -d /target/ | Extracts archive contents into a specified target directory. |
Comprehensive Hands-on Practice & Examples (zip & unzip)
Example 1: Creating a Recursive Zip Archive (zip -r)
To bundle an entire project directory (my_website/) into a compressed .zip package:
zip -r website_archive.zip my_website/
Example 2: Creating a Password-Protected Encrypted Archive (zip -e)
If you need to archive sensitive configuration files or credentials before transmitting them across an insecure network, you can encrypt the archive with AES-256 encryption using the -e flag:
zip -e confidential_data.zip passwords.txt server_keys/
The terminal will prompt you to enter and confirm a password.
Example 3: Extracting Zip Archives (unzip)
To extract an archive into your current working directory:
unzip website_archive.zip
To extract it into a specific destination path (e.g., /var/www/html/):
unzip website_archive.zip -d /var/www/html/
Summary Checklist for Archiving and Compression
- [ ] Understand the fundamental difference between archiving (tar—combining files and preserving metadata) and compression (gzip, zip—reducing file size).
- [ ] Master creating compressed tarball archives using tar -czvf.
- [ ] Master extracting tarball archives using tar -xzvf, including target destination paths with -C.
- [ ] Use gzip -k to compress individual files while keeping the uncompressed originals, and gunzip to decompress them.
- [ ] Use zip -r to recursively archive directories into cross-platform .zip files and zip -e for password encryption.
- [ ] Use unzip to extract archives and -d to unpack files into precise target directories.
Section 10.2: Advanced Command-Line Construction and Text Manipulation — xargs, sed, and awk
Throughout Chapters 1 through 9, and into the previous section of Chapter 10, you have mastered an extensive array of Linux administration and power tools: file navigation, stream filtering, permissions, process monitoring, network diagnostics, remote administration, package management, shell scripting, and file archiving/compression.
However, as you tackle more complex data engineering, log auditing, and system administration workflows, you will encounter scenarios where standard pipes (|) fall short.
- What happens when a command (like rm, mkdir, or diff) expects a list of arguments as input, but your pipeline outputs those items as a continuous stream of standard input (stdin) rather than command-line parameters?
- How do you automatically search and replace configuration strings across dozens of files on disk without manually opening a text editor?
- How do you parse structured, tabular text columns (such as CSV logs, disk usage reports, or process tables) to perform calculations and filter data dynamically?
In this section, we examine the pinnacle of Unix command-line power: xargs for command-line construction, sed for stream editing, and awk for pattern scanning and data extraction.
Part 1: Building Command Lines from Standard Input — The xargs Command
To understand why xargs is indispensable, you must first understand the fundamental divide between standard input (stdin) and command-line arguments.
When you run a command like cat file.txt | grep “error”, grep is explicitly designed to read data piped into its standard input. However, many foundational utilities—such as rm (remove), cp (copy), chmod (change mode), and mkdir—do not read from standard input. They expect their targets to be passed as explicit arguments on the command line.
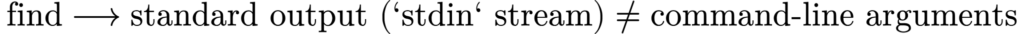
The xargs command bridges this gap. It reads items from standard input (separated by spaces, tabs, or newlines) and converts them into command-line arguments for a specified command.
Essential Options and Flags for xargs
Common`xargs`Options
| Option | Flag Name | Description |
| -n MAX, –max-args=MAX | Max Arguments | Limits the maximum number of arguments passed to each execution of the target command. |
| -I REPLACE, –replace=REPLACE | Replace String | Defines a placeholder string (e.g., {}) to position input items precisely within the target command. |
| -d CHAR, –delimiter=CHAR | Custom Delimiter | Specifies an input item delimiter character instead of whitespace or newlines. |
| -0, –null | Null Delimiter | Reads input items separated by a null character (\0), vital for safely handling filenames with spaces. |
| -p, –interactive | Interactive Prompt | Prompts the user for confirmation (y/N) before executing each generated command. |
| -P MAX, –max-procs=MAX | Parallel Execution | Runs multiple command processes simultaneously in parallel (great for performance). |
Comprehensive Hands-on Practice & Examples (xargs)
Example 1: Basic Argument Conversion (xargs)
Suppose you use find to locate all temporary .tmp files in a directory and want to delete them. If you pipe them directly without xargs, rm will fail because it receives no arguments.
find . -name “*.tmp” | xargs rm
How it works: find outputs a stream of filenames. xargs captures that stream and appends the filenames as arguments to rm, executing rm file1.tmp file2.tmp file3.tmp.
Example 2: Handling Filenames with Spaces Safely (-print0 and xargs -0)
Filenames in Linux can legally contain spaces, tabs, and newlines. A naive pipeline (find … | xargs) will break if a filename contains a space (e.g., my document.tmp will be split into two separate arguments: my and document.tmp).
To solve this, use null-terminated strings (-print0) paired with xargs -0:
find . -name “*.tmp” -print0 | xargs -0 rm
-0: Tells xargs that items are separated by null bytes rather than whitespace, ensuring absolute safety with complex filenames.
Example 3: Positioning Arguments with Replacement Strings (xargs -I {})
By default, xargs appends arguments to the end of the target command. If you need to insert the argument into the middle or multiple times within a command, use the -I replacement flag.
Suppose you want to back up a list of configuration files by copying each one into a backup/ directory:
ls *.conf | xargs -I {} cp {} backup/{}.bak
{}: Acts as a placeholder token. For every filename piped into xargs, {} is replaced by that filename, generating cp nginx.conf backup/nginx.conf.bak.
Example 4: Parallel Processing (xargs -P)
If you are processing hundreds of media files, compressing archives, or pinging servers, running tasks sequentially is slow. You can run tasks in parallel using the -P flag:
cat server_list.txt | xargs -P 4 -n 1 ping -c 1
-P 4: Spawns up to 4 concurrent child processes simultaneously, dramatically accelerating batch execution.
Part 2: Stream Editing — The sed Command
Once you can construct commands dynamically using xargs, the next challenge in text processing is modifying text streams on the fly without altering the source files manually.
The sed command (short for Stream Editor) is a powerful utility designed to parse, filter, transform, and edit text streams line by line.
sed[options]’script'[input_file]
How sed Works Under the Hood
- sed reads an input stream line by line.
- It copies each line into an internal temporary memory buffer known as the Pattern Space.
- It applies your editing instructions (substitution, deletion, insertion) to the pattern space.
- It prints the modified pattern space to standard output (stdout) and moves to the next line.
Essential Options and Flags for sed
Common`sed`OptionsandModifiers
| Option / Modifier | Description |
| -n, –quiet, –silent | Suppresses automatic printing of pattern space; only prints lines explicitly requested via the p print command. |
| -i, –in-place | In-Place Editing: Modifies and saves changes directly to the source file on disk rather than printing to stdout. |
| -e SCRIPT, –expression | Allows chaining multiple editing scripts or commands in a single execution. |
| s/pattern/replacement/ | Substitute Command: Replaces occurrences of pattern with replacement. |
| g (Global Modifier) | Replaces every match on a line, rather than stopping after the first match. |
| d (Delete Command) | Deletes specified lines from the output stream. |
Comprehensive Hands-on Practice & Examples (sed)
Example 1: Basic Substitution (sed ‘s/old/new/’)
To replace the first occurrence of the word “localhost” with “production-db” in a configuration file:
sed ‘s/localhost/production-db/’ config.cfg
Example 2: Global Substitution (sed ‘s/…/…/g’)
By default, sed replaces only the first match on any given line. To replace every instance across the entire line, append the g (global) flag:
sed ‘s/error/WARNING/g’ /var/log/syslog
Example 3: In-Place File Editing (sed -i)
⚠️ Caution: By default, sed outputs transformed text to your terminal screen, leaving the original file untouched. To overwrite the original file directly on disk, use the -i flag:
sed -i ‘s/debug_mode = true/debug_mode = false/g’ /etc/app/settings.conf
Best Practice: When performing risky in-place edits on critical system configuration files, you can automatically create a backup of the original file by appending an extension to -i:
sed -i.bak ‘s/port = 80/port = 443/g’ /etc/nginx/nginx.conf
(This modifies nginx.conf in place while saving a pristine backup copy as nginx.conf.bak).
Example 4: Deleting Specific Lines (sed ‘d’)
You can use sed to delete lines based on line numbers or pattern matching:
- Delete line 5:
- Bash
sed ‘5d’ file.txt
Delete all blank lines:- Bash
sed ‘/^$/d’ file.txt
Part 3: Pattern Scanning and Processing Language — The awk Command
While sed is a brilliant stream editor for line-by-line substitutions and deletions, it lacks advanced programming constructs, arithmetic capabilities, and column-based data parsing.
When you need to process structured, tabular data (such as CSV files, tabular process lists, or log files organized into columns), the definitive tool is awk (named after its creators: Alfred Aho, Peter Weinberger, and Brian Kernighan).
awk is not merely a filter; it is a full-fledged, programmable pattern scanning and data processing language.
awk[options]’pattern{action}'[input_file]
How awk Processes Text: Records and Fields
awk views text files through a structured, database-like lens:
- Record (NR): By default, every line in a file is treated as a separate record. awk processes records one by one in a loop.
- Field ($1,$2,$3…): Within each record, awk automatically splits the line into individual columns (words) separated by whitespace (spaces or tabs).
- $0: Represents the entire current line.
- $1: Represents the first column.
- $2: Represents the second column.
- $NF: Represents the last column in the record (where NF stands for Number of Fields).
- $0: Represents the entire current line.
Built-in Variables in awk
Common`awk`Built-inVariables
| Variable | Description |
| NR | Number of Record: The current line number being processed (1, 2, 3…). |
| NF | Number of Fields: The total count of columns/words found in the current record. |
| FS | Field Separator: Defines the input delimiter (defaults to whitespace; can be set to commas : or ,). |
| OFS | Output Field Separator: Defines the delimiter used when printing columns. |
Comprehensive Hands-on Practice & Examples (awk)
Example 1: Printing Specific Columns (awk ‘{print …}’)
Suppose you want to inspect system users by reading /etc/passwd. /etc/passwd is a colon-separated file where the username is column 1 and the default shell is column 7.
To print just the username and shell:
awk -F: ‘{print “User:”, $1, “\tShell:”, $7}’ /etc/passwd
-F:: Sets the Field Separator (FS) to a colon (:) instead of whitespace.- $1 and $7: Extracts the first and seventh columns.
Expected Output (Truncated):
User: root Shell: /bin/bash
User: daemon Shell: /usr/sbin/nologin
User: alex Shell: /bin/bash
Example 2: Conditional Row Filtering in awk
You can apply conditions inside awk to process only rows matching specific criteria.
Suppose you want to parse the output of df -h (disk filesystem usage) and print only filesystems where disk usage exceeds 80%:
df -h | awk ‘NR > 1 {print $1, $5, $6}’
NR > 1: Skips the header row (NR == 1).- $5: Represents the percentage used column (e.g., 85%).
Example 3: Arithmetic Calculations and Variables in awk
Because awk is a programming language, you can perform math on columns directly inside your stream processing pipeline.
Suppose you have a log file of server request sizes in bytes (sizes.txt) and want to sum them up or calculate averages:
awk ‘{sum += $1} END {print “Total Sum of Bytes:”, sum}’ sizes.txt
sum += $1: Accumulates the numerical value of column 1 across every line.- END { … }: A special block executed after awk has finished reading every line of the file, printing the final aggregated total.
Summary Checklist for Advanced Tech Manipulation
- [ ] Use xargs to convert standard input streams (stdin) into command-line arguments for utilities that do not read pipes natively.
- [ ] Master null-terminated streams (find -print0 | xargs -0) to handle filenames containing spaces safely.
- [ ] Use xargs -I {} for custom argument placement and -P for parallel task execution.
- [ ] Use sed for lightning-fast stream editing, substitutions (s/old/new/g), and in-place file modifications (sed -i).
- [ ] Leverage awk as a programmable pattern scanning language to extract columns ($1, $2, $NF), set custom field separators (-F), and perform arithmetic text analytics.
Section 10.3: Session Management and Persistence — screen and tmux
Throughout Chapter 10, you have mastered advanced power tools: archiving and compressing file trees with tar, gzip, and zip, constructing dynamic command lines using xargs, editing streams with sed, and parsing tabular data with awk. You can manipulate data and manage storage with surgical precision.
However, as a system administrator or DevOps engineer, you will frequently initiate long-running operations across remote servers accessed via SSH—such as compiling large software packages from source, executing massive database migrations, mirroring multi-terabyte filesystems, or training machine learning models.
- What happens when your laptop battery dies, your local Wi-Fi drops, or your SSH connection times out halfway through a six-hour remote database backup?
- By default, when an SSH session disconnects, the Linux kernel sends a SIGHUP (Hangup) signal to every process associated with that pseudo-terminal, instantly terminating your running jobs and interrupting critical workflows.
In this section, we examine Session Management and Terminal Multiplexers—specifically screen and the modern standard tmux—which allow you to detach terminal sessions, leave processes running safely in the background on remote servers, and reattach to them seamlessly across disconnections.
The Architecture of Terminal Persistence
To understand why multiplexers solve the disconnection problem, you must understand how terminal sessions operate:
- Standard SSH Session: Your SSH client connects to a remote shell process. That shell acts as the parent process controlling your interactive terminal. If the network drops, the parent shell dies, broadcasting SIGHUP down to all child processes.
- Terminal Multiplexer (screen / tmux): A multiplexer runs as an independent daemon process detached from any single physical terminal window. When you launch a multiplexer, it creates a persistent virtual session container. Your shell and commands run inside this container. If your SSH connection drops, the virtual session remains active and running uninterrupted on the remote server’s background. You can log back in hours later and reattach to the exact same session, picking up right where you left off.
Part 1: The Classic Standard — GNU Screen (screen)
GNU Screen is the veteran terminal multiplexer found pre-installed on virtually every enterprise Linux distribution (RHEL, CentOS, Fedora, Debian, Ubuntu, and Arch Linux). While newer tools exist, screen remains an essential fallback utility for headless server rescue and emergency administration.
screen[options][arguments]
Essential Screen Commands and Options
GNUScreenReference
| Command / Flag | Description |
| screen | Starts a new default screen session. |
| screen -S session_name | Starts a new screen session with a custom, descriptive name. |
| screen -ls | Lists all active, detached, and running screen sessions on the server. |
| screen -r session_name | Reconnects (reattaches) to a detached screen session. |
| screen -d session_name | Remotely detaches a running screen session from another terminal window. |
Core Screen Keyboard Shortcuts
Once you are inside a screen session, all keyboard inputs are captured by your virtual terminal except for the Command Character Prefix: Ctrl + A.
To issue a command to screen itself, you must first press Ctrl + A, release both keys, and then press the command letter.
ScreenShortcutReference
| Shortcut Sequence | Description |
| Ctrl + A then d | Detach: Detaches from the active screen session, returning you to your normal shell while leaving jobs running safely in the background. |
| Ctrl + A then c | Create: Opens a new virtual terminal window inside your current screen session. |
| Ctrl + A then n | Next: Switches to the next open window in your session. |
| Ctrl + A then p | Previous: Switches to the previous window in your session. |
| Ctrl + A then k | Kill: Terminates (closes) the current active window and its running process. |
Comprehensive Hands-on Practice (screen)
Example 1: Launching a Named Screen Session
When starting a long-running administrative task (such as a large database dump), launch it inside a named screen session so you can easily identify it later:
screen -S database_backup
Your terminal screen will flash or clear briefly, presenting you with a standard shell prompt running securely inside the new screen container.
Now, execute your long-running job:
pg_dump -U postgres enterprise_db > /var/backups/enterprise_db_dump.sql
Example 2: Detaching from the Session
While the database backup is running, you can safely walk away or close your terminal window by pressing:
Ctrl+Athend
Expected Output:
[detached from 12345.database_backup]
You are now back in your standard local SSH shell. The database backup continues running uninterrupted in the background on the remote server.
Example 3: Listing and Reattaching to Sessions
Hours later, or after reconnecting via a new SSH session, check your active screen sessions:
screen -ls
Expected Output:
There is a screen on:
12345.database_backup (Detached)
1 socket in /var/run/screen/S-alex.
To reattach to the backup session and monitor its progress:
screen -r database_backup
The session instantly restores onto your display, showing real-time progress.
Part 2: The Modern Standard — Tmux (tmux)
While screen is robust and ubiquitous, tmux (Terminal Multiplexer) was engineered from the ground up as a modern, highly extensible, and feature-rich successor.
tmux introduces a cleaner architecture, superior window and pane splitting, intuitive status bars, and robust configuration flexibility, making it the default choice for modern DevOps engineers and systems administrators.
tmux[command][options]
Tmux Architecture Terminology
- Session: An independent workspace containing one or more windows. You can detach and reattach sessions freely.
- Window: Equivalent to tabs in a modern web browser; each window fills your terminal screen.
- Pane: Splits a single window into multiple simultaneous, independent terminal views side-by-side or stacked vertically.
Essential Tmux Commands
TmuxCommand-LineReference
| Command | Description |
| tmux | Starts a new default tmux session. |
| tmux new -s session_name | Starts a new tmux session with a custom, human-readable name. |
| tmux ls | Lists all active tmux sessions currently running on the server. |
| tmux attach -t session_name | Reattaches to a running tmux session (shortcut: tmux a -t session_name). |
| tmux kill-session -t session_name | Completely terminates a specific tmux session and all processes running inside it. |
Tmux Prefix and Key Bindings
Just like screen, tmux uses a command prefix to capture instructions. By default, the Tmux prefix is Ctrl + B.
TmuxShortcutReference
| Shortcut Sequence | Description |
| Ctrl + B then d | Detach: Detaches from the current session, leaving it running in the background. |
| Ctrl + B then % | Split Pane Vertically: Splits the current window into two side-by-side terminal panes. |
| Ctrl + B then “ | Split Pane Horizontally: Splits the current window into two stacked top-and-bottom panes. |
| Ctrl + B then Arrow Keys | Navigate Panes: Moves active keyboard focus between panes. |
| Ctrl + B then c | Create Window: Opens a new window inside the session. |
| Ctrl + B then n / p | Switch Windows: Cycles to the next (n) or previous (p) window. |
| Ctrl + B then x | Kill Pane: Closes the active pane. |
Comprehensive Hands-on Practice (tmux)
Example 1: Creating a Named Tmux Session
To start a new session named sysadmin_ops:
tmux new -s sysadmin_ops
Notice the clean, elegant status bar at the bottom of your terminal displaying the session name, active windows, hostname, and current system timestamp.
Example 2: Splitting Panes for Simultaneous Monitoring
Suppose you are debugging an application and want to tail system logs in one pane while running commands in another:
- Split your terminal window vertically by pressing:
- In the new right pane, start tailing your log file:
- Bash
tail -f /var/log/nginx/access.log
Switch focus back to the left pane by pressing:- Ctrl+BthenLeft Arrow
- Run your application commands freely in the left pane without losing sight of real-time log output on the right.
Example 3: Detaching and Reattaching
To detach from your Tmux session and return to your parent shell:
Ctrl+Bthend
To list your running sessions later:
tmux ls
Expected Output:
sysadmin_ops: 1 windows (created Sun Nov 8 10:20:00 2026) [120×30]
To reattach to your session:
tmux attach -t sysadmin_ops
Part 3: Comparison — screen vs. tmux
Screenvs.TmuxFeatureComparison
| Feature | GNU Screen (screen) | Tmux (tmux) |
| Development Status | Mature, stable, but largely in maintenance mode. | Actively developed, modern feature set. |
| Command Prefix | Ctrl + A | Ctrl + B (easily reconfigured in ~/.tmux.conf). |
| Pane Management | Rigid vertical splitting; complex manipulation. | Fluid, intuitive vertical and horizontal pane splitting. |
| Status Bar | Minimalist; requires manual configuration. | Highly customizable, informative status bar built-in by default. |
| Scriptability | Limited command-line scripting interface. | Powerful programmatic control via shell commands and configuration files. |
Summary Checklist for Session Management
- [ ] Understand the SSH disconnection problem: how network drops send SIGHUP signals that terminate unmanaged child processes.
- [ ] Use terminal multiplexers (screen or tmux) to create persistent virtual session containers decoupled from physical SSH terminals.
- [ ] Master GNU Screen basics: screen -S (start named session), Ctrl + A, d (detach), screen -ls (list), and screen -r (reattach).
- [ ] Master Tmux basics: tmux new -s (start session), Ctrl + B, d (detach), tmux ls (list), and tmux attach -t (reattach).
- [ ] Utilize Tmux advanced pane splitting (Ctrl + B, % and Ctrl + B, “) for simultaneous multi-tasking and real-time log monitoring.
Congratulations! You have successfully completed Chapter 10—and with it, your comprehensive journey through the Linux command line. You have mastered the advanced power tools, workflow speedups, and session management techniques that separate proficient administrators from true power users.
Let’s review the core concepts and utilities you’ve mastered throughout this final chapter:
- Archiving and Compression (tar, gzip, zip, unzip): Combining file trees while preserving ownership and permission metadata with tar, managing efficient file compression via gzip, and handling cross-platform .zip and password-encrypted archives.
- Advanced Command-Line Construction and Text Manipulation (xargs, sed, awk): Bridging standard input streams into command-line arguments safely with xargs, executing stream edits and substitutions with sed, and parsing structured tabular data using the programmable scanning and extraction power of awk.
- Session Management and Persistence (screen, tmux): Defending long-running administrative processes against network drops and SSH disconnections by utilizing virtual session containers, detachable windows, and multi-pane multiplexing with GNU Screen and modern tmux.
You now possess a complete, professional-grade mastery of the Linux command line, from basic file navigation and shell scripting to advanced systems administration and productivity tooling.
Appendix: Quick Reference Cheat Sheet
This appendix provides a comprehensive, alphabetical reference of the Linux commands covered across the chapters of this book. Use this list for rapid syntax lookup, flag verification, and operational guidance.
A
- alias — Creates short commands or shortcuts for longer command strings.
- Syntax: alias name=’command’
- Example: alias ll=’ls -lah –color=auto’
- Syntax: alias name=’command’
- apt — High-level package management tool for Debian/Ubuntu systems.
- Syntax: apt [command] [package]
- Example: sudo apt update && sudo apt install -y nginx
- Syntax: apt [command] [package]
- awk — Pattern scanning and tabular data processing language.
- Syntax: awk ‘[pattern] {action}’ file
- Example: awk -F: ‘{print $1, $7}’ /etc/passwd
- Syntax: awk ‘[pattern] {action}’ file
B
- bash — The GNU Bourne-Again SHell command interpreter.
- Syntax: bash [options] [script_file]
- Example: bash -x script.sh
- Syntax: bash [options] [script_file]
- bunzip2 — Decompresses files compressed with bzip2.
- Syntax: bunzip2 file.bz2
- Syntax: bunzip2 file.bz2
- bzip2 — High-ratio block-sorting file compressor.
- Syntax: bzip2 file
- Syntax: bzip2 file
C
- cat — Concatenates and displays file contents on standard output.
- Syntax: cat [options] file
- Syntax: cat [options] file
- cd — Changes the current working directory.
- Syntax: cd [directory_path]
- Example: cd “$HOME/.config”
- Syntax: cd [directory_path]
- chmod — Modifies file and directory permissions mode bits.
- Syntax: chmod [permissions] file
- Example: chmod +x script.sh
- Syntax: chmod [permissions] file
- chown — Changes file owner and group ownership.
- Syntax: chown user:group file
- Syntax: chown user:group file
- cp — Copies files and directories across the filesystem.
- Syntax: cp [options] source destination
- Example: cp -r /etc/nginx ./backup/
- Syntax: cp [options] source destination
- curl — Transfers data to or from a network server using supported protocols.
- Syntax: curl [options] URL
- Example: curl -O [https://example.com/file.tar.gz](https://example.com/file.tar.gz)
- Syntax: curl [options] URL
D
- date — Displays or sets the system date and time.
- Syntax: date [+”format”]
- Syntax: date [+”format”]
- dd — Converts and copies low-level raw image data.
- Syntax: dd if=input_file of=output_file [options]
- Syntax: dd if=input_file of=output_file [options]
- df — Reports file system disk space usage.
- Syntax: df -h
- Syntax: df -h
- dig — Domain Information Groper for DNS lookup diagnostics.
- Syntax: dig [domain]
- Syntax: dig [domain]
- dnf — Modern package manager for Red Hat, Fedora, and RHEL-based distributions.
- Syntax: dnf [command] [package]
- Example: sudo dnf install -y git
- Syntax: dnf [command] [package]
- dpkg — Low-level Debian package manager utility.
- Syntax: dpkg [options] package.deb
- Example: sudo dpkg -i package.deb
- Syntax: dpkg [options] package.deb
- du — Estimates file and directory space usage.
- Syntax: du -sh /path/to/dir
- Syntax: du -sh /path/to/dir
E
- echo — Prints strings or expanded variables to standard output.
- Syntax: echo “text or $VARIABLE”
- Syntax: echo “text or $VARIABLE”
- env — Displays active environment variables or runs a program in a modified environment.
- Syntax: env
- Syntax: env
- export — Exports local shell variables into inherited environment variables for child processes.
- Syntax: export VARIABLE=”value”
- Example: export PATH=”HOME/bin:PATH”
- Syntax: export VARIABLE=”value”
F
- find — Searches directory trees recursively for files matching criteria.
- Syntax: find [path] [expression]
- Example: find . -name “*.tmp” -print0
- Syntax: find [path] [expression]
- flatpak — Builds, manages, and executes containerized desktop applications.
- Syntax: flatpak [command] [application]
- Example: flatpak install flathub org.gimp.GIMP
- Syntax: flatpak [command] [application]
G
- grep — Searches text patterns using regular expressions.
- Syntax: grep [options] “pattern” file
- Example: grep -rn “ERROR” /var/log/
- Syntax: grep [options] “pattern” file
- gunzip — Decompresses files compressed with gzip.
- Syntax: gunzip file.gz
- Syntax: gunzip file.gz
- gzip — Compresses files using Lempel-Ziv (LZ77) coding.
- Syntax: gzip [options] file
- Example: gzip -k logfile.log
- Syntax: gzip [options] file
H
- head — Outputs the first part (default 10 lines) of files.
- Syntax: head -n 20 file.txt
- Syntax: head -n 20 file.txt
- history — Displays command history list or recalls previous executions.
- Syntax: history [number]
- Syntax: history [number]
I
- ip — Network interface and routing manipulation utility.
- Syntax: ip [object] [command]
- Example: ip addr show
- Syntax: ip [object] [command]
K
- kill — Sends termination signals to running processes by Process ID (PID).
- Syntax: kill -[signal] PID
- Example: kill -9 1234
- Syntax: kill -[signal] PID
- killall — Sends termination signals to processes by binary name.
- Syntax: killall process_name
- Syntax: killall process_name
L
- ln — Creates hard or symbolic links between files.
- Syntax: ln -s target link_name
- Syntax: ln -s target link_name
- ls — Lists directory contents.
- Syntax: ls [options] [path]
- Example: ls -lah
- Syntax: ls [options] [path]
- lsof — Lists open files and the processes that opened them.
- Syntax: lsof -i :80
- Syntax: lsof -i :80
M
- mkdir — Creates new directories.
- Syntax: mkdir -p /path/to/directory
- Syntax: mkdir -p /path/to/directory
- mount — Mounts a storage filesystem to a directory node.
- Syntax: mount /dev/sdX /mnt/target
- Syntax: mount /dev/sdX /mnt/target
- mv — Moves or renames files and directories.
- Syntax: mv source destination
- Syntax: mv source destination
N
- netstat — Displays network connections, routing tables, and interface statistics (legacy).
- Syntax: netstat -tulpn
- Syntax: netstat -tulpn
P
- pacman — Package manager utility for Arch Linux distributions.
- Syntax: pacman <operation> [options] [package]
- Example: sudo pacman -Syu
- Syntax: pacman <operation> [options] [package]
- ping — Sends ICMP ECHO_REQUEST packets to network hosts.
- Syntax: ping -c 4 host
- Syntax: ping -c 4 host
- ps — Reports a snapshot of active processes.
- Syntax: ps aux
- Syntax: ps aux
- printenv — Prints specified or all environment variables.
- Syntax: printenv [VARIABLE]
- Syntax: printenv [VARIABLE]
- pwd — Prints current working directory path.
- Syntax: pwd
- Syntax: pwd
R
- read — Reads input lines from standard input into shell variables.
- Syntax: read -p “Prompt: ” VARIABLE
- Syntax: read -p “Prompt: ” VARIABLE
- rm — Removes files or directory trees.
- Syntax: rm -rf /path/to/target
- Syntax: rm -rf /path/to/target
- rmdir — Removes empty directories.
- Syntax: rmdir directory
- Syntax: rmdir directory
- rpm — Low-level Red Hat Package Manager utility.
- Syntax: rpm [options] package.rpm
- Example: sudo rpm -ivh package.rpm
- Syntax: rpm [options] package.rpm
- rsync — Efficient remote and local file synchronization utility.
- Syntax: rsync -avz source/ destination/
- Syntax: rsync -avz source/ destination/
S
- scp — Securely copies files over an encrypted SSH connection.
- Syntax: scp source user@host:/path
- Syntax: scp source user@host:/path
- screen — Terminal multiplexer for persistent virtual sessions.
- Syntax: screen -S session_name
- Syntax: screen -S session_name
- sed — Stream editor for filtering and transforming text streams.
- Syntax: sed ‘s/search/replace/g’ file
- Example: sed -i ‘s/80/443/g’ config.conf
- Syntax: sed ‘s/search/replace/g’ file
- snap — Manages cross-distro Snap container packages.
- Syntax: snap [command] [package]
- Example: sudo snap install –classic code
- Syntax: snap [command] [package]
- source — Executes commands from a file within the current shell context.
- Syntax: source ~/.bashrc
- Syntax: source ~/.bashrc
- ss — Utility to investigate network sockets (modern replacement for netstat).
- Syntax: ss -tulpn
- Syntax: ss -tulpn
- ssh — Secure Shell client for remote terminal access.
- Syntax: ssh user@hostname
- Syntax: ssh user@hostname
- sudo — Executes commands with elevated or superuser privileges.
- Syntax: sudo command
- Syntax: sudo command
T
- tail — Outputs the final part of files or monitors logs live.
- Syntax: tail -f /var/log/syslog
- Syntax: tail -f /var/log/syslog
- tar — Tape archiving utility for bundling and extracting archive files.
- Syntax: tar [options] archive.tar.gz /path
- Example: tar -czvf backup.tar.gz /var/www/
- Syntax: tar [options] archive.tar.gz /path
- tmux — Modern terminal multiplexer with window/pane splitting and persistence.
- Syntax: tmux new -s session_name
- Syntax: tmux new -s session_name
- top — Displays real-time system process resource usage.
- Syntax: top
- Syntax: top
- touch — Changes file timestamps or creates empty files.
- Syntax: touch filename
- Syntax: touch filename
- traceroute — Traces the network packet route to a remote host.
- Syntax: traceroute domain
- Syntax: traceroute domain
- trap — Intercepts OS signals and executes specified cleanup actions.
- Syntax: trap ‘command’ SIGNAL
- Syntax: trap ‘command’ SIGNAL
U
- umount — Unmounts mounted filesystems from directory nodes.
- Syntax: umount /mnt/target
- Syntax: umount /mnt/target
- unalias — Removes active aliases defined in the current shell session.
- Syntax: unalias alias_name
- Syntax: unalias alias_name
- uname — Prints system and operating system kernel information.
- Syntax: uname -a
- Syntax: uname -a
- unzip — Extracts compressed .zip archives.
- Syntax: unzip archive.zip -d /target/
- Syntax: unzip archive.zip -d /target/
W
- wget — Non-interactive network downloader for HTTP, HTTPS, and FTP.
- Syntax: wget [options] URL
- Syntax: wget [options] URL
- which — Shows the full path of executable commands found in $PATH.
- Syntax: which command_name
- Syntax: which command_name
- while — Executes code repeatedly as long as a condition remains true.
- Syntax: while [ condition ]; do … done
- Syntax: while [ condition ]; do … done
X
- xargs — Builds and executes command lines from standard input streams.
- Syntax: command | xargs [target_command]
- Example: find . -name “*.tmp” -print0 | xargs -0 rm
- Syntax: command | xargs [target_command]
Y
- yum — Legacy high-level package manager for RHEL/CentOS systems.
- Syntax: yum [command] [package]
- Syntax: yum [command] [package]
- zip — Packages and compresses files into .zip archives.
- Syntax: zip -r archive.zip directory/
Source Bibliography and Reference Documentation
This bibliography compiles the canonical documentation, official project repositories, and technical specifications referenced throughout the creation of this book. These resources serve as foundational reading for deep-dive Linux administration, systems engineering, and shell scripting.
Official GNU and Core Utilities Documentation
- GNU Coreutils Manual
- Description: The definitive reference manual for standard GNU file, shell, and text manipulation utilities (ls, cp, mv, rm, cat, date, touch).
- Description: The definitive reference manual for standard GNU file, shell, and text manipulation utilities (ls, cp, mv, rm, cat, date, touch).
- GNU Bash Reference Manual
- Description: Comprehensive documentation covering Bash syntax, environment variables, parameter expansion, arithmetic evaluation, control flow constructs, and execution debugging flags (-x).
- Description: Comprehensive documentation covering Bash syntax, environment variables, parameter expansion, arithmetic evaluation, control flow constructs, and execution debugging flags (-x).
- Gawk: Effective AWK Programming Manual
- Description: The authoritative guide to GNU awk, detailing pattern scanning, field separators, associative arrays, and tabular data transformation.
- Description: The authoritative guide to GNU awk, detailing pattern scanning, field separators, associative arrays, and tabular data transformation.
- GNU Screen Manual
- Description: Official user manual for GNU Screen, detailing virtual terminal sessions, window management, and background detachment.
- Description: Official user manual for GNU Screen, detailing virtual terminal sessions, window management, and background detachment.
Operating System & Distribution Documentation
- Arch Wiki
- Description: Widely regarded as the gold standard of technical Linux documentation. Used extensively for architectural insights into pacman, system initialization, rolling-release models, and package databases.
- Description: Widely regarded as the gold standard of technical Linux documentation. Used extensively for architectural insights into pacman, system initialization, rolling-release models, and package databases.
- Debian Policy Manual & Documentation
- Description: Official specifications governing the structure of Debian packages (.deb), low-level maintenance via dpkg, and high-level dependency resolution through apt.
- Description: Official specifications governing the structure of Debian packages (.deb), low-level maintenance via dpkg, and high-level dependency resolution through apt.
- Red Hat Enterprise Linux Documentation Hub
- Description: Official enterprise manuals detailing RPM package management (rpm), modern transactional package updates (dnf), EPEL repositories, and system configuration for RHEL and Fedora.
- Description: Official enterprise manuals detailing RPM package management (rpm), modern transactional package updates (dnf), EPEL repositories, and system configuration for RHEL and Fedora.
- The Linux Kernel Archives
- Description: Core architectural standards, kernel release notes, and documentation regarding system calls, process namespaces, and hardware interaction.
- Description: Core architectural standards, kernel release notes, and documentation regarding system calls, process namespaces, and hardware interaction.
Universal Packaging & Containerization
- Flatpak Documentation
- Description: Comprehensive architecture guides covering decentralized repositories (Flathub), shared runtimes, and bubblewrap (bwrap) sandboxing for desktop applications.
- Description: Comprehensive architecture guides covering decentralized repositories (Flathub), shared runtimes, and bubblewrap (bwrap) sandboxing for desktop applications.
- Snapcraft Documentation & Developer Guide
- Description: Official documentation for Canonical’s Snap universal packaging system, SquashFS mounting, snapd daemons, and strict vs. classic confinement levels.
- Description: Official documentation for Canonical’s Snap universal packaging system, SquashFS mounting, snapd daemons, and strict vs. classic confinement levels.
POSIX Standards & Technical Specifications
- The Open Group Base Specifications (IEEE Std 1003.1 / POSIX)
- Description: The foundational international standard for Unix operating systems, defining shell command behaviors, exit statuses, environment variable inheritance, and utility interfaces.
- Description: The foundational international standard for Unix operating systems, defining shell command behaviors, exit statuses, environment variable inheritance, and utility interfaces.
- Tmux Official Repository and Wiki
- Description: Upstream documentation, configuration guides, and shortcut references for the modern terminal multiplexer tmux.